Mac mini M6 Without a Subscription: Voice Cloning, Music and Transcription, 8 Local AIs vs Paid
Posted Video released
On a Mac mini M6 32GB we tested eight local AIs for voice cloning, music and transcription against paid services: VoxCPM2 similarity 0.918, Suno lyric error 2.3%, Whisper error 3.6%.
How far can you get with voice cloning, music composition, and transcription on a single Mac mini M6 32GB, with no subscription? We compared eight local AI tools against two paid cloud services (voice cloning and Suno) using the same sentence and the same lyrics. Voice cloning sounded closer to the original locally, lyric clarity in songs was better with paid Suno, and Whisper large-v3 was the most accurate at transcription. This post rewrites the content of our YouTube video as an article.
Conclusions first
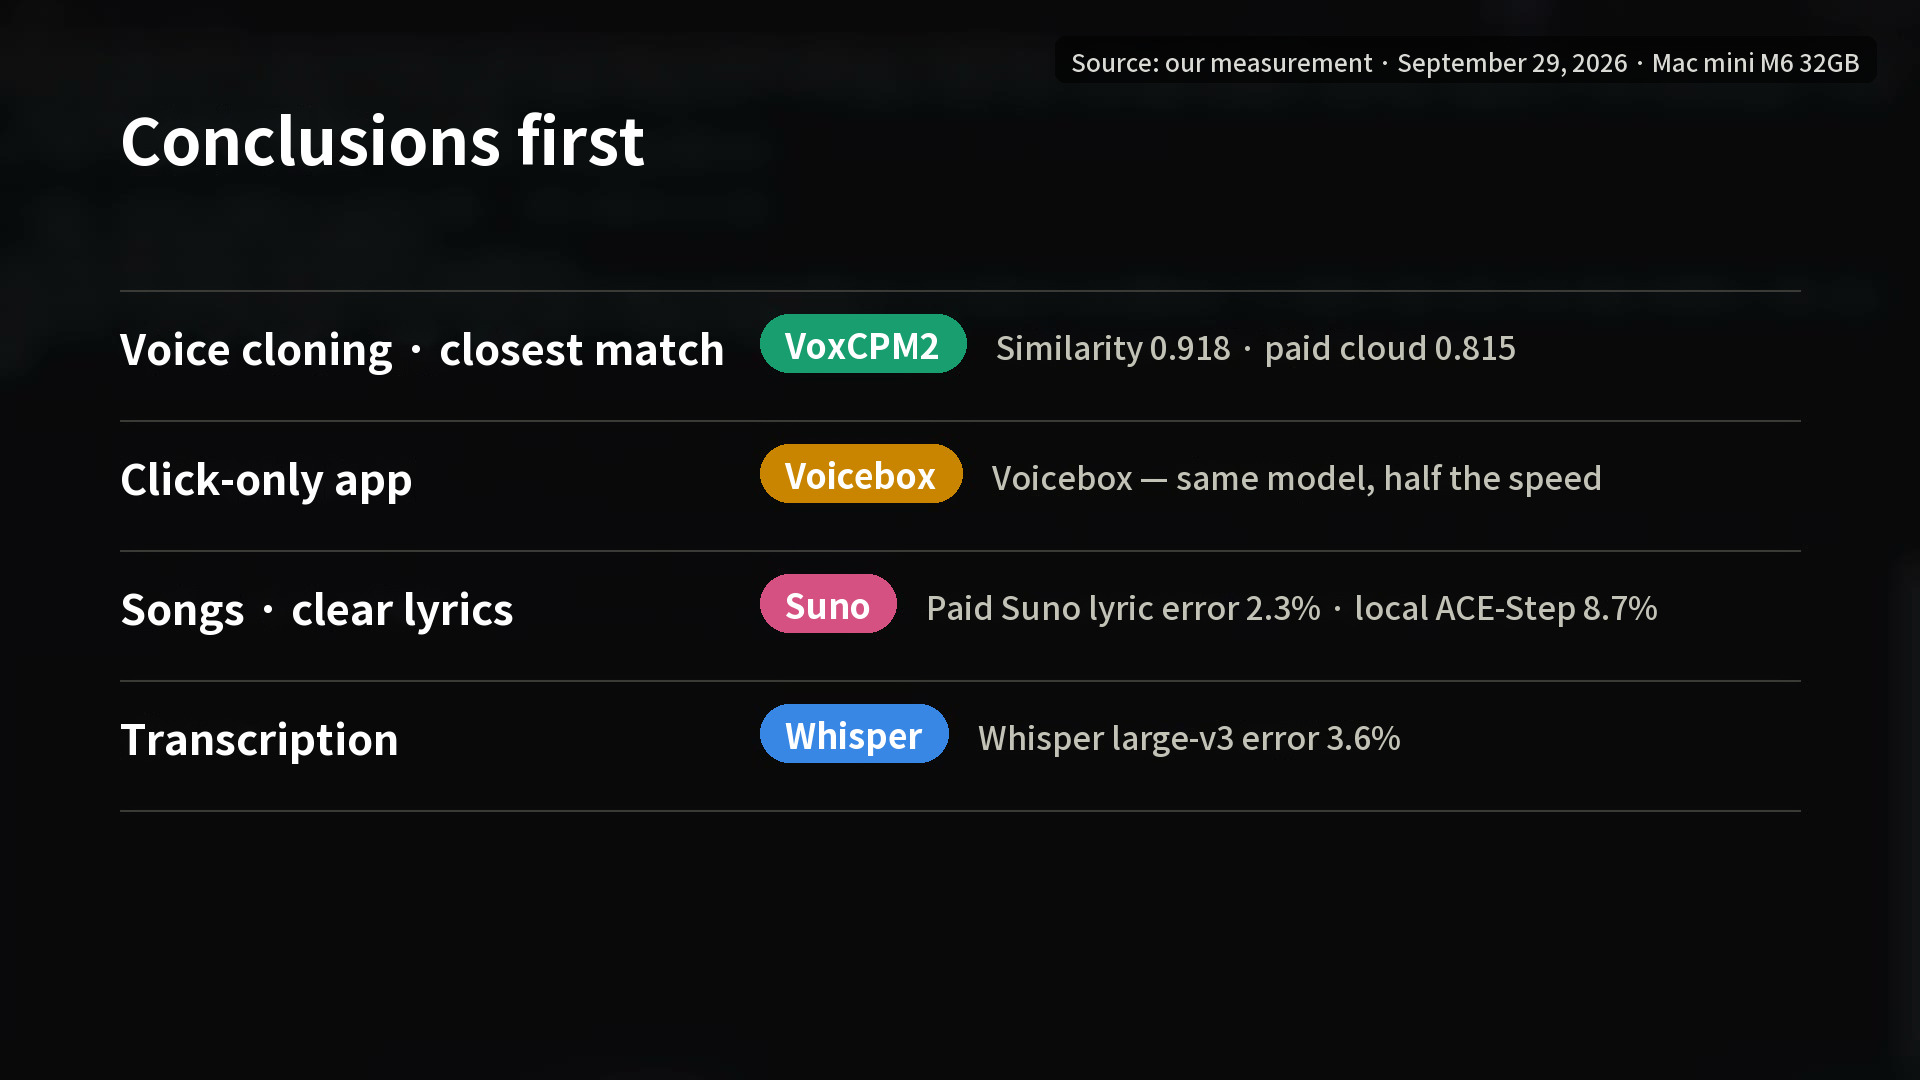
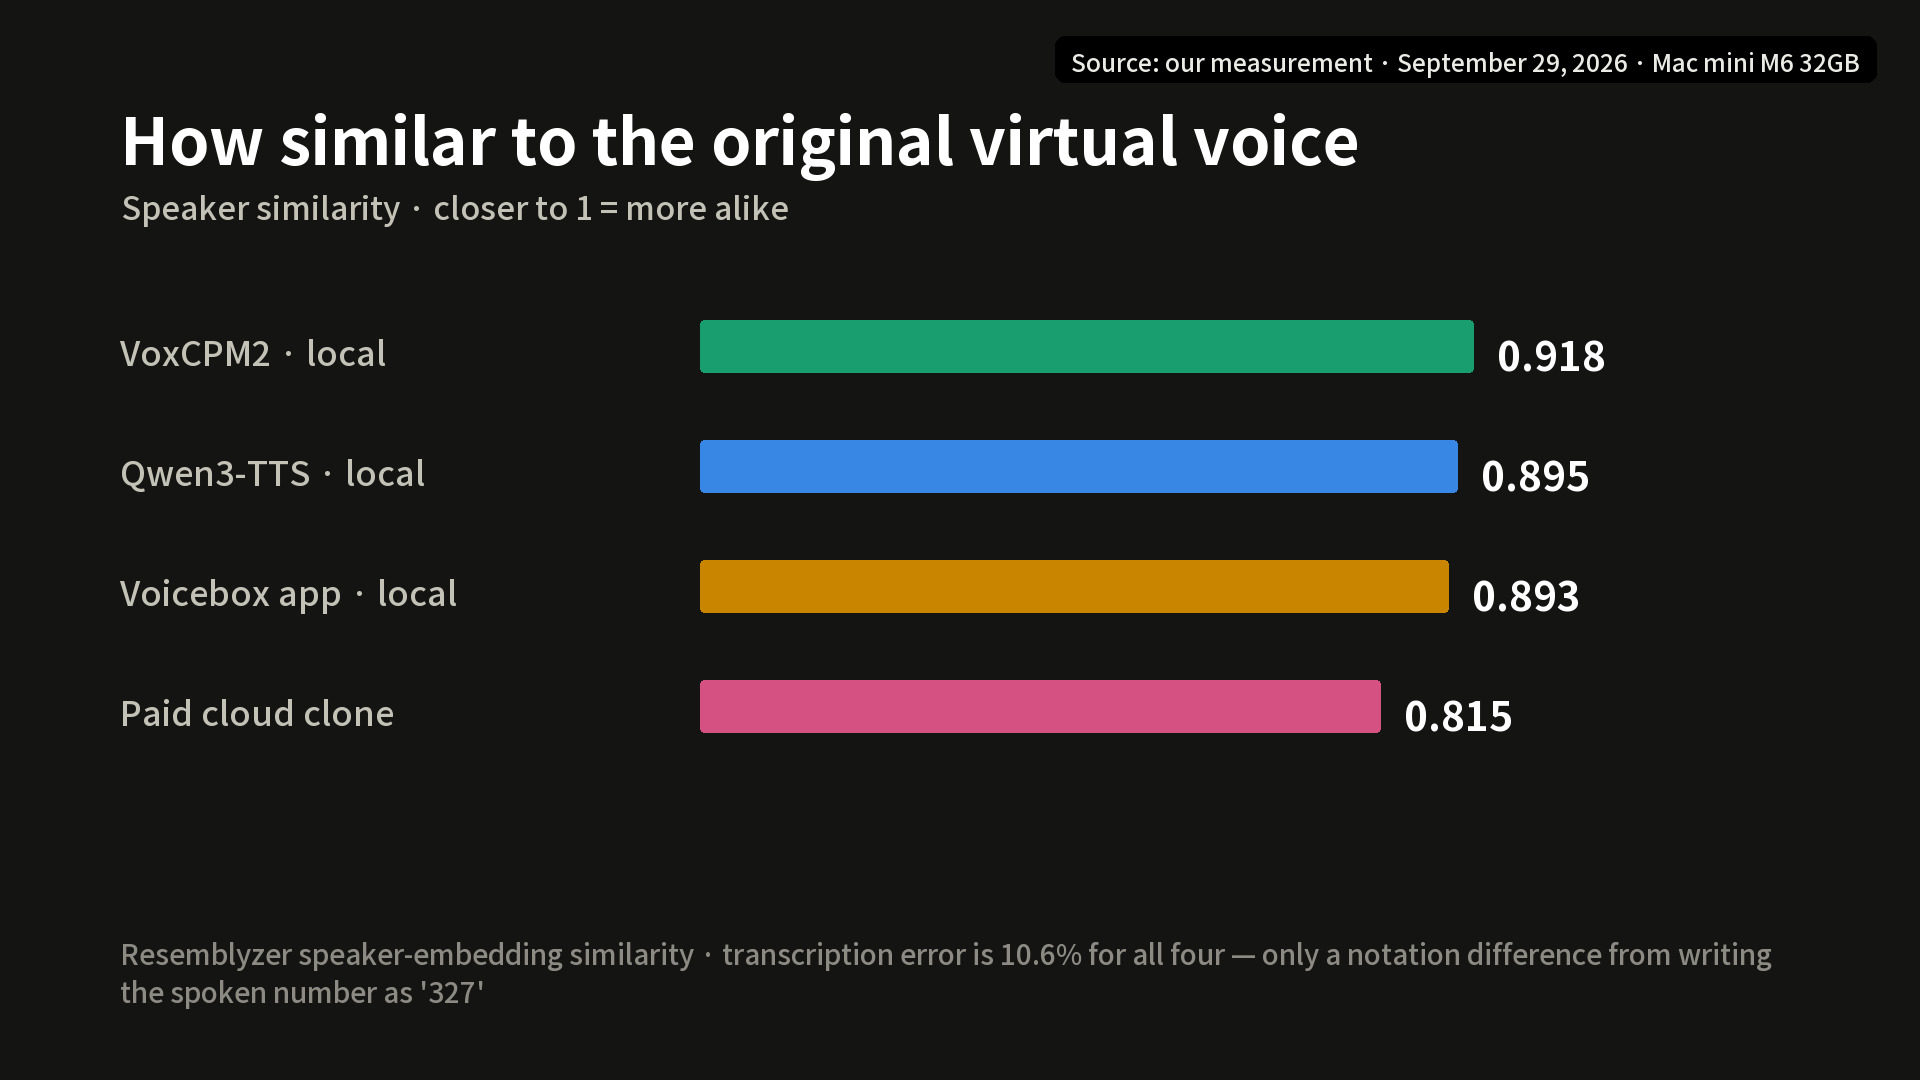
- Voice cloning was closer locally than with the paid service. Speaker similarity was 0.918 for VoxCPM2, 0.895 for Qwen3-TTS, 0.893 for the Voicebox app, and 0.815 for the paid cloud instant clone.
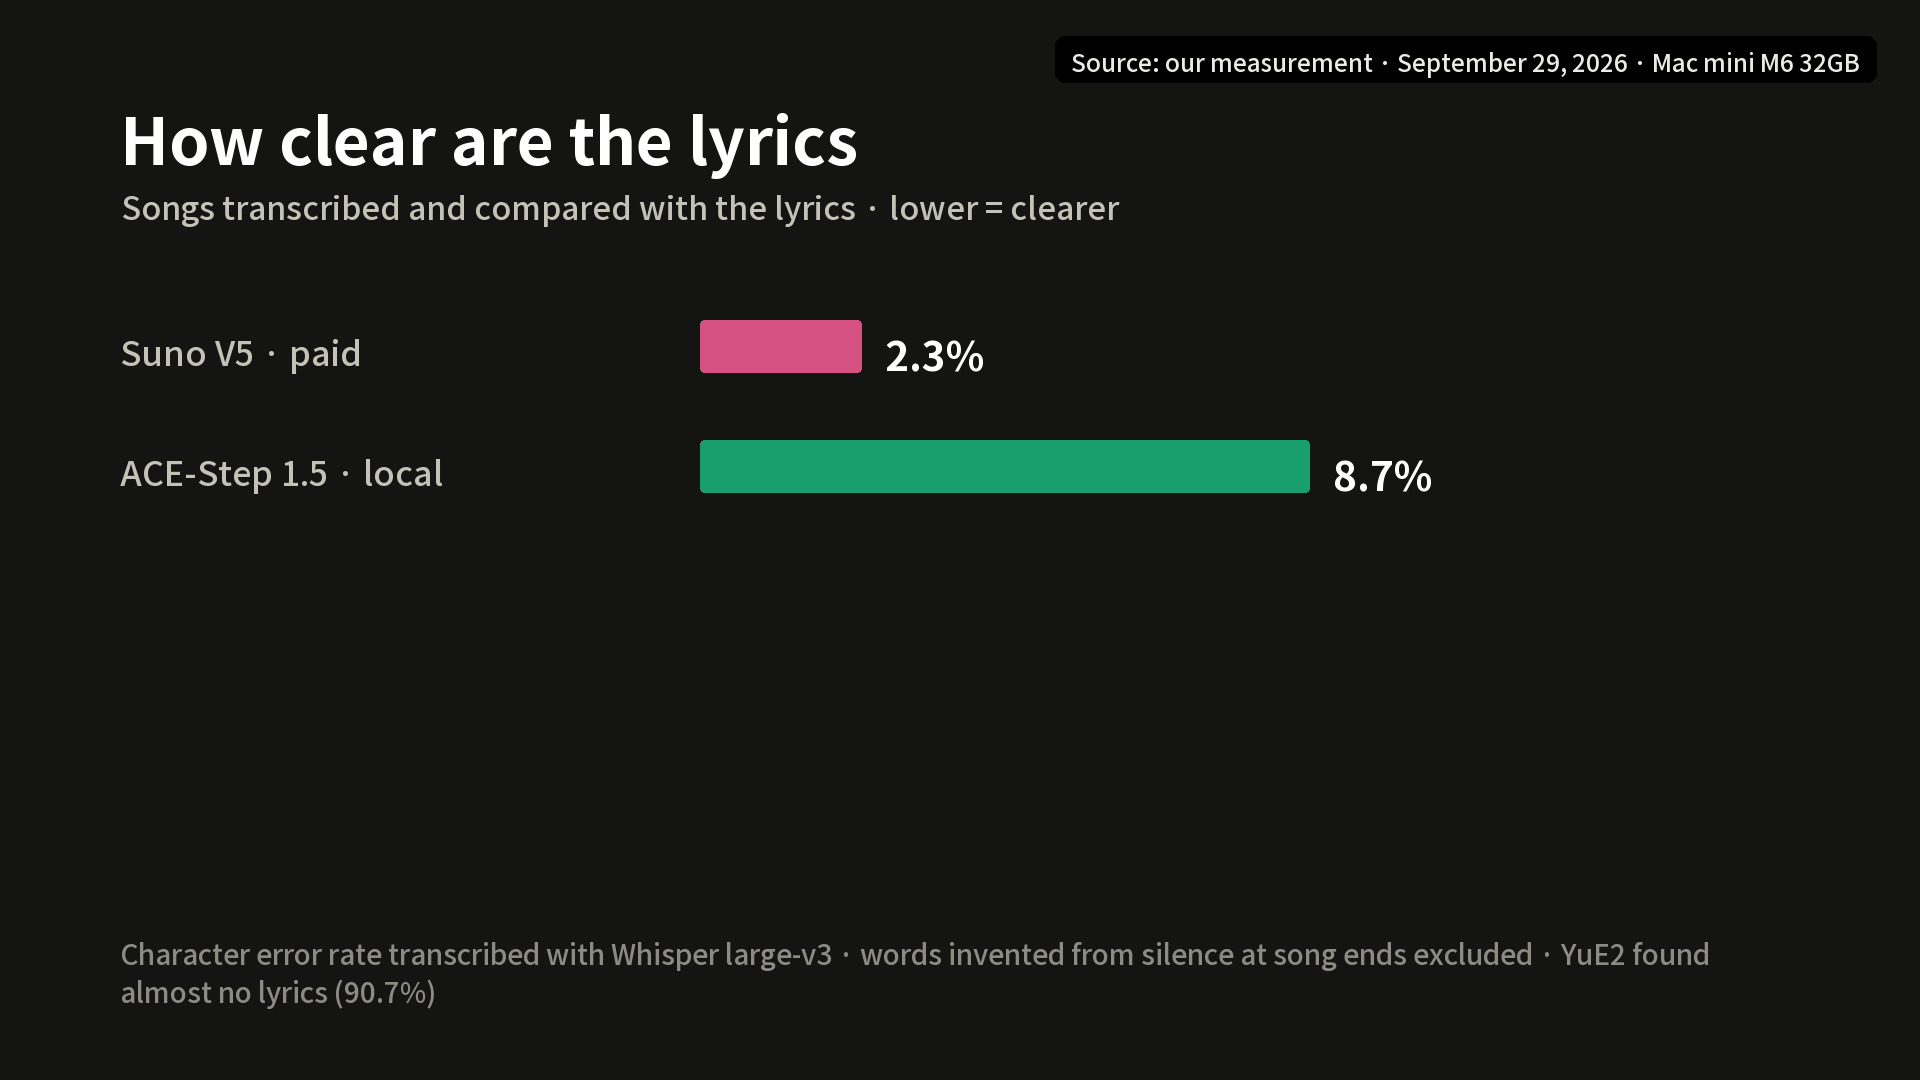
- For songs, the clearest lyrics came from paid Suno (2.3% lyric error). Local ACE-Step 1.5 scored 8.7%, and the largest model, ACE-Step XL (4B), ran out of memory and stalled on the 32GB Mac mini.
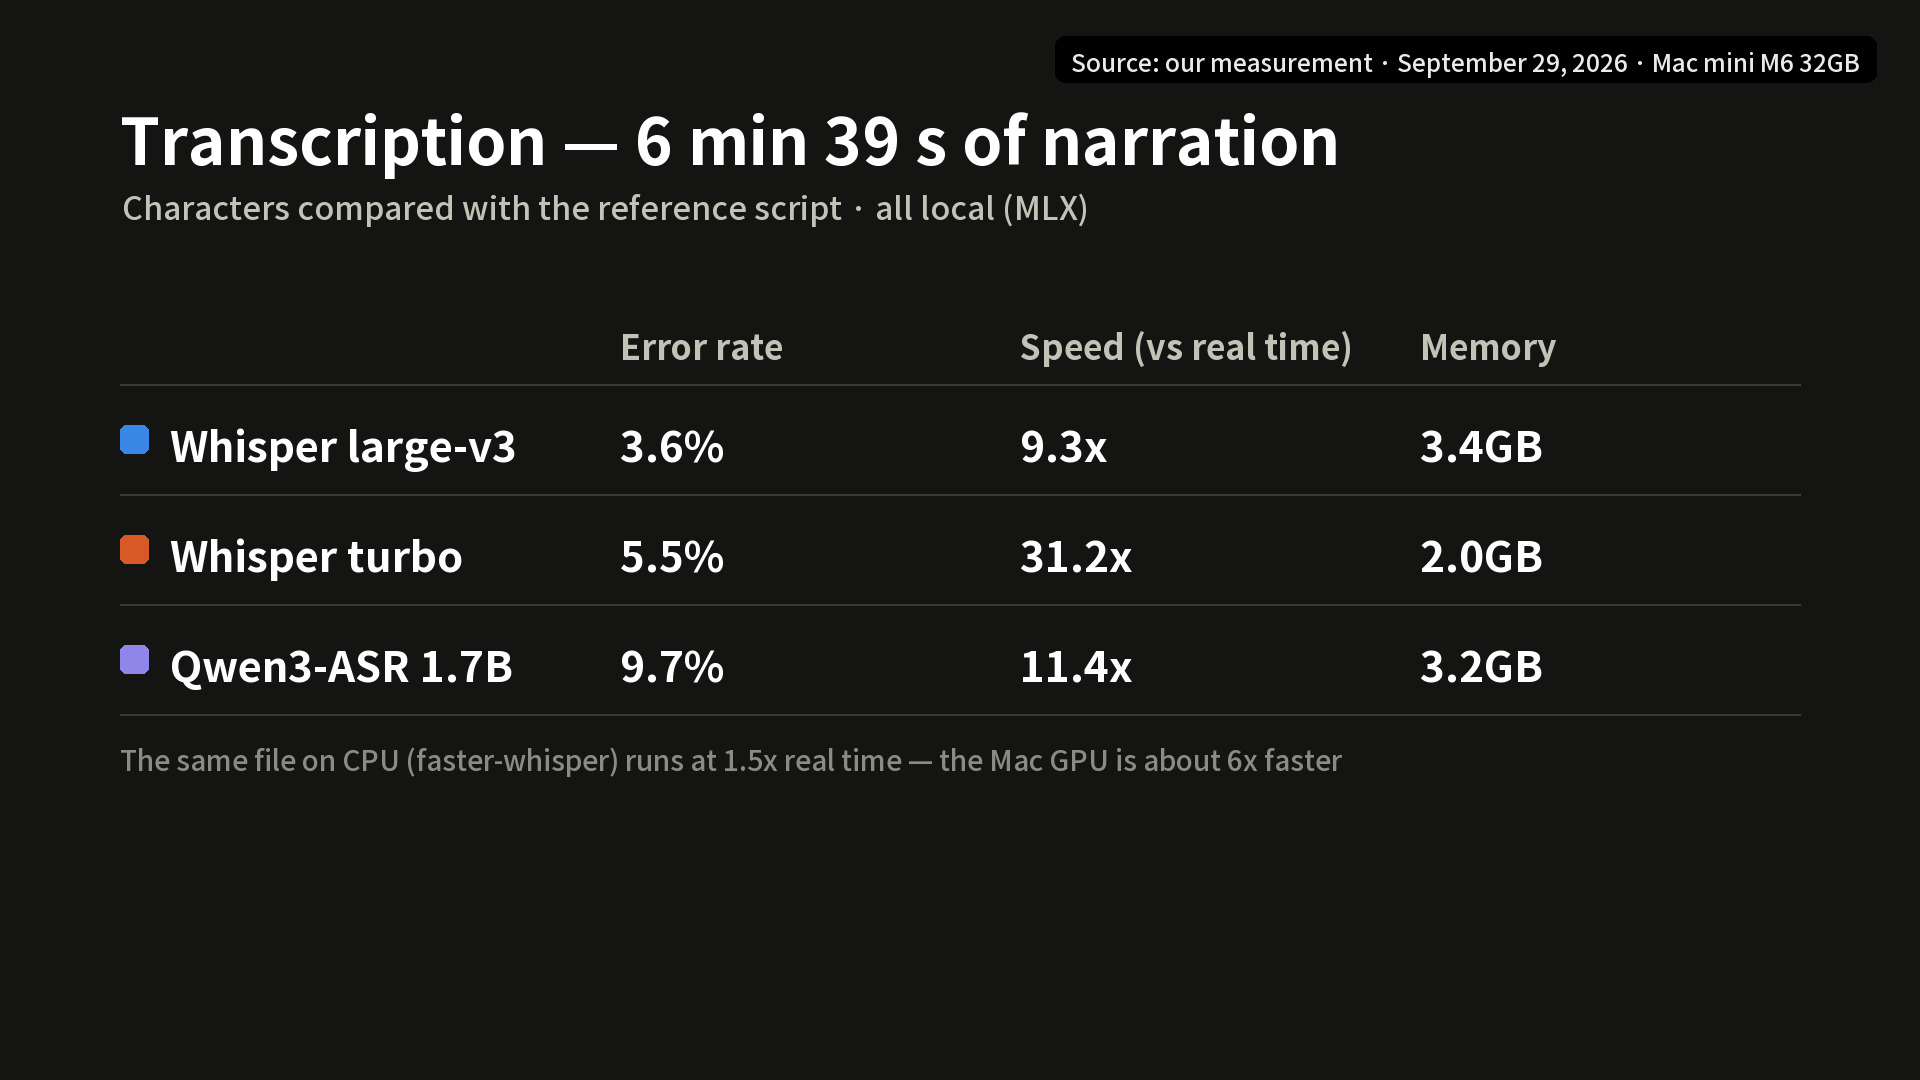
- For transcription, the old Whisper large-v3 came first with a 3.6% error rate, and the newer Qwen3-ASR made the most mistakes on our Korean narration at 9.7%.
- On 32GB, voice and transcription have plenty of room (mostly around 6GB), and composition is the tight one.
What kind of numbers these are
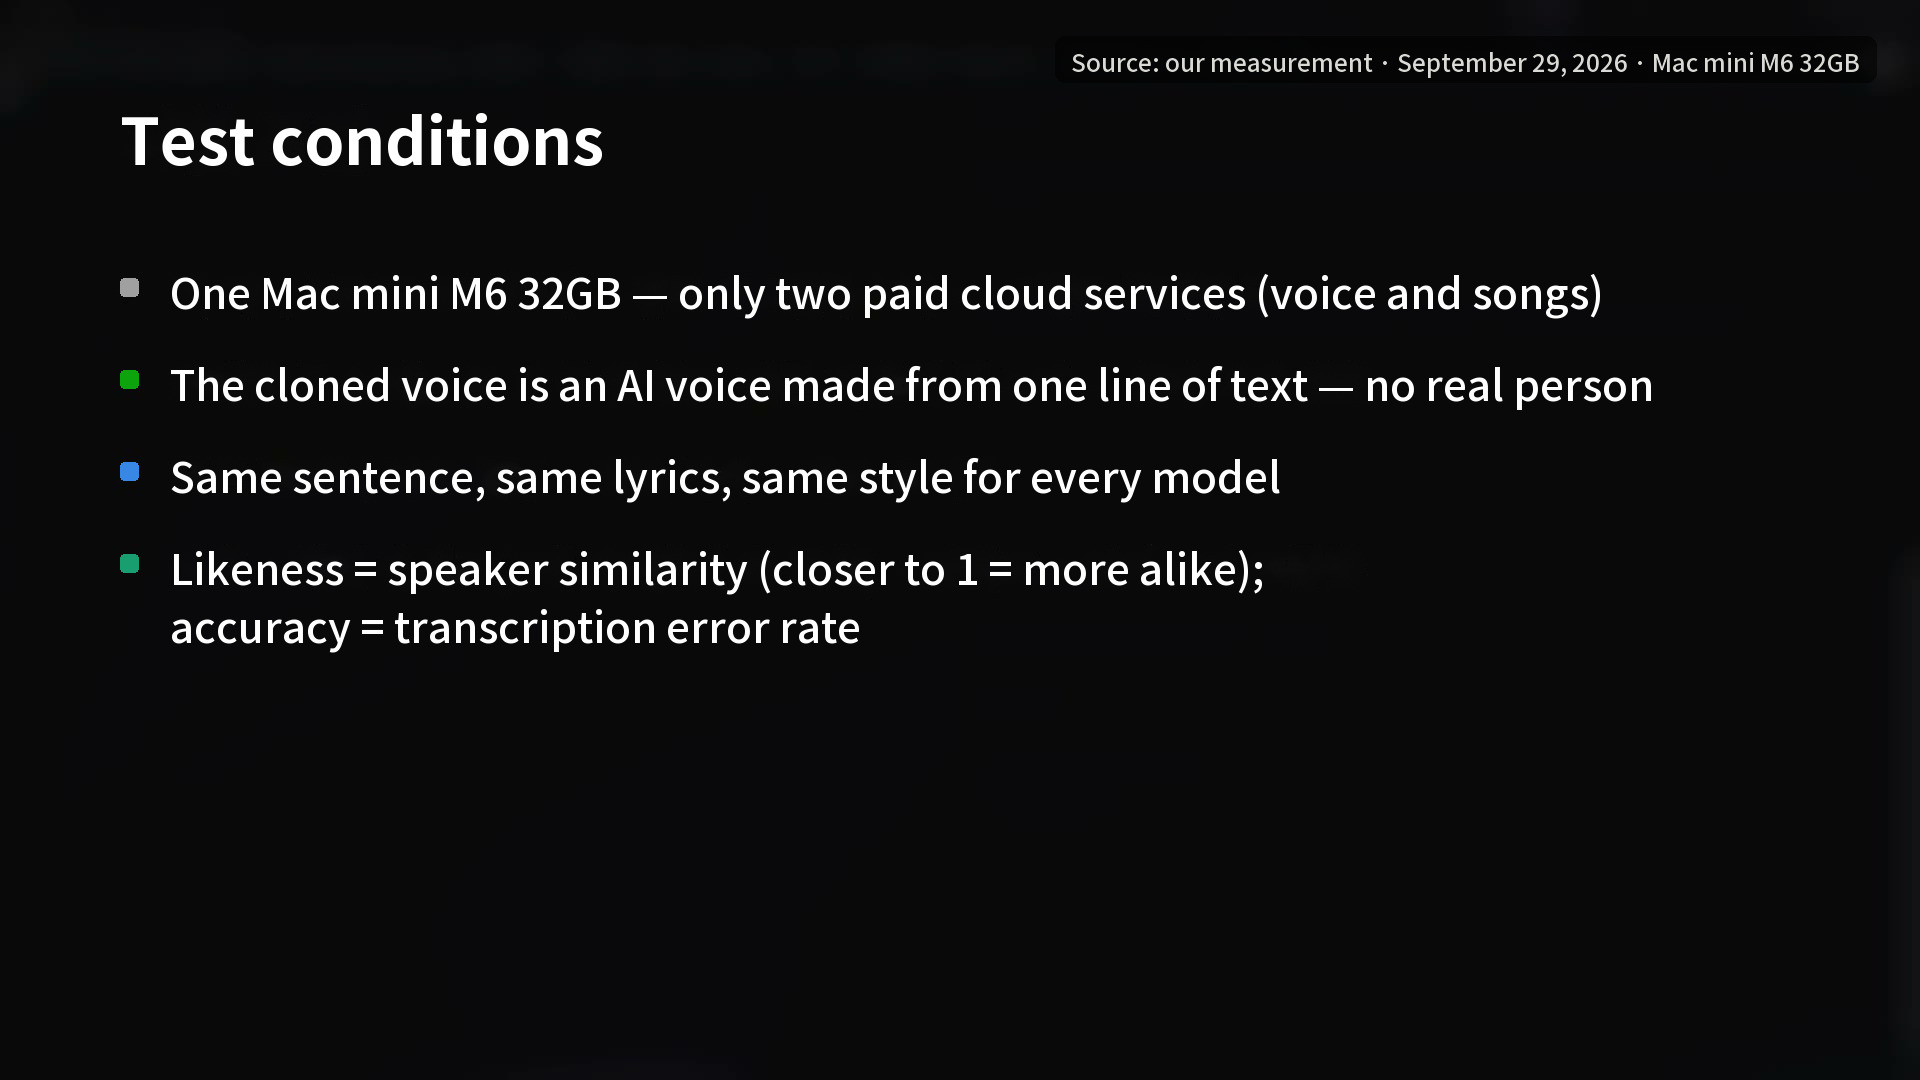
All numbers are our measurements (Mac mini M6 32GB, 2026-09-29, the same sentence and the same lyrics for every model). Except for the two paid services, everything ran on the Mac without internet. Similarity is Resemblyzer speaker-embedding similarity (closer to 1 means more alike), accuracy is the character error rate from Whisper large-v3 transcription, and memory is the peak value reported by each program. The source voice for cloning is not a real person but a virtual voice an AI made from a single line of text, and all voices in the video are AI-synthesized.
Test conditions
We first made the voice to clone. Describing it only in text as "a Korean man in his 30s, low and calm voice," Qwen3-TTS VoiceDesign 1.7B (bf16) produced 12.1 seconds of audio in 11.5 seconds using 4.7GB of memory. There are no recorded files at all, and this voice is the source for every clone. The sentence to be read mixes in the number "삼백이십칠" (327) and the English "GPU". The models were Qwen3-TTS 1.7B bf16, VoxCPM2 2B 8-bit (given a reference voice and its transcript together), mlx-audio 0.5.7, the Voicebox 0.5.0 app, ACE-Step 1.5 turbo 2B + LM 1.7B (MLX), YuE2 3B official code (device=mps), Whisper large-v3, large-v3-turbo, and Qwen3-ASR 1.7B 8-bit (MLX).
Voice cloning: local sounded closer
| Method | Similarity | Speed (audio length → time taken) | Memory |
|---|---|---|---|
| VoxCPM2 2B 8-bit | 0.918 | 10.4 s → 17.2 s | 6.2GB |
| Qwen3-TTS Base 1.7B | 0.895 | 8.9 s → 10.6 s | 4.7GB |
| Voicebox app (same Qwen3-TTS inside) | 0.893 | 9.8 s → 23.5 s (first run 32 s) | - |
| Paid cloud instant clone | 0.815 | 9.85 s → 1.5 s | - |
All four had a transcription error of 10.6%, and every one of those was just writing "삼백이십칠" as the digits 327, so there were no actual mispronunciations. Voicebox is a free app you install by dragging the installer into the Applications folder (the video says it has over 50,000 GitHub stars), and it took about 40 seconds from creating a voice to saving the profile. We did not investigate why it is about twice as slow as the terminal despite using the same model.
Composition: paid was ahead on lyrics
We compared with the same Korean lyrics and style (we wrote the lyrics ourselves). ACE-Step 1.5 took 76.8 seconds for two 60-second songs with an 8.7% lyric error. The backing and melody sound plausible, but in places "팬 소리도" sounded like "벤 소리도" and "맥 미니로" like "맹이로". Paid Suno V5 produced two songs (50.9 and 40.4 seconds long) in 24.8 seconds from the same lyrics, with a 2.3% lyric error. The lyric error rate is the song transcribed to text and compared with the lyrics, excluding words invented in the silence at the end of a song.
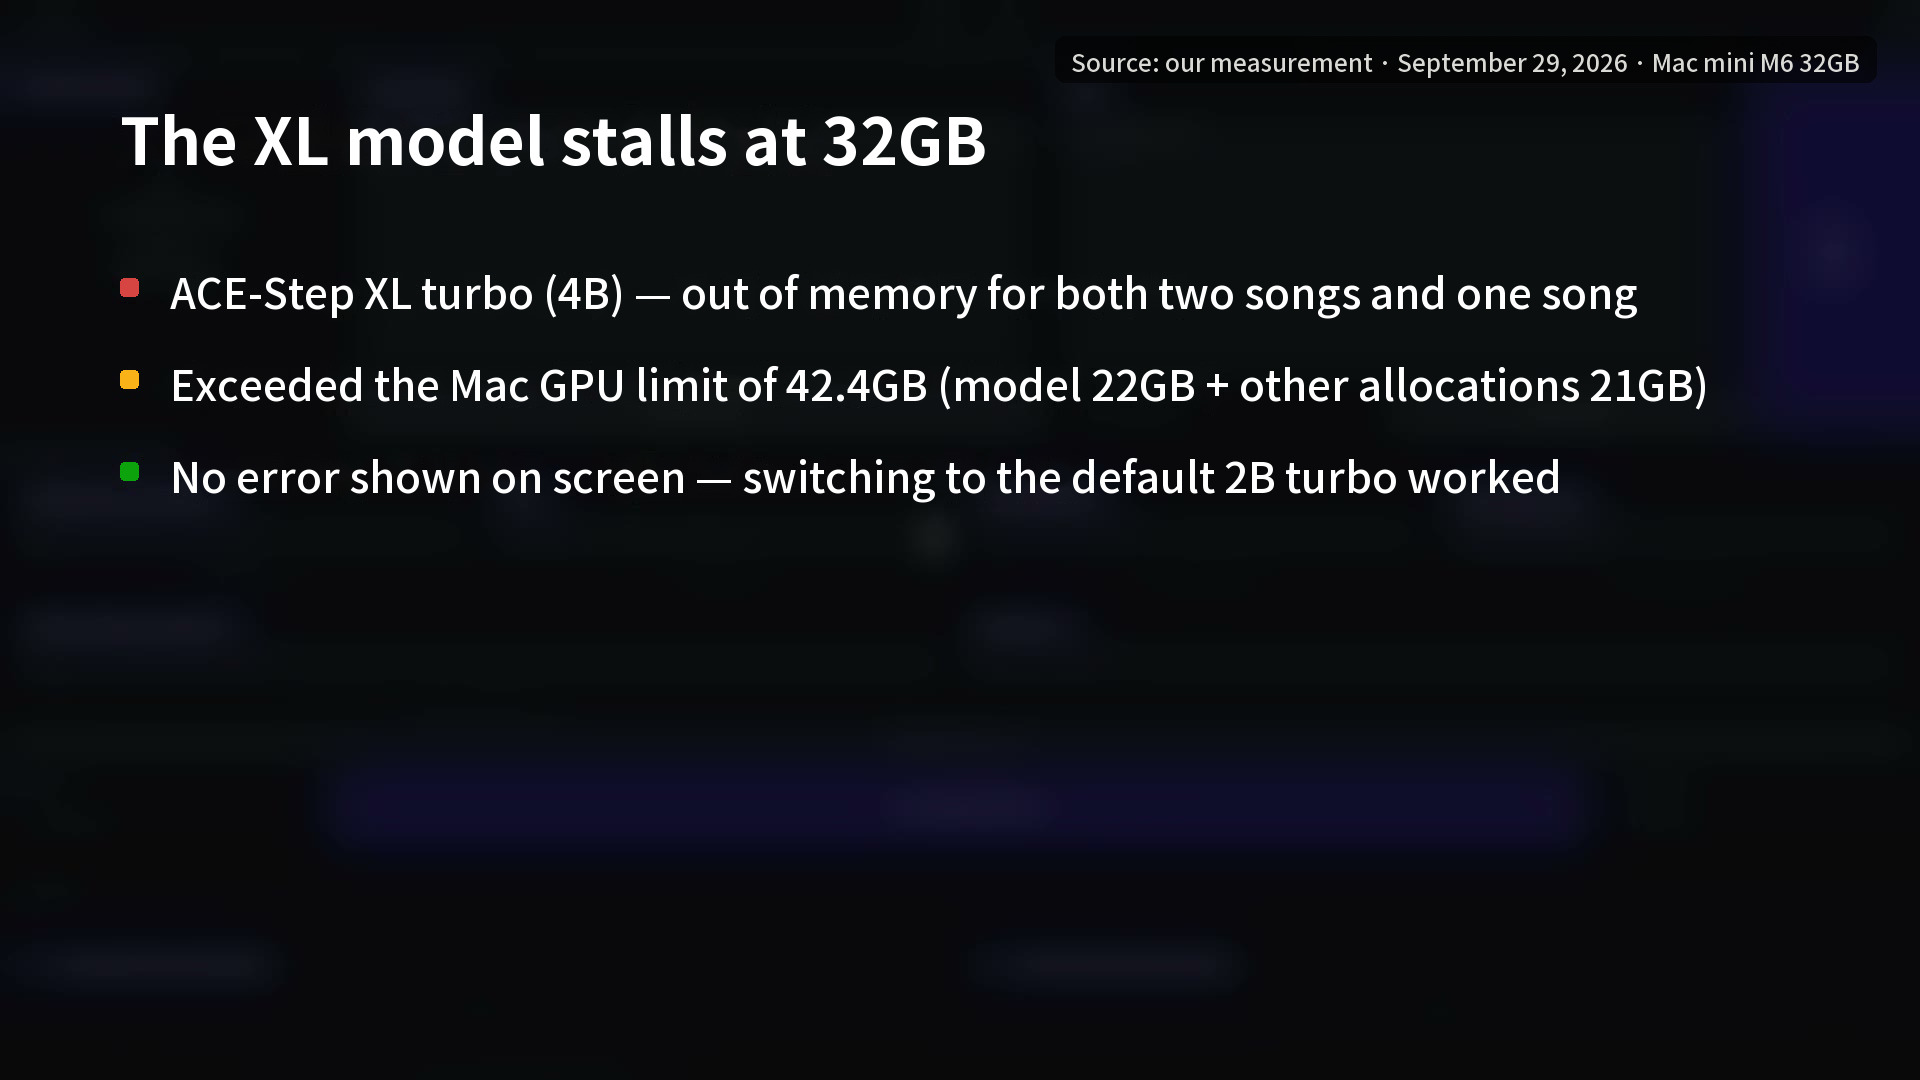
The largest model, ACE-Step XL turbo (4B), stalled from lack of memory both with two songs at a time and one at a time. A model at 22GB plus other allocations of 21GB exceeded the Mac's GPU limit of 42.4GB, and no error appeared on screen, so we switched to the default 2B model. YuE2's official guidance says Linux with an NVIDIA 24GB card only, but it actually ran on the Mac GPU (MPS), taking 246 seconds (about 4 minutes) for a 65.5-second song, and the transcription could hardly find the Korean lyrics (90.7%). Korean is not an officially supported language.
Transcription: the old Whisper came first
We compared 27 of our channel's narration clips (6 minutes 39 seconds) against the reference script. On the same 16-second sample, Whisper and Qwen3-ASR both finished in 1.5 seconds, but Whisper wrote "3090과 4090" correctly while Qwen3-ASR wrote "3,990, 4,990".
| Model (all local, MLX) | Character error rate | Speed (x real time) | Memory |
|---|---|---|---|
| Whisper large-v3 | 3.6% | 9.3x | 3.4GB |
| Whisper large-v3-turbo | 5.5% | 31.2x | 2.0GB |
| Qwen3-ASR 1.7B | 9.7% | 11.4x | 3.2GB |
Running the same file on the CPU (faster-whisper) gives 1.5x real time, so the Mac GPU is about 6x faster.
Is a 32GB Mac mini enough?
| Model | Memory | Result |
|---|---|---|
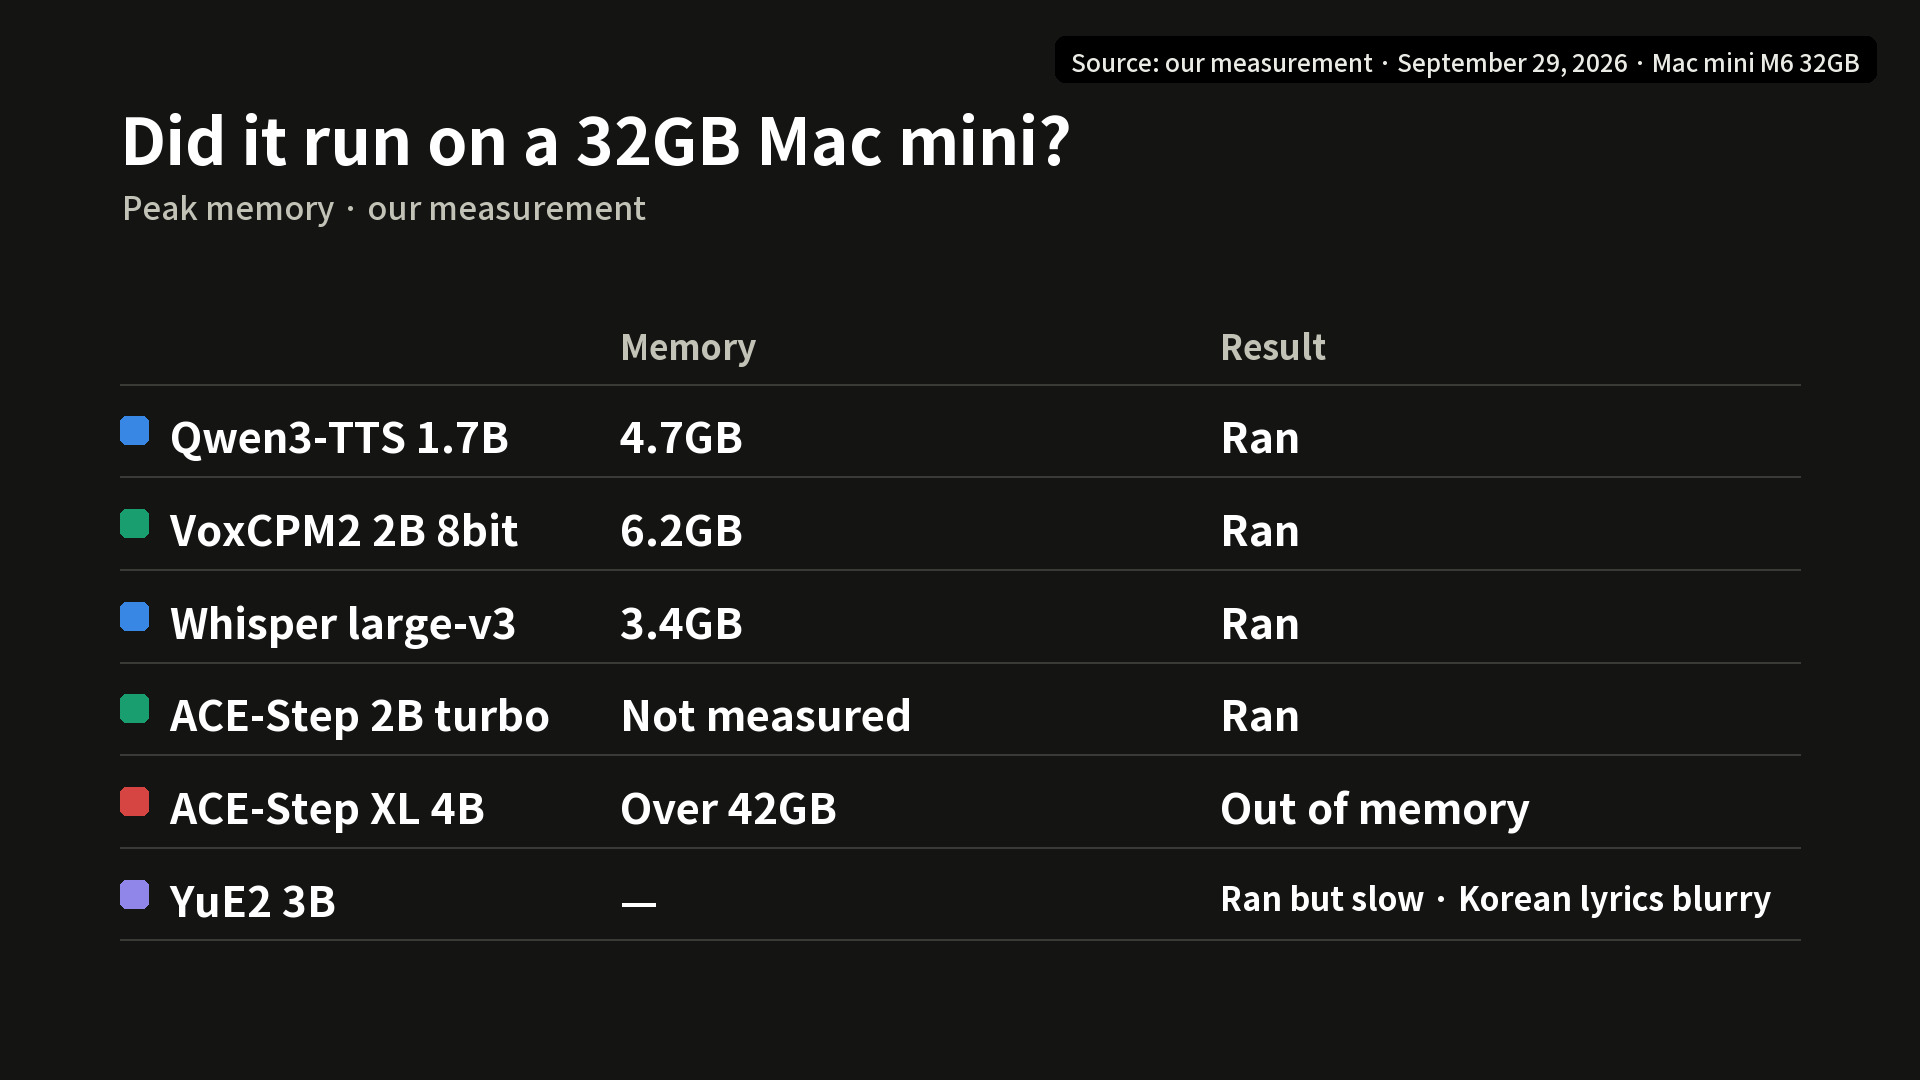
| Qwen3-TTS 1.7B | 4.7GB | ran |
| VoxCPM2 2B 8-bit | 6.2GB | ran |
| Whisper large-v3 | 3.4GB | ran |
| ACE-Step 2B turbo | not measured | ran |
| ACE-Step XL 4B | over 42GB | out of memory |
| YuE2 3B | - | ran but slow, Korean lyrics blurry |
The video's summary and before you use it
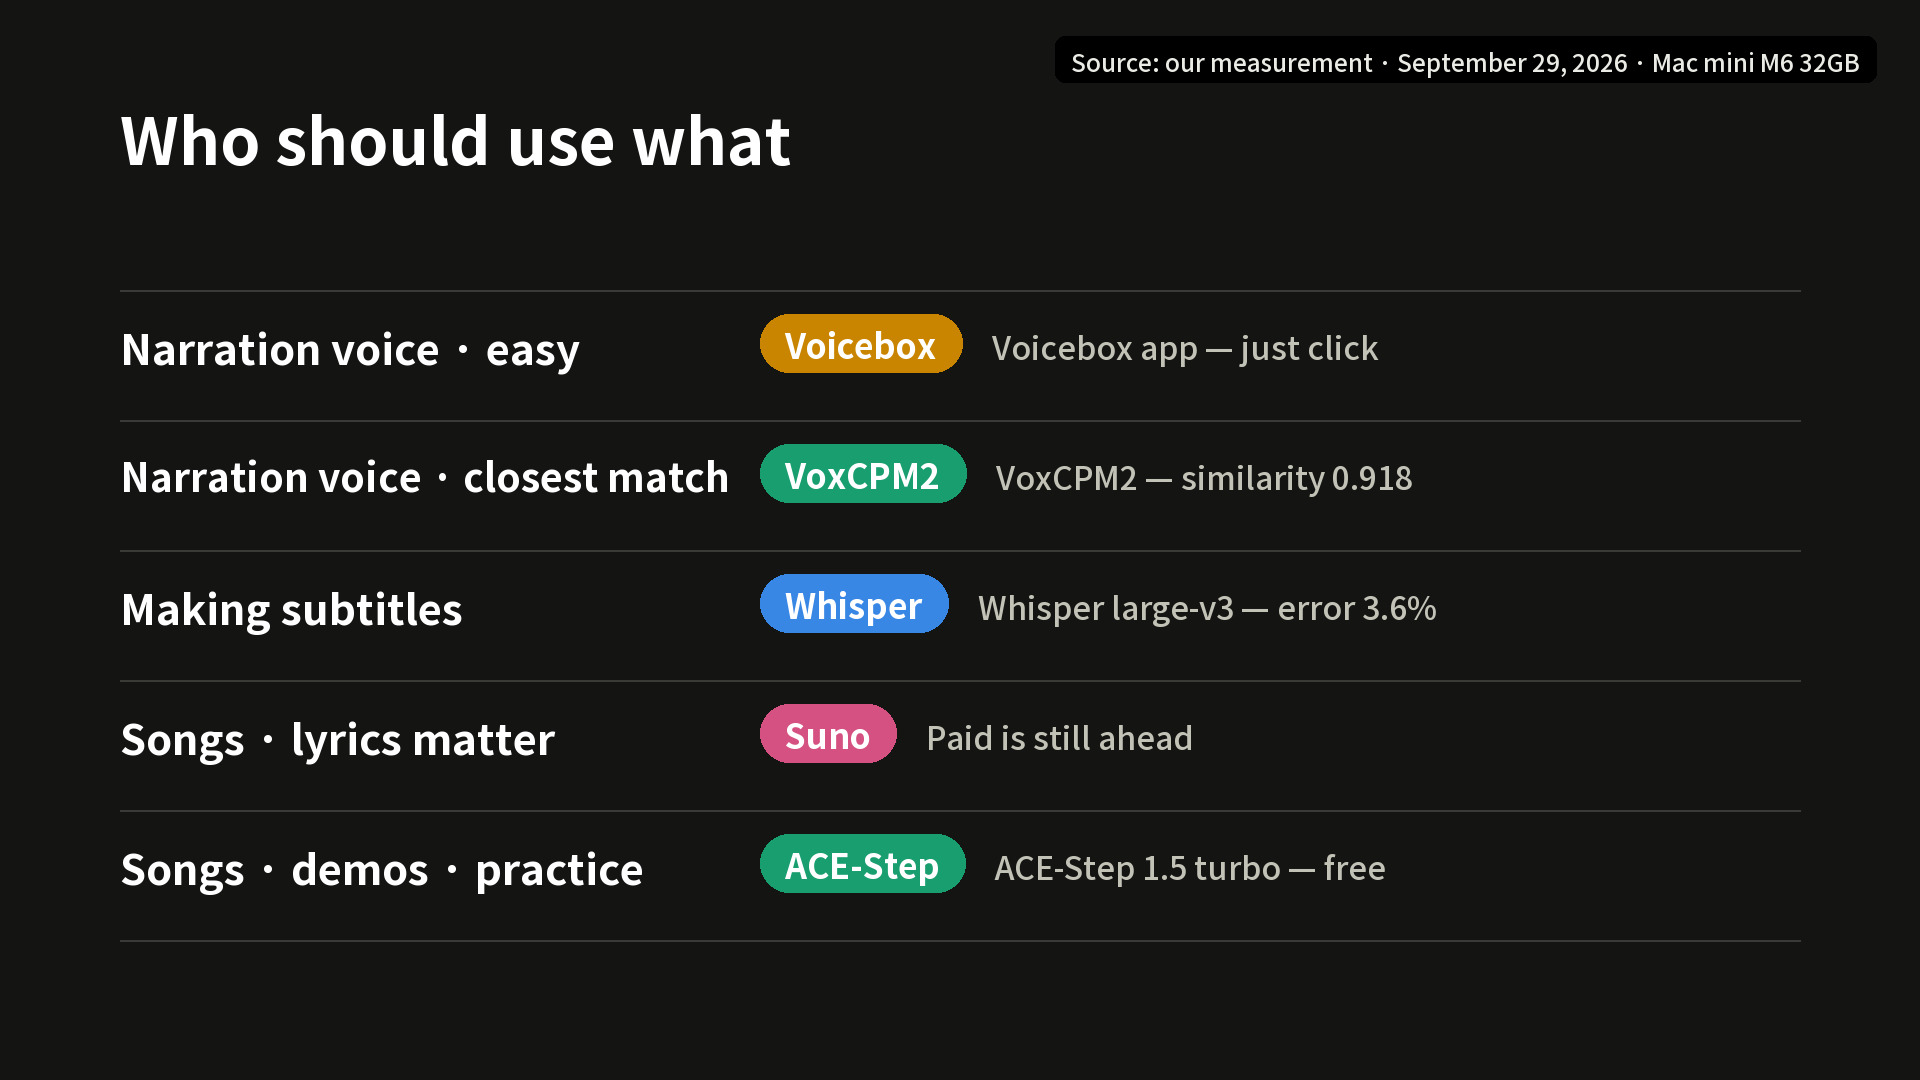
The video's conclusion is that voice cloning for narration is now fine on a Mac mini without a subscription. The easy choice is Voicebox, the closest is VoxCPM2, for subtitles Whisper large-v3, and for songs paid services are still ahead, but for demo tracks or practice you can generate them free with ACE-Step. Clone only your own voice or a voice you have written permission to use. On licenses, Qwen3-TTS and VoxCPM2 are Apache-2.0, ACE-Step is MIT, and YuE2 is non-commercial by default with a condition allowing individual creators, so check each repository's latest license before using them.
Limits and reference date
- Cloning was one sentence, one run per model. Similarity is a single metric (Resemblyzer), and the lyric error rate is a value that goes through transcription.
- The paid cloud speeds (1.5 s, 24.8 s) include the internet, so their conditions differ from local speeds. We did not investigate why Voicebox is slower.
- Transcription is based on our channel's Korean narration and may differ for other voices.
- Reference date: measured 2026-09-29, video published 2026-10-01 (as of the video's publication; model versions may have changed since).