Will It Run on My PC? Quantized Files 5 to 94GB: RAM, VRAM and Mac Fit
Posted Video released
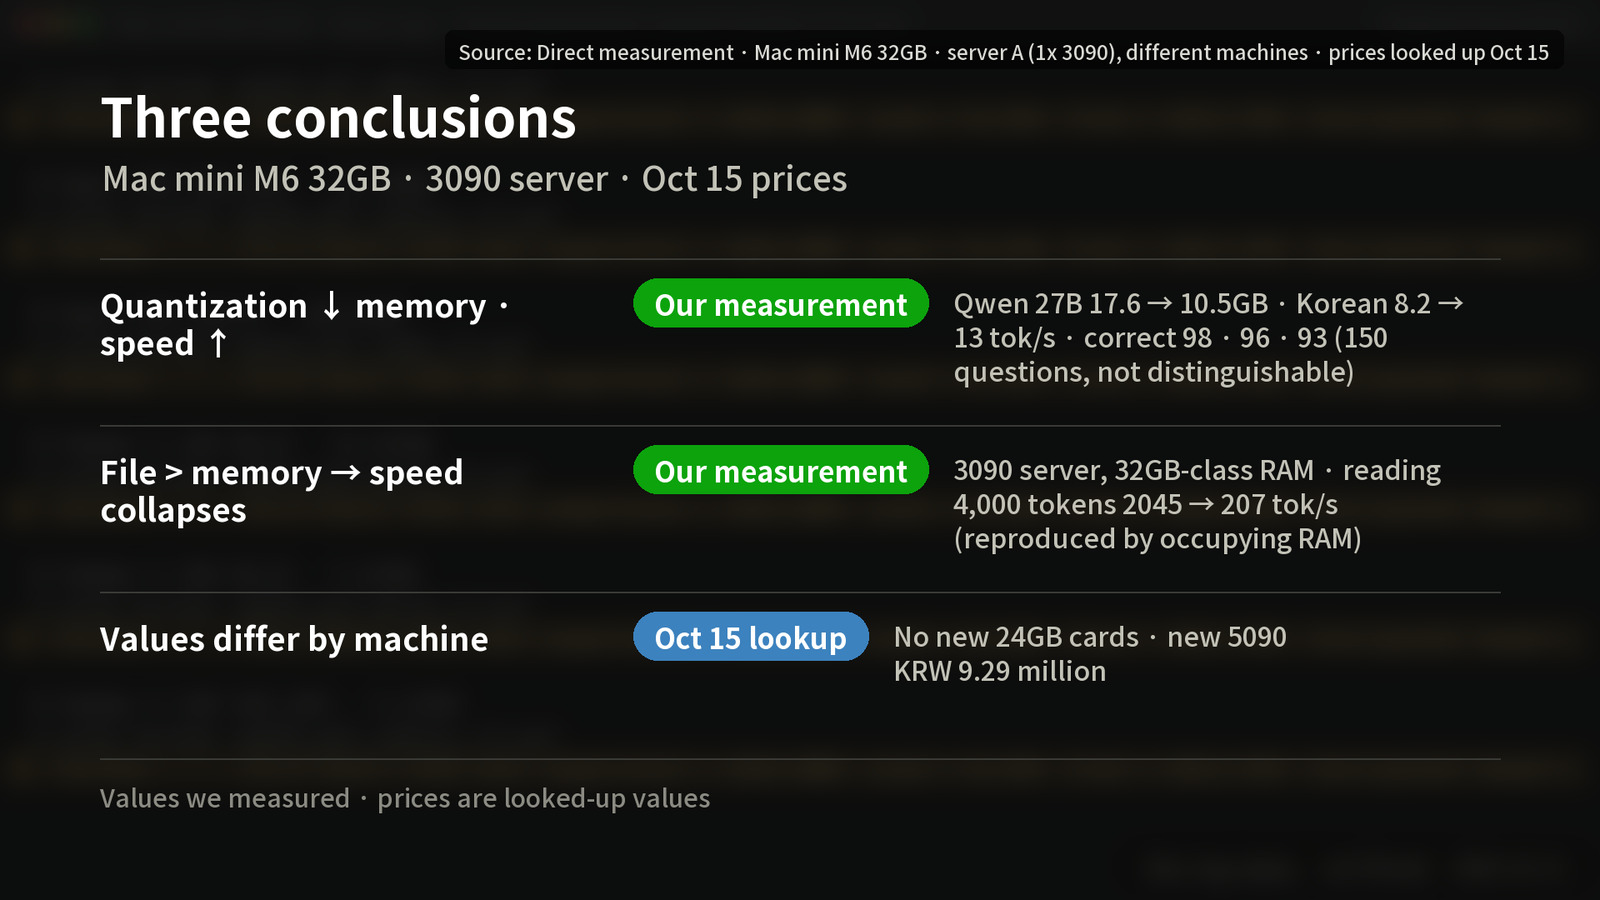
Lower quantization shrinks Qwen 27B from 17.56 to 10.52GB on a 32GB Mac mini and speeds Korean from 8.2 to 13.0 tok/s. When a file exceeds RAM, speed collapses. 3090, 5090 and Mac fit, with October 15 prices.
Will this model run on my computer? Lowering the quantization (the way a model file is shrunk) on a 32GB Mac mini cuts the Qwen 27B file from 17.56GB to 10.52GB and speeds up Korean generation from 8.2 to 13.0 tokens per second. But when the file gets bigger than RAM, speed collapses. When we reproduced a 32GB-class RAM on a 3090 server, reading 4,000 tokens dropped from 2045.1 to 206.7 tokens per second. This post reorganizes the YouTube video into our measurements, calculations, third-party reports and price lookups. Prices are as looked up on October 15, 2026.
The short version
- Lowering quantization improves memory need and speed in step with file size. On the Mac mini M6 32GB, Qwen 27B scored 98, 96 and 93 correct (out of 150 questions), which cannot be told apart. [our measurement]
- When the file is larger than memory, speed collapses. Flash-Next IQ3_S read 4,000 tokens at 2045.1 tokens/s with no RAM limit and 206.7 tokens/s at 32GB class. (Reproduced by occupying RAM with another process; it is not a machine that really has that RAM.) [our measurement]
- The same model costs different amounts on different machines. There are no new 24GB-class graphics cards, and a new 5090 was KRW 9.29 million as of October 15 (in Korea). [price lookup]
The numbers in this post come in four kinds
| Label | Meaning |
|---|---|
| our measurement | measured directly on the Mac mini M6 32GB and rented servers |
| calculation | multiplication or comparison of our values; whether a model fits a card's capacity (not speed) |
| third-party report | values written by someone else, such as a range from one creator's machine |
| price | looked up 2026-10-15 14:51 to 15:10 KST; new = lowest on Danawa, used = asking price (not transaction price), Apple Korea configuration prices |
The Mac mini was one M6 32GB unit running llama.cpp (build 11552), using the median of 3 runs, and Korean accuracy comes from 150 KMMLU questions. The RTX 3090 server (server A) and the RTX 5090 server (server B) were rented servers measured once each; they are different machines, so their speeds are not compared. PC prices add only the graphics card and RAM.
Mac mini 32GB: what changes when you lower quantization
We measured six configurations on the Mac mini M6 32GB under the same conditions (thinking turned off, 256 tokens, greedy).
| Model · quantization | File GB | Korean tok/s | KMMLU correct (150 questions) |
|---|---|---|---|
| Qwen 27B UD-Q4_K_XL | 17.56 | 8.2 | 98 |
| Qwen 27B IQ3_XXS | 12.32 | 11.3 | 96 |
| Qwen 27B IQ2_M | 10.52 | 13.0 | 93 |
| Gemma 4 12B Q8_0 | 12.67 | 11.4 | 103 |
| Gemma 4 12B Q4_0 | 7.22 | 18.1 | 100 |
| Gemma 4 12B IQ3_XXS | 5.15 | 25.4 | 85 |
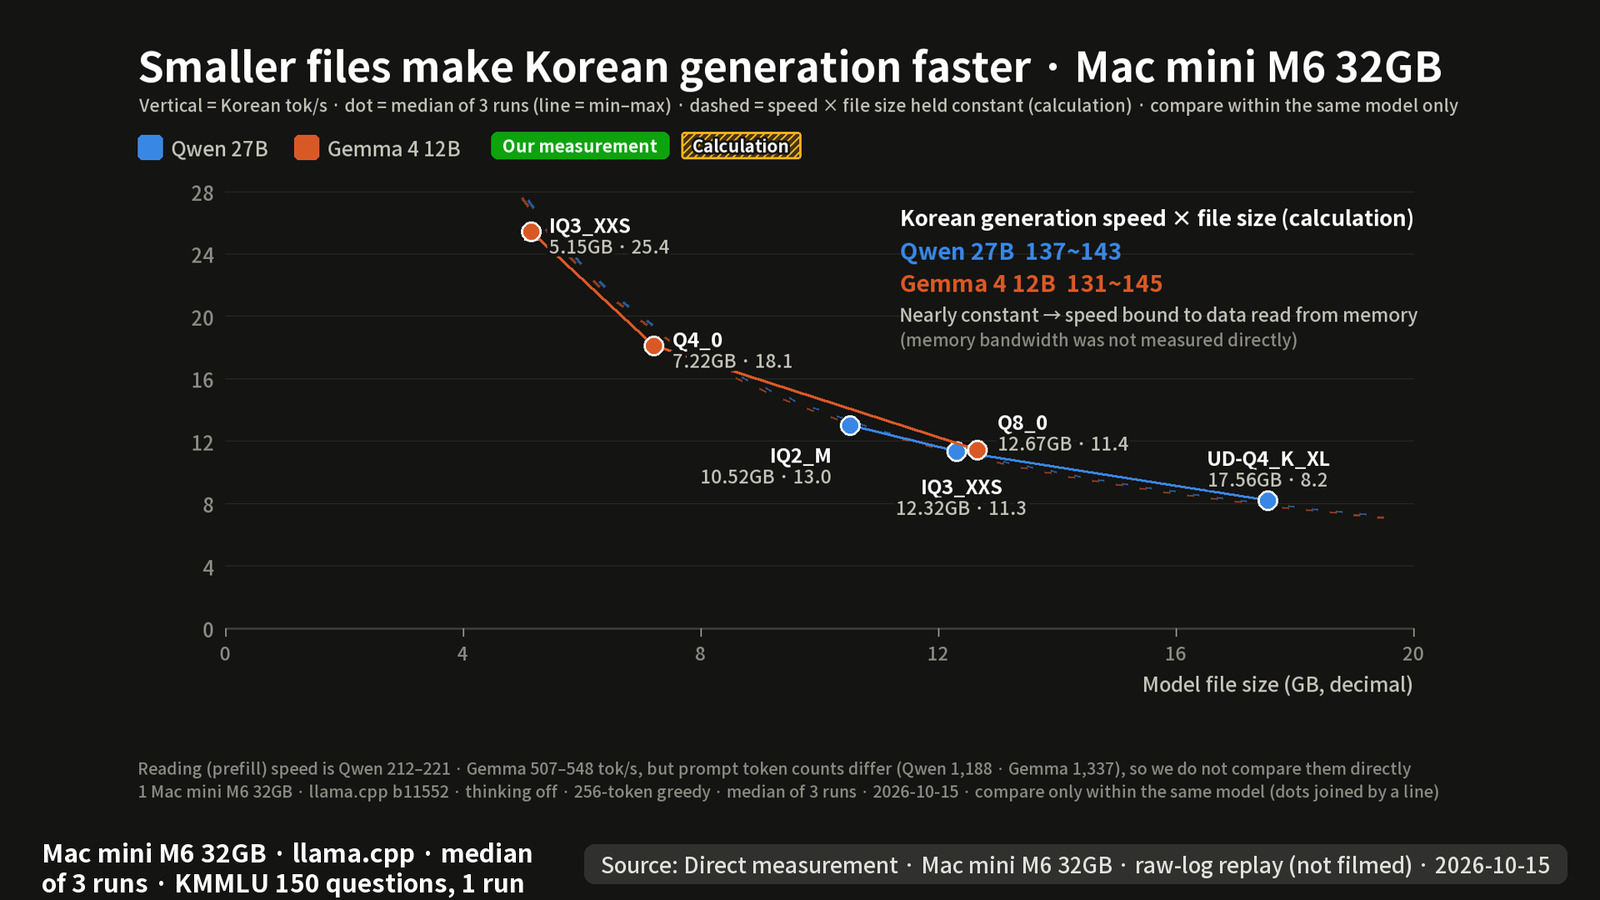
The memory actually used by Qwen 27B was about 17, 12.2 and 10.7GB (at a context of 20480). Multiplying speed by file size gives a nearly constant 137 to 143 for Qwen and 131 to 145 for Gemma. This is a calculation, not a direct measurement of memory bandwidth.
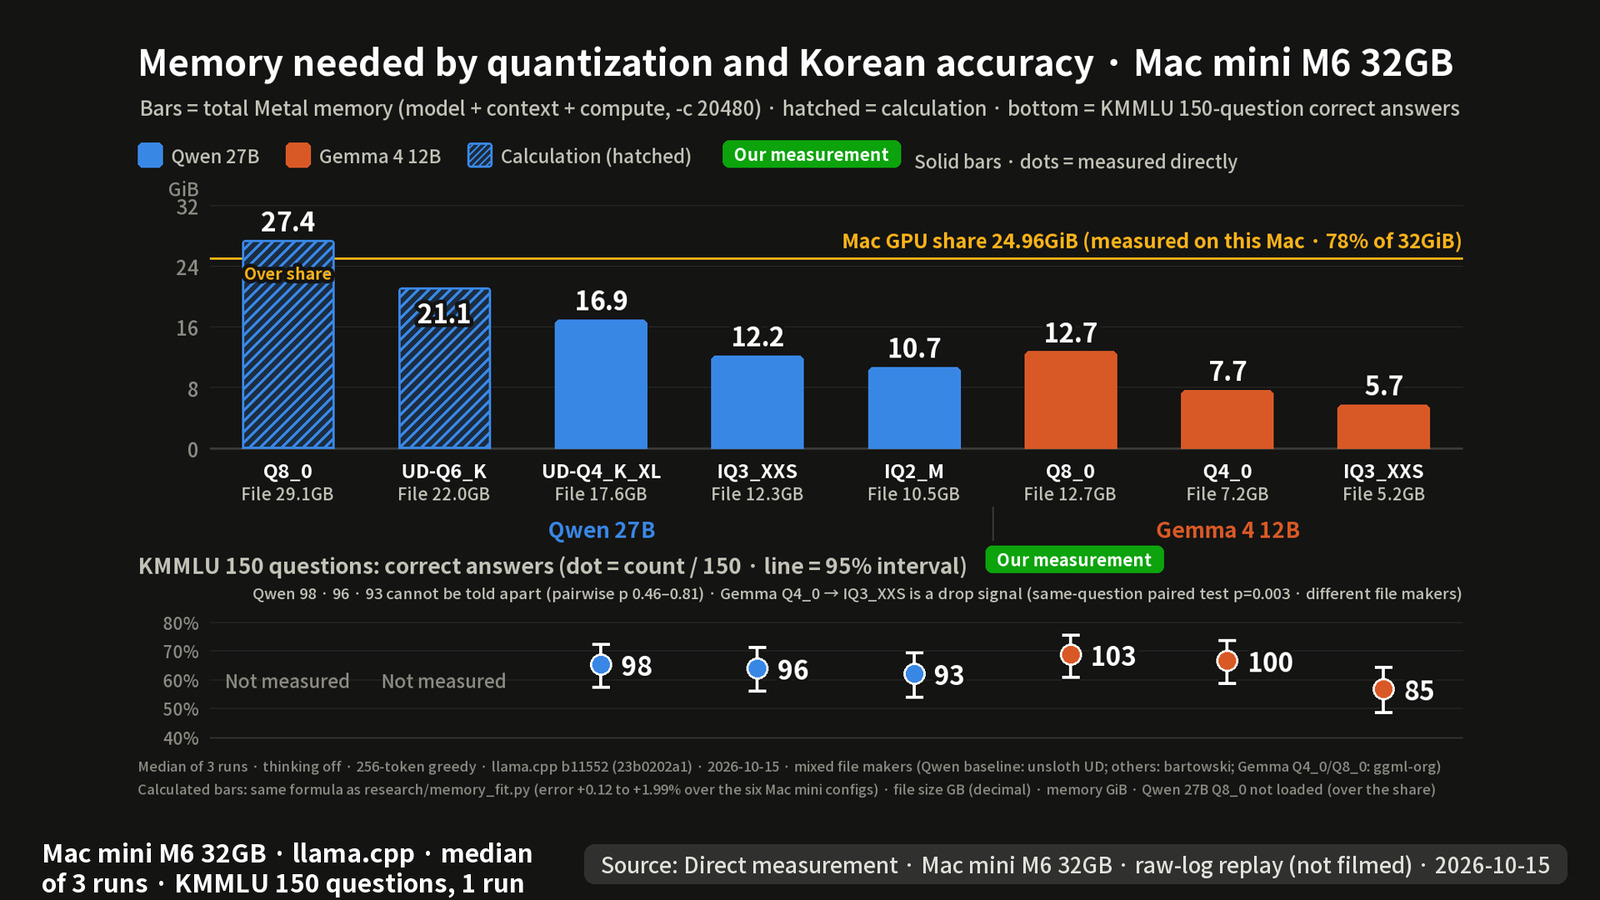
With 150 questions the margin of error is large (about ±7.5 percentage points), so Qwen 98, 96 and 93, and also Gemma Q8 at 103 and Q4_0 at 100, cannot be told apart. The drop of the 3-bit IQ3_XXS to 85 is worth treating as a warning sign, though: a paired comparison on the same questions against Q4_0 gives p=0.003. Still, the files come from different makers (Gemma Q4_0 from ggml-org, IQ3_XXS from bartowski), so we do not pin the drop on the bit count.
8, 12 and 16GB cards: only whether the model fits, by calculation
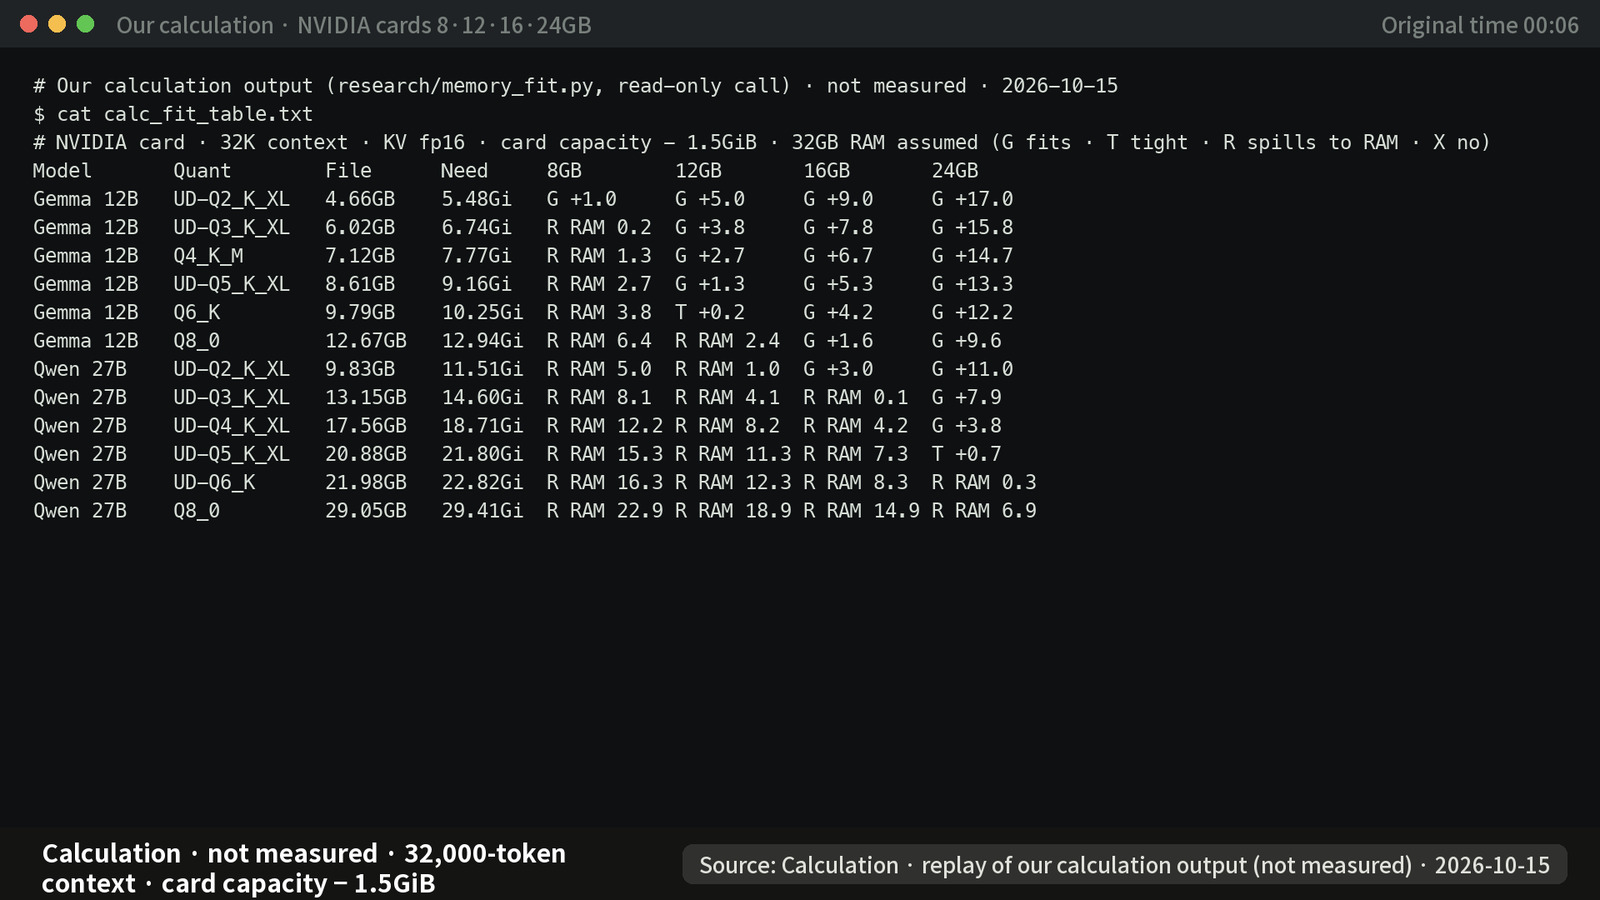
We could not measure 8, 12 and 16GB cards directly, so these are calculations. We only checked whether a model fits entirely, using a 32,000-token context and the card capacity minus 1.5GiB. We did not measure how much slower it gets when it spills into RAM.
- 8GB: up to Gemma 12B at 2-bit.
- 12GB: up to a Gemma 12B file of 8.6GB. Qwen 27B does not fit even at 2-bit.
- 16GB: up to Gemma 12B Q8 and 27B at 2-bit. 27B at 4-bit spills 4.2GB into RAM.
- 24GB: 27B at 4-bit fits entirely.
For reference, on one rented server with a 42.6GB RAM limit, a 3060 12GB ran Flash-Next at 2-bit at 39.5 tokens per second in Korean. The environment was not uniform, so treat it as reference only.
24GB 3090: for 66 to 94GB models, RAM comes first
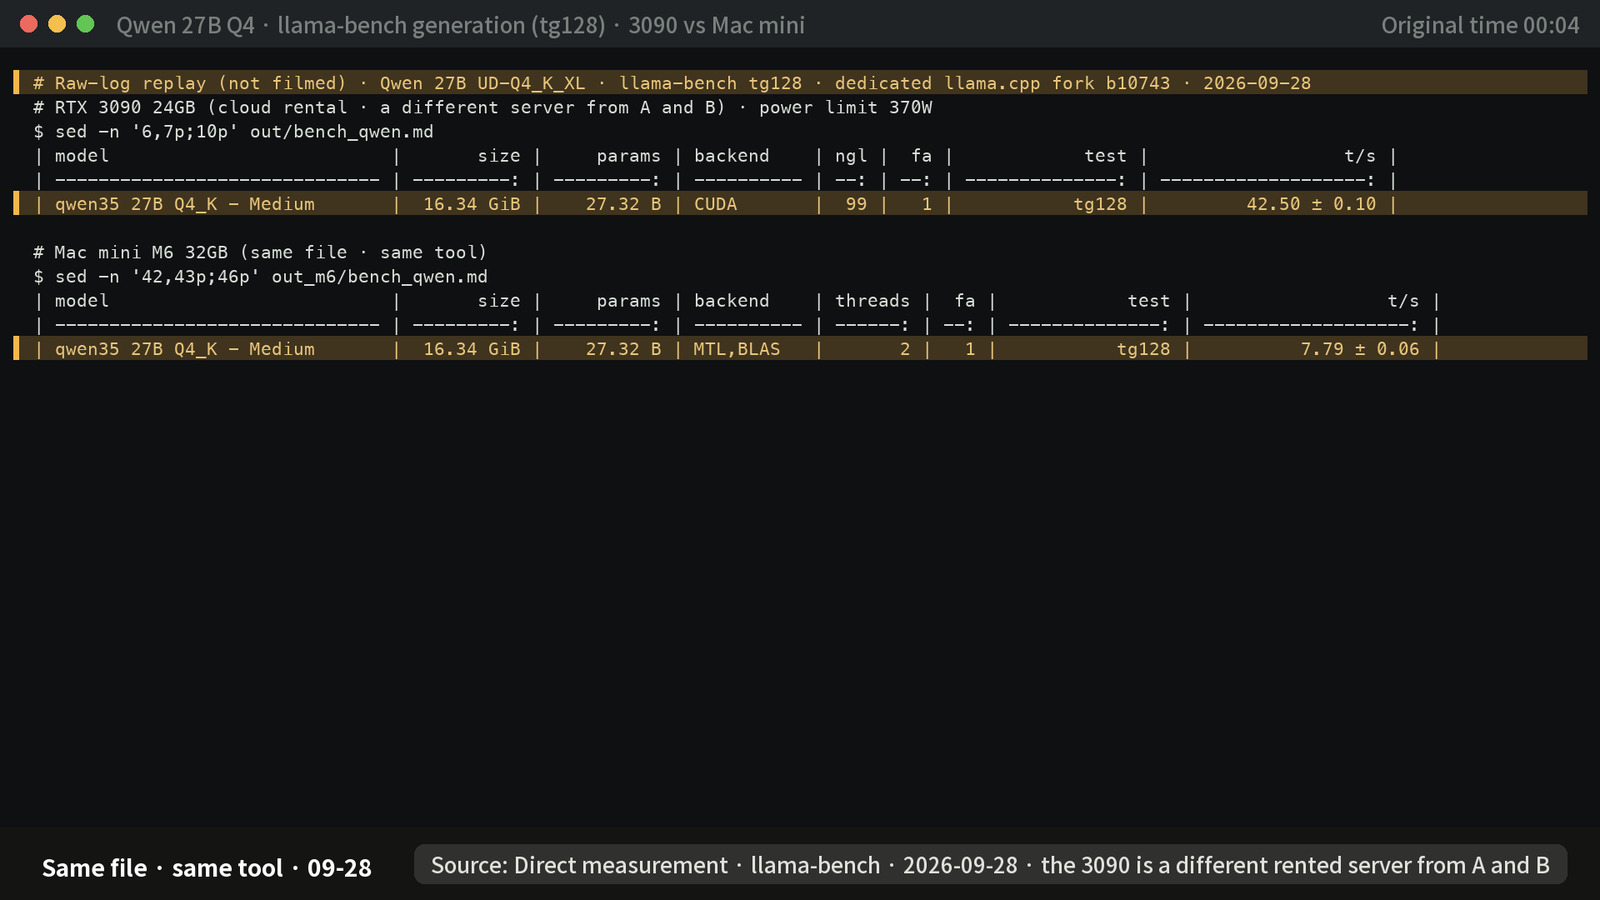
The used 3090 asking price has a pooled median of KRW 1.747 million, and per-marketplace medians over the last 30 days of KRW 1.74 to 2.0 million (in Korea). In llama-bench on September 28, 2026, with the same file, Qwen 27B Q4 generation was 42.5 tokens per second on the 3090 and 7.8 on the Mac mini. The same tool was used, but that 3090 was a different rented server from servers A and B in this video.
For Flash-Next 125B, we measured five quantizations once each on server A (3090 24GB, power limit 420W).
| Quantization | File GB | Korean tok/s |
|---|---|---|
| Q2_0 | 66.4 | 112.1 |
| IQ2_XS | 68.0 | 116.8 |
| IQ3_XXS | 75.8 | 110.1 |
| IQ3_S | 83.6 | 98.9 |
| UD-IQ4_XS* | 93.7 | 89.0 |
KMMLU accuracy over 450 questions was 65.1 to 71.3% for the four other than UD-IQ4_XS. *UD-IQ4_XS used different settings (ROUTE_TAIL_SKIP=0, STRATA_HC_Q8=1), so it is not placed on the same line. Fixed RAM was 33.47GiB for Q2_0 and 48.67GiB for IQ3_S.
Reducing RAM changes reading speed a lot. At a 32GB-class RAM (reproduced by occupying RAM; not a machine that really has that RAM), reading 4,000 tokens went from 2045.1 to 206.7 tokens/s for IQ3_S, and from 2276.8 to 1664.4 tokens/s for Q2_0.
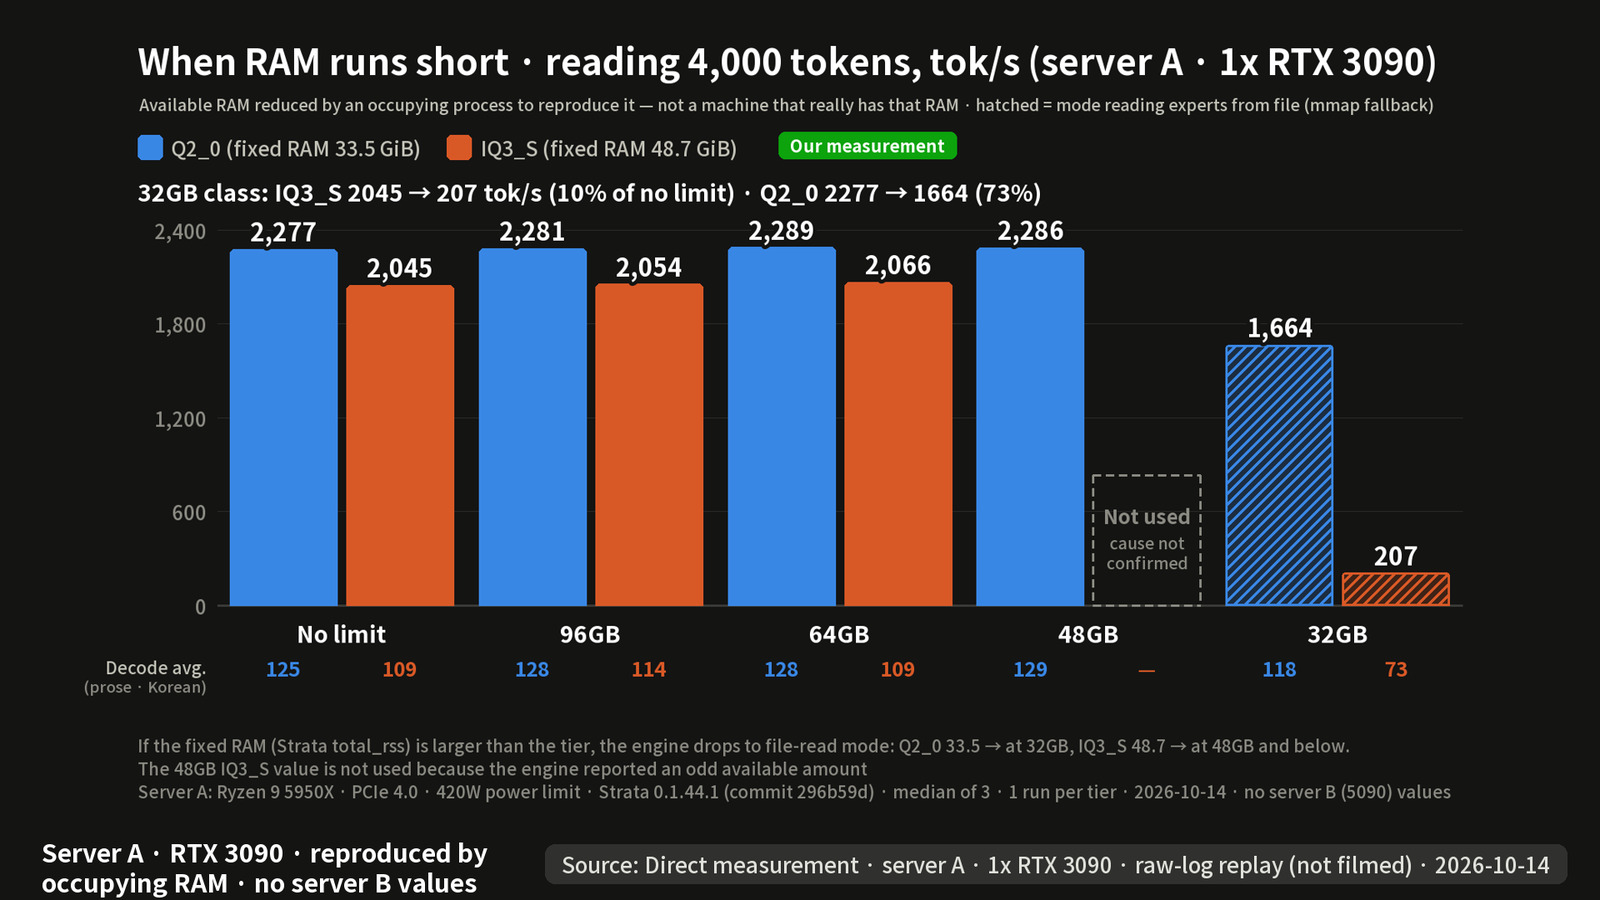
So IQ3_S ran normally with 64GB of RAM. Adding the lowest 64GB kit price of KRW 1.518 million to a used 3090 at KRW 1.747 million comes to about KRW 3.265 million (excluding motherboard, case, power supply and CPU).
32GB 5090: server B measurements and price
The 5090 was measured on server B with the power limit set to 400W. gpt-oss 120B ran at 78.8 tokens/s in Korean, using 32.9GiB of RAM (as file pages) and 29.1GiB of VRAM. Flash-Next IQ3_S ran at 39.4 tokens/s with 48.7GiB of RAM, and UD-IQ4_XS, under different conditions, at 30.2 tokens/s with 57.3GiB of RAM. During long-input reading, 32 to 51% of samples hit the power limit, so values in that range may be affected by the limit. The server had plenty of RAM (limit 384.7GiB), so a PC with tight RAM could not be reproduced.
A new 5090 was KRW 9.29 million as of October 15, up from the KRW 6.49 million range in the September 27 survey (we could not confirm the cause). The used asking price has a per-marketplace median of KRW 8.5 to 8.8 million over the last 30 days, and a new card plus a 64GB kit comes to about KRW 10.808 million.
Mac configurations: calculation and prices
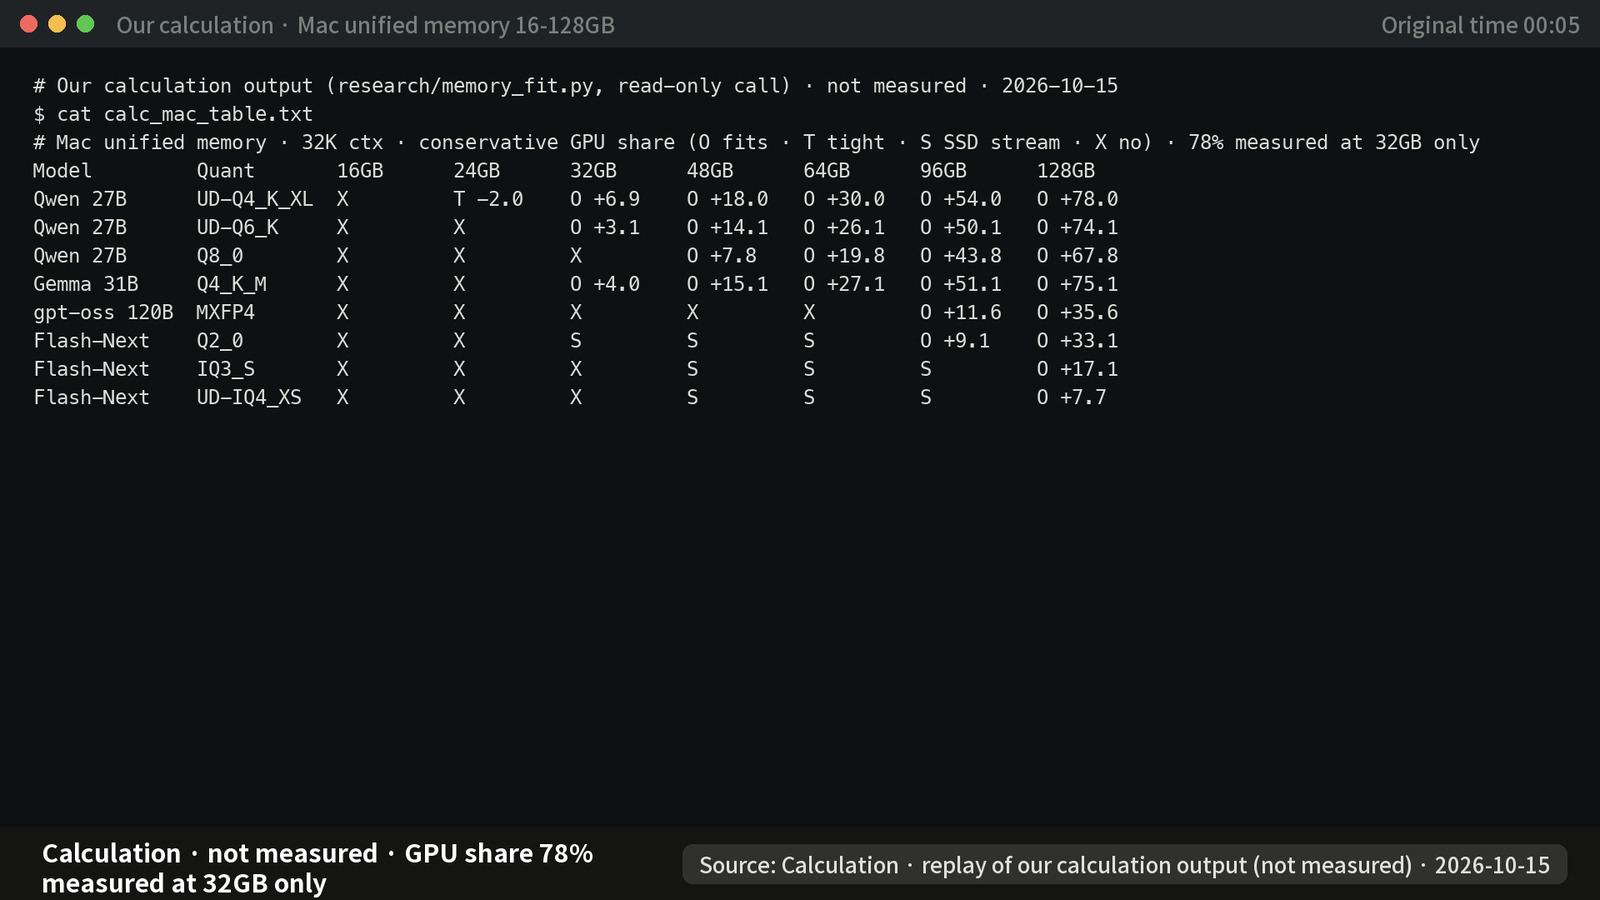
By calculation, a Mac mini 32GB fits Qwen 27B up to 6-bit and does not fit 8-bit. We measured the Mac GPU's usable share only at 32GB (78%); other capacities should be read as ranges. The 66.4GB Flash-Next 2-bit file is larger than RAM, so it reads from the SSD, and across 3 runs on the Mac mini Korean speed varied from 13.8 to 17.3 tokens per second. Because the files are 66 to 94GB, you also need free SSD space.
As a third-party report, the creator wrote that on an M4 Max 128GB, Flash-Next Q2_0 generation runs at 68 to 111 tok/s with strata-mlx and 38 to 39 tok/s with llama-server. This is a range from one creator's machine.
Prices as of October 15
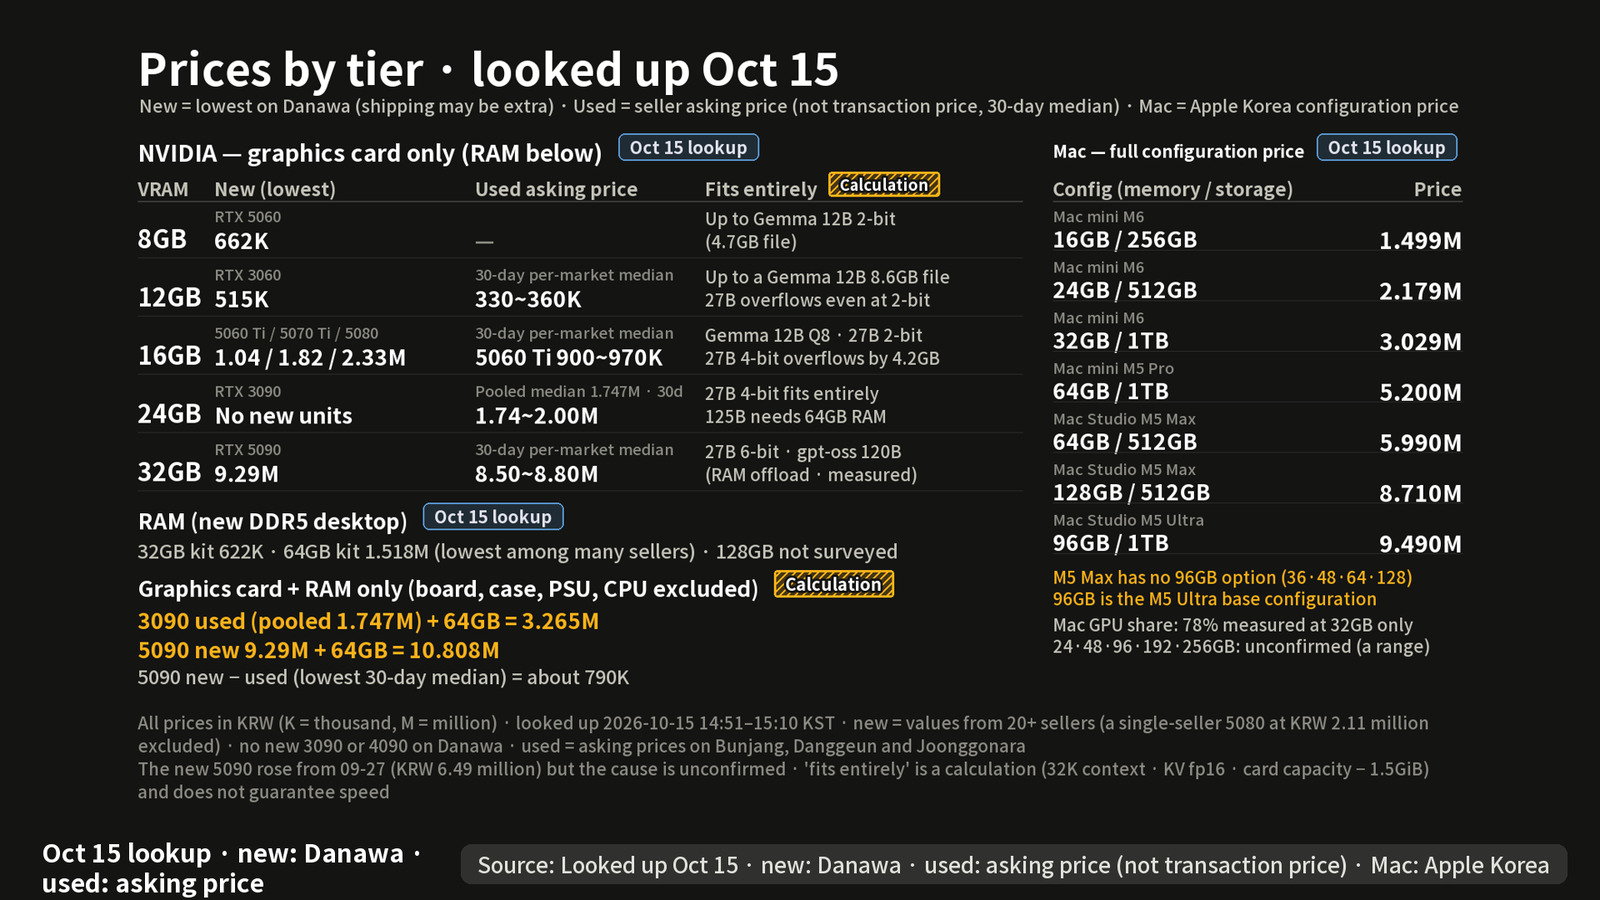
| Category | Price (KRW, in Korea) |
|---|---|
| New (lowest on Danawa) | 5060 8GB 662,000 · 3060 12GB 515,000 · 5060 Ti 16GB 1.044 million · 5070 Ti 1.819 million · 5080 2.330 million · 5090 9.290 million |
| 24GB class | no new 3090 or 4090 |
| Used asking price (per-marketplace median, last 30 days) | 3060 330,000 to 360,000 · 3090 1.74 to 2.0 million · 5090 8.5 to 8.8 million |
| DDR5 32GB kit · 64GB kit | 622,000 · 1.518 million |
| Apple Korea configuration price | Mac mini M6 32GB/1TB 3.029 million · M5 Pro 64GB/1TB 5.200 million · Mac Studio M5 Max 64GB 5.990 million · 128GB 8.710 million · M5 Ultra 96GB 9.490 million |
Storage capacity differs by configuration.
By use
This is a direction under these conditions, not a win or a loss.
- Gemma 12B at 4-bit fits entirely from a 12GB card (calculation).
- Qwen 27B at 4-bit starts at a used 3090 or a Mac mini 32GB, and the 3090 was 5.5 times faster with the same tool (our measurement).
- For Flash-Next 125B, RAM comes first. The 3090 was normal with 64GB of RAM, and at a 32GB class reading dropped to one tenth.
- A new 5090 and a used asking price differ by roughly KRW 790,000.
Limits and reference date
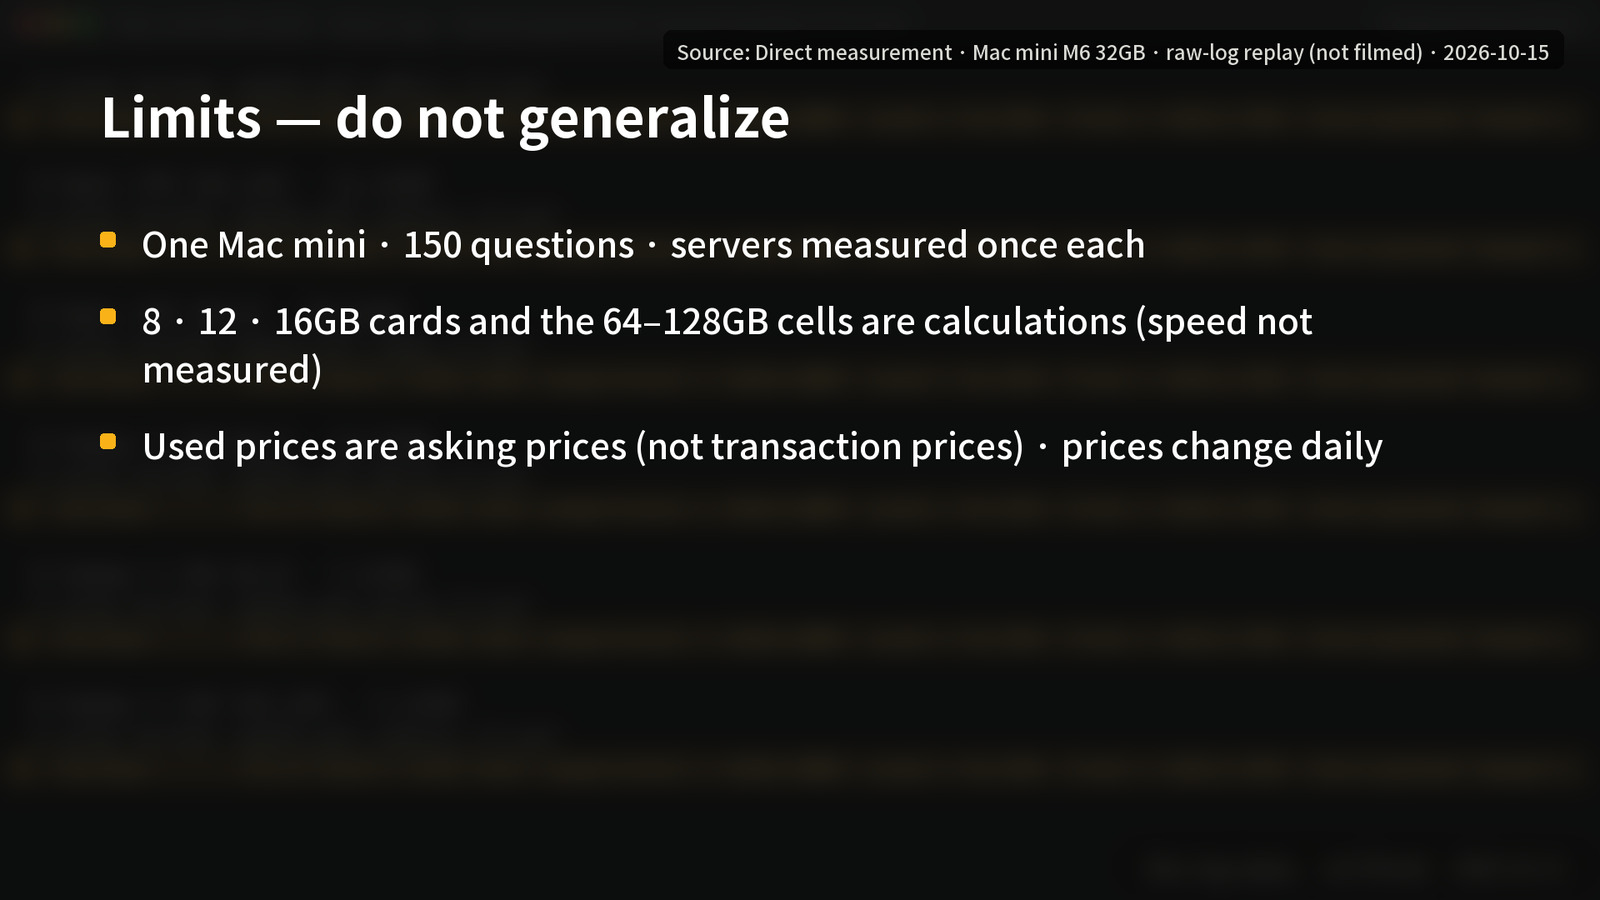
The Mac mini was one unit with 150 questions, and the servers were measured once each. The 8, 12 and 16GB cards and the Mac 24, 48 and 96GB are calculations. We could not reproduce a PC with tight RAM, and server-class models are not covered. Used prices are asking prices, and prices change daily. All prices are as looked up on October 15, 2026, the day before the video was published (2026-10-16).