Strata on RTX 3090: 5 Quantizations of 125B Measured, IQ3_S Prefill 2045 to 207 at 32GB RAM
Posted Video released
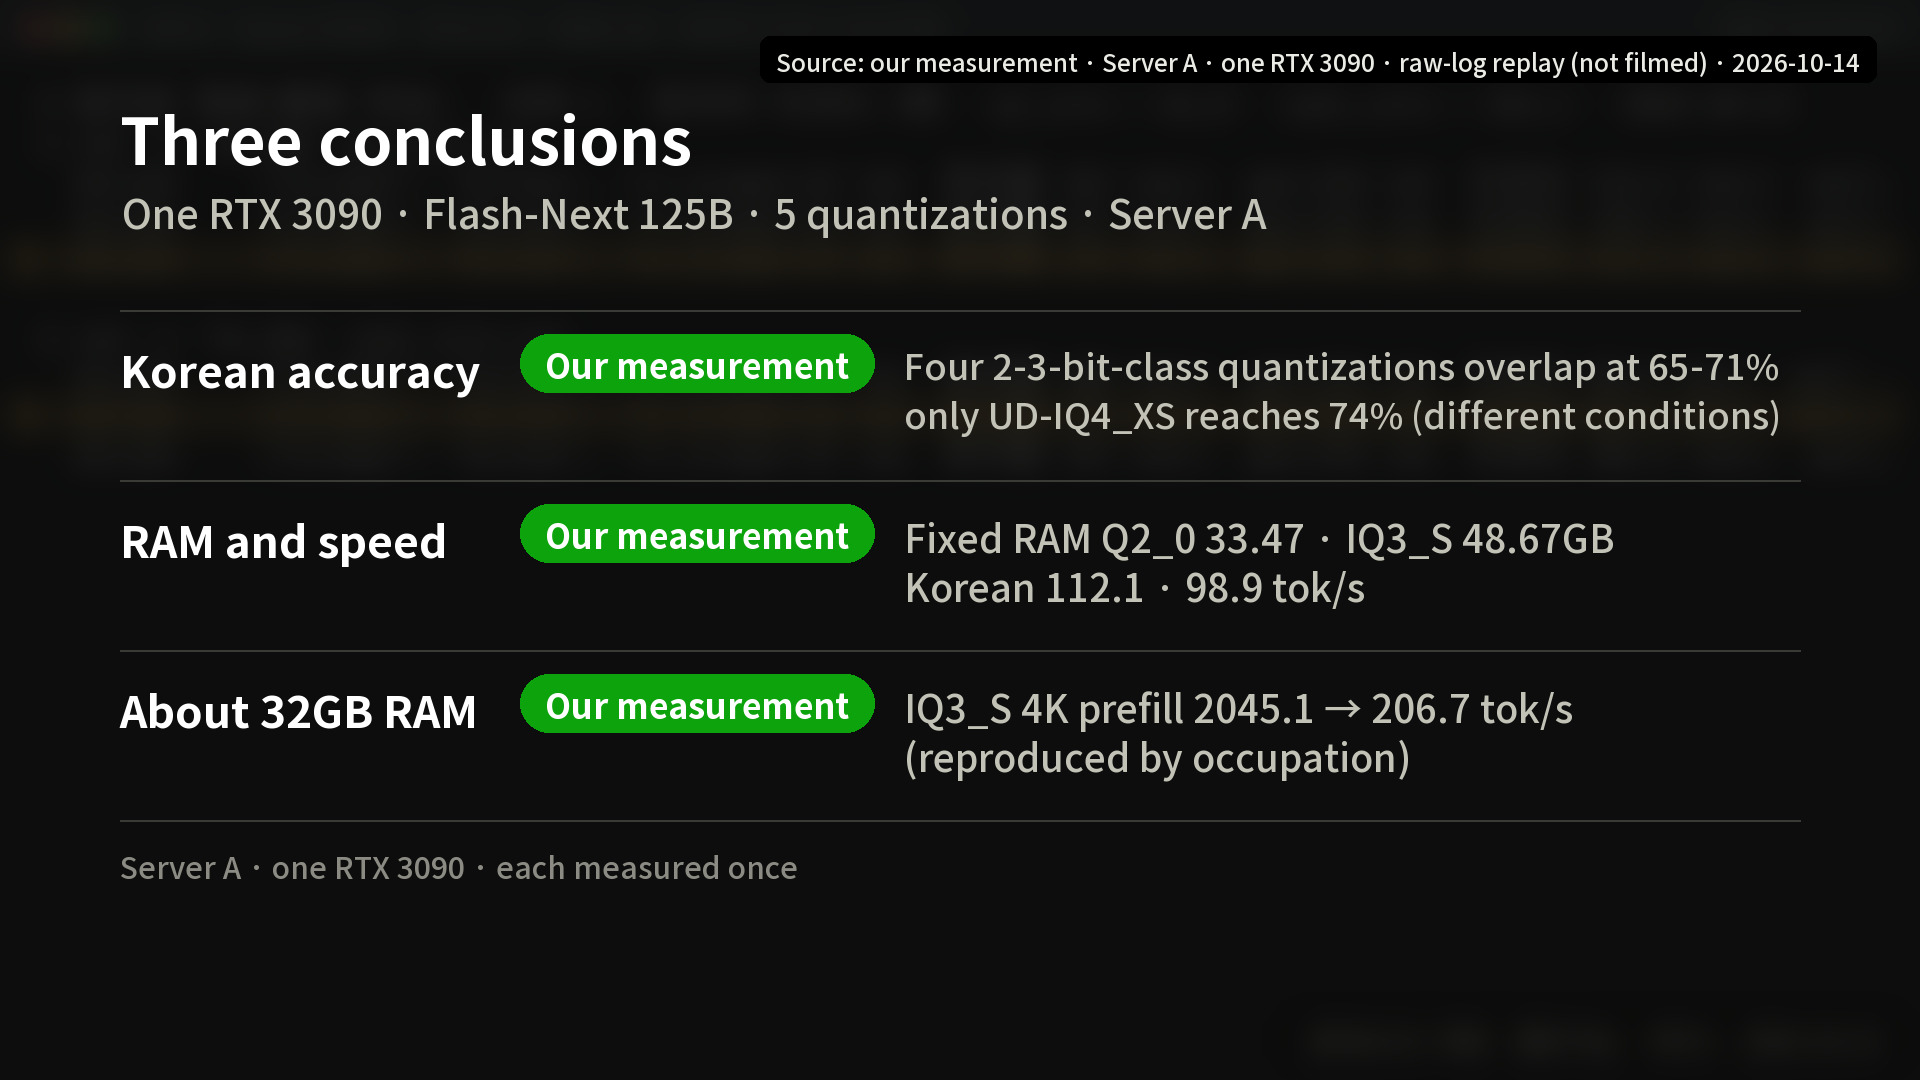
We measured five quantizations of Qwen 3.8 Flash-Next 125B with Strata on one RTX 3090. Korean accuracy overlapped; at about 32GB RAM, IQ3_S prefill fell from 2045 to 207 tok/s.
What differs among five quantizations when you run Qwen 3.8 Flash-Next (a 125B MoE) on a single RTX 3090 (24GB) with the Strata engine? We measured them ourselves on a rented cloud 3090 server. Korean accuracy overlapped a lot; what split first was RAM and speed. When we reproduced a machine with about 32GB of usable RAM, IQ3_S 4K-token prefill dropped from 2045.1 to 206.7 tokens per second. This post rewrites the content of our YouTube video as an article.
Conclusions first
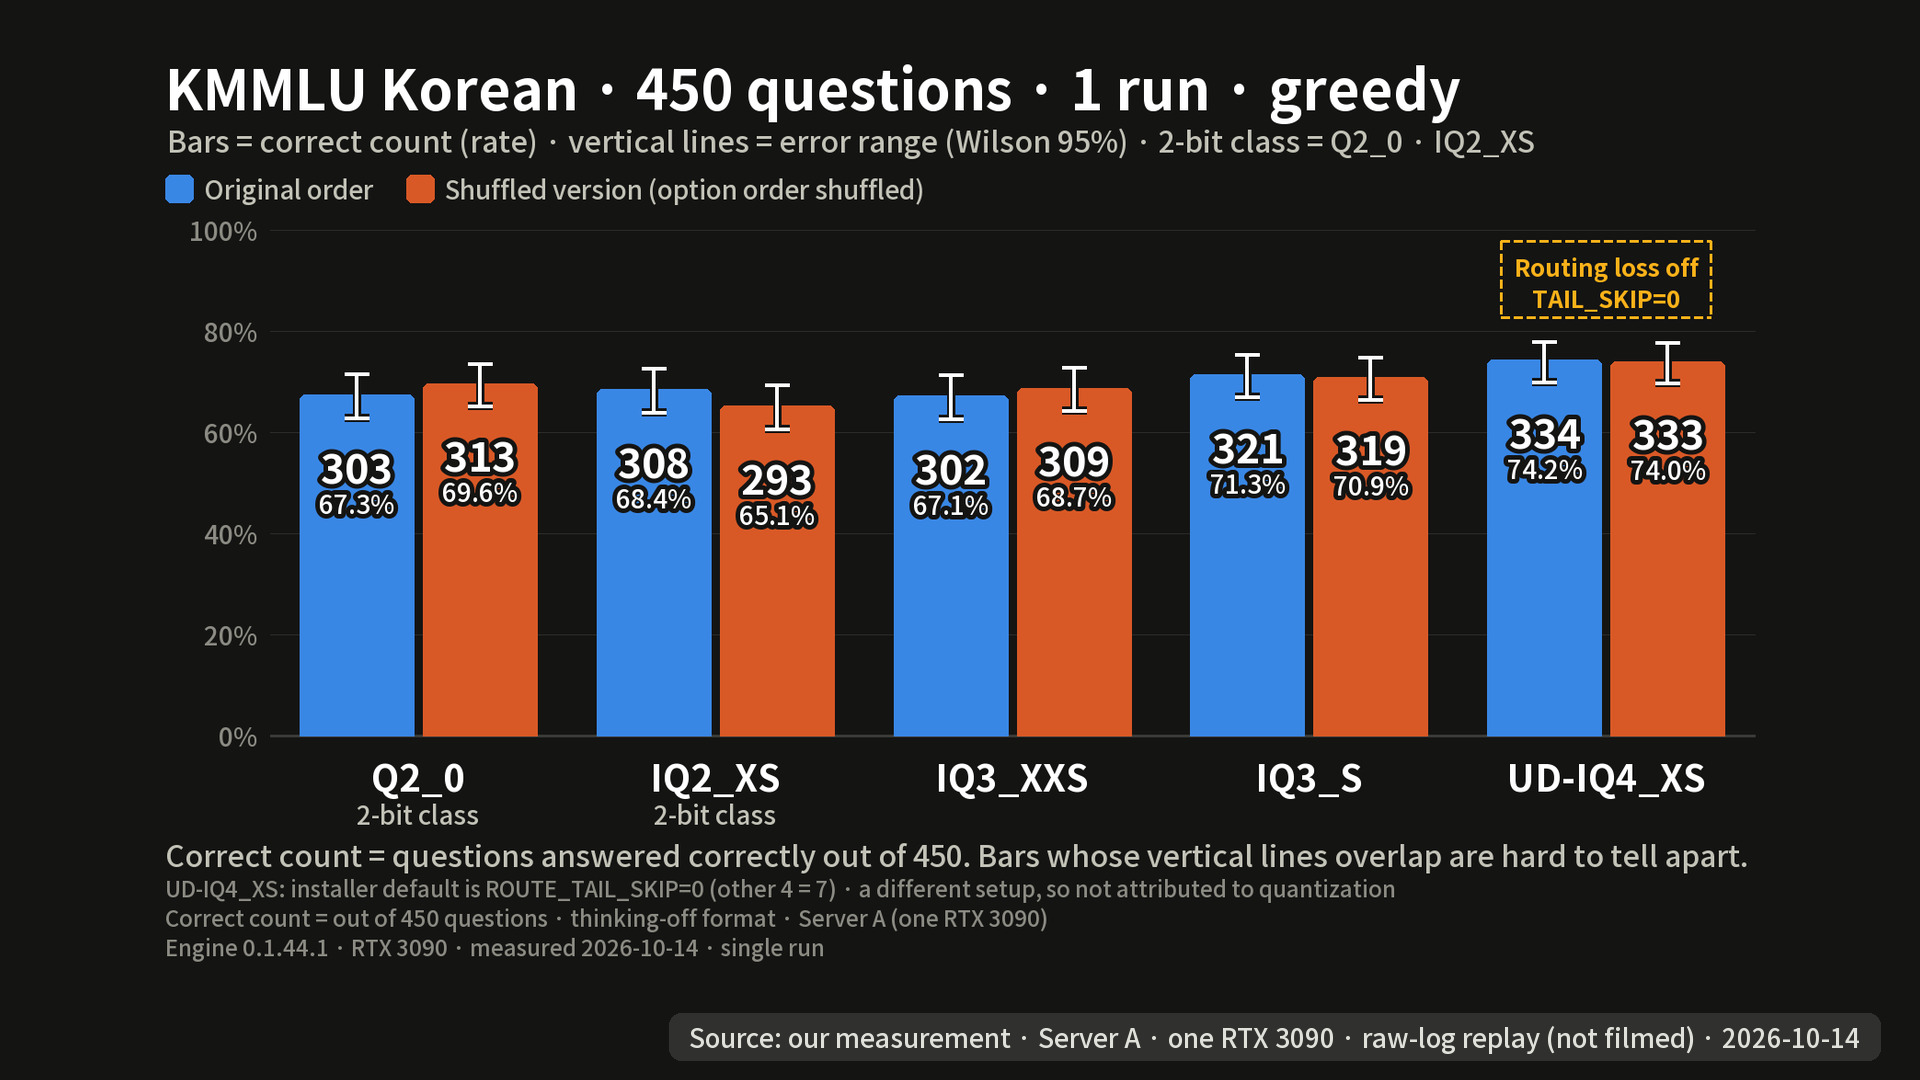
- Korean accuracy (KMMLU, 450 questions): the four 2-to-3-bit-class quantizations (Q2_0, IQ2_XS, IQ3_XXS, IQ3_S) overlapped at 65-71%. Only UD-IQ4_XS, which was run under different conditions, reached 74%.
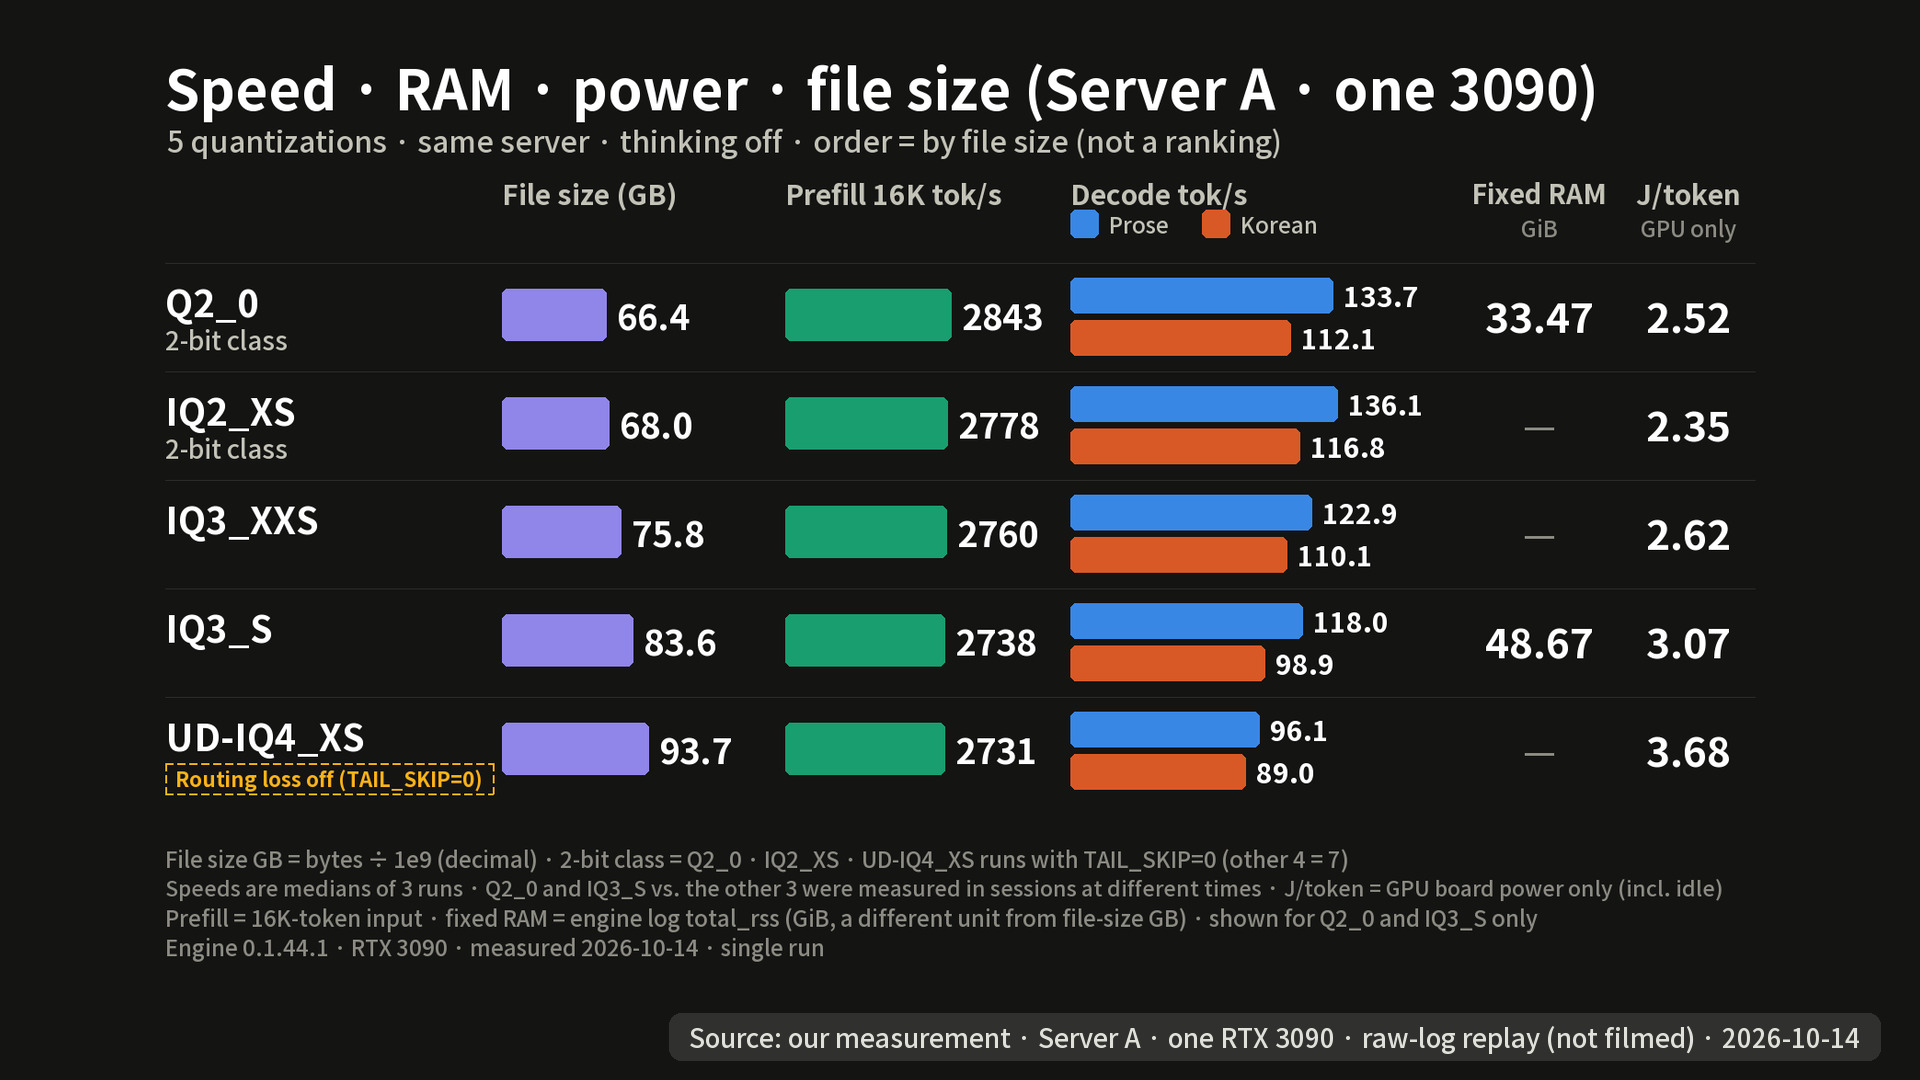
- What split first was RAM and speed. The smallest, Q2_0, had a fixed RAM of 33.47GiB and Korean decode of 112.1 tokens per second; IQ3_S had 48.67GiB and 98.9 tokens per second.
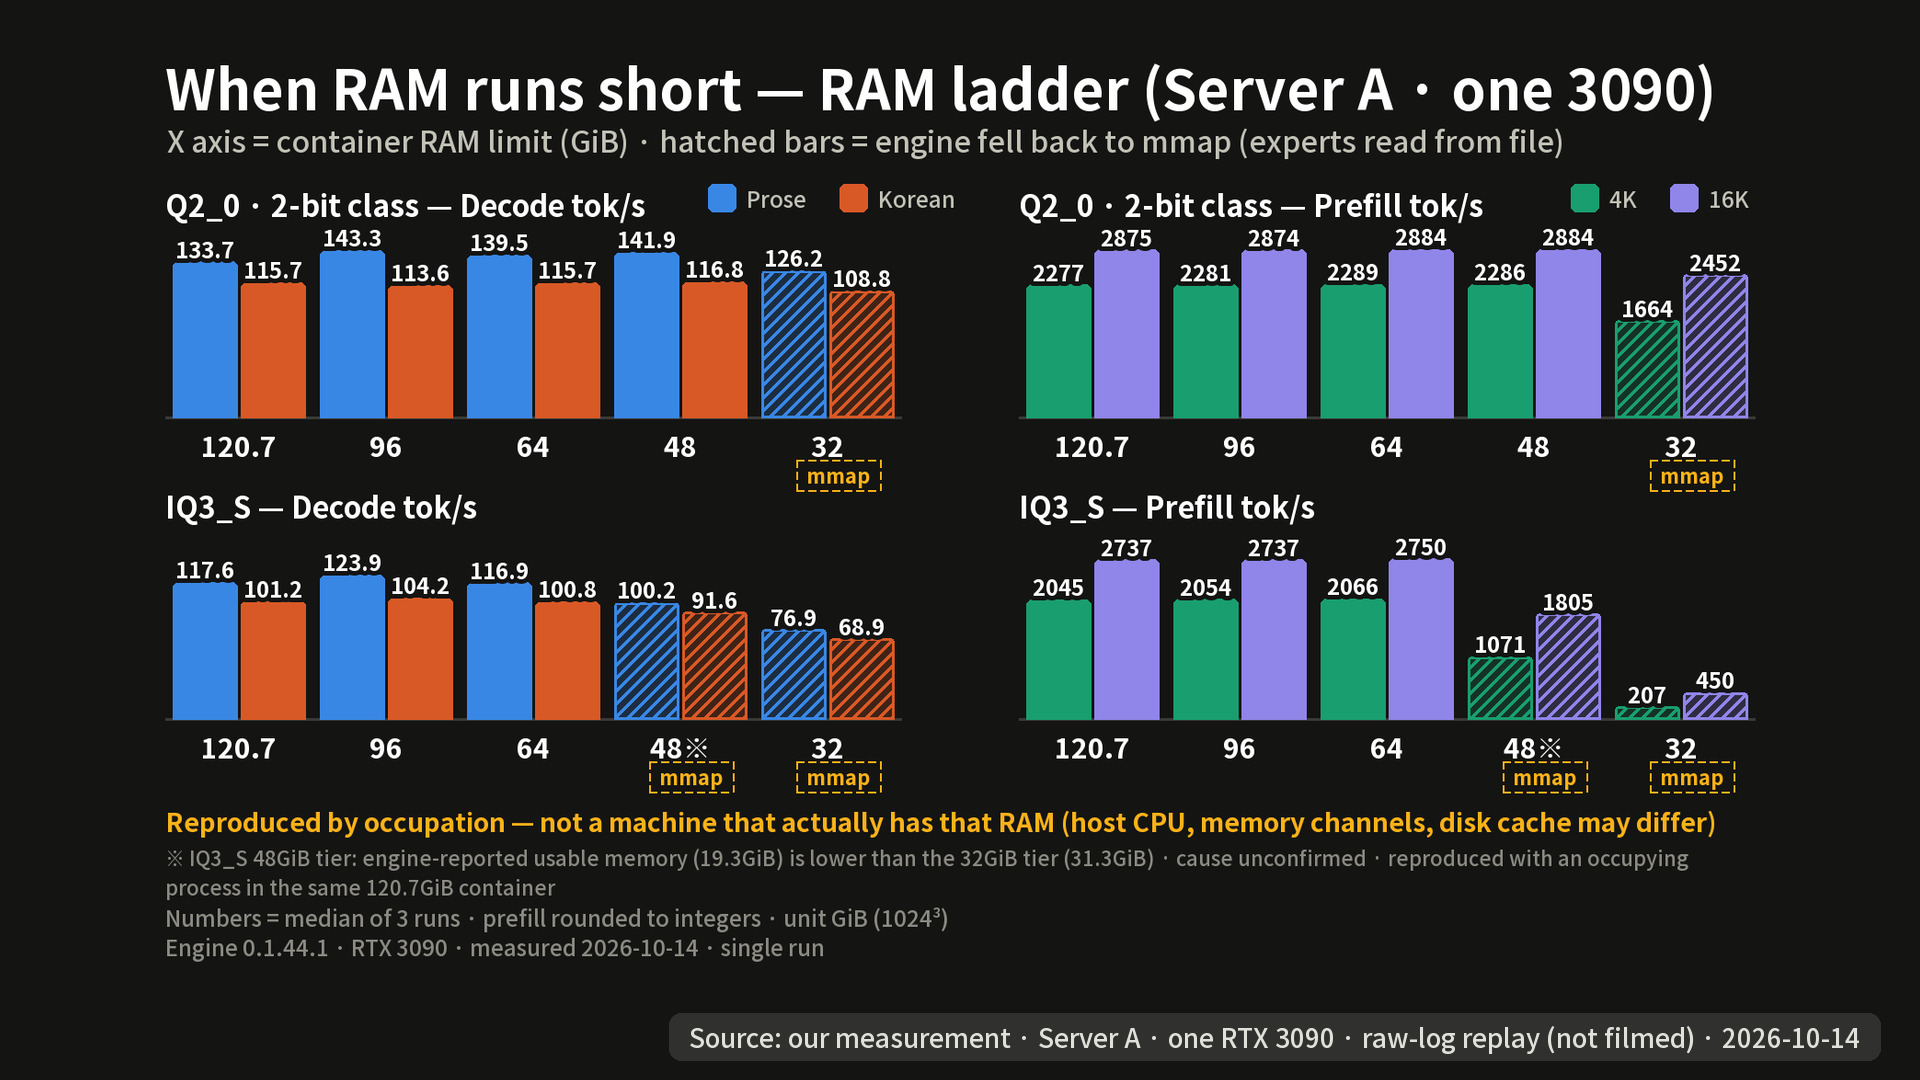
- Cutting usable RAM to about 32GB dropped IQ3_S 4K-token prefill from 2045.1 to 206.7 tok/s, while Q2_0 fell less, from 2276.8 to 1664.4.
- The video's reading is that, under these conditions, you should look at your RAM before accuracy when choosing. Every value is from a single run.
What kind of numbers these are
Almost all numbers are our measurements (server A, one run, greedy, thinking-off format). The two-card ratios are a calculation, dividing the 2-card value by the 1-card value on the same server. RAM-tier values are not from a machine that actually has that RAM; they reproduce it by shrinking usable RAM with an occupying process on the same server. We use no review measurements, official specs, or prices.
Why we measured
The video starts from reading comments: out of 77 Strata videos posted over the past month and a half, 63 had comments, about 4,600 in total (the question classification was done by hand, as a rough count). The most common question was "Will it run on my graphics card and RAM?", and as far as we looked, no video had measured Korean accuracy as a number.
Measurement conditions
Server A is a rented cloud server with a Ryzen 9 5950X, one RTX 3090 24GB, PCIe 4.0, and a 420W power limit. The engine was Strata 0.1.44.1 (the same commit for all five), context 32768, KV int8, MTP on, thinking-off format with greedy decoding (temperature 0), and speeds are the median of three runs. GGUF file sizes are Q2_0 66.4, IQ2_XS 68.0, IQ3_XXS 75.8, IQ3_S 83.6, and UD-IQ4_XS 93.7GB. Only UD-IQ4_XS ran with ROUTE_TAIL_SKIP=0 and STRATA_HC_Q8=1, so its conditions differ from the other four. The two-card tests used a different server with a Xeon CPU, PCIe 3.0, no NVLink, and a 220W limit per card, so we do not compare its absolute speeds with server A.
Korean accuracy overlapped
We had each model answer 450 KMMLU questions in the original option order and in a shuffled option order. For the 113 questions whose answer is the second option, IQ2_XS picked the second option 179 times in the shuffled version. This kind of option bias seems to have moved the values, so we do not quote only one order. The 95% confidence interval is roughly plus or minus 4 percentage points, so most of them overlap. Of the 20 pairwise comparisons, five passed the strict threshold, and four of those five involve UD-IQ4_XS, whose conditions differ, so we cannot attribute them to the quantization.
The five at a glance (server A, our measurement)
| Quantization | File GB | KMMLU original / shuffled % | Decode prose / Korean tok/s | GPU J/token | Coding 52 | Tool-call 49 (v2) |
|---|---|---|---|---|---|---|
| Q2_0 | 66.4 | 67.3 / 69.6 | 133.7 / 112.1 | 2.52 | 34 | 48 |
| IQ2_XS | 68.0 | 68.4 / 65.1 | 136.1 / 116.8 | 2.35 | 37 | 46 |
| IQ3_XXS | 75.8 | 67.1 / 68.7 | 122.9 / 110.1 | 2.62 | 40 | 48 |
| IQ3_S | 83.6 | 71.3 / 70.9 | 118.0 / 98.9 | 3.07 | 38 | 48 |
| UD-IQ4_XS | 93.7 | 74.2 / 74.0 | 96.1 / 89.0 | 3.68 | 39 | 47 |
Prefill (reading long input, 16K tokens) was nearly the same across all five, from 2843 down to 2731 tokens per second. What split was decode, which is generally slower as the file gets larger, and energy per token (GPU power only, including idle) also rose. The speeds were measured in two sessions at different times on the same server. Fixed RAM was recorded only for Q2_0 and IQ3_S.
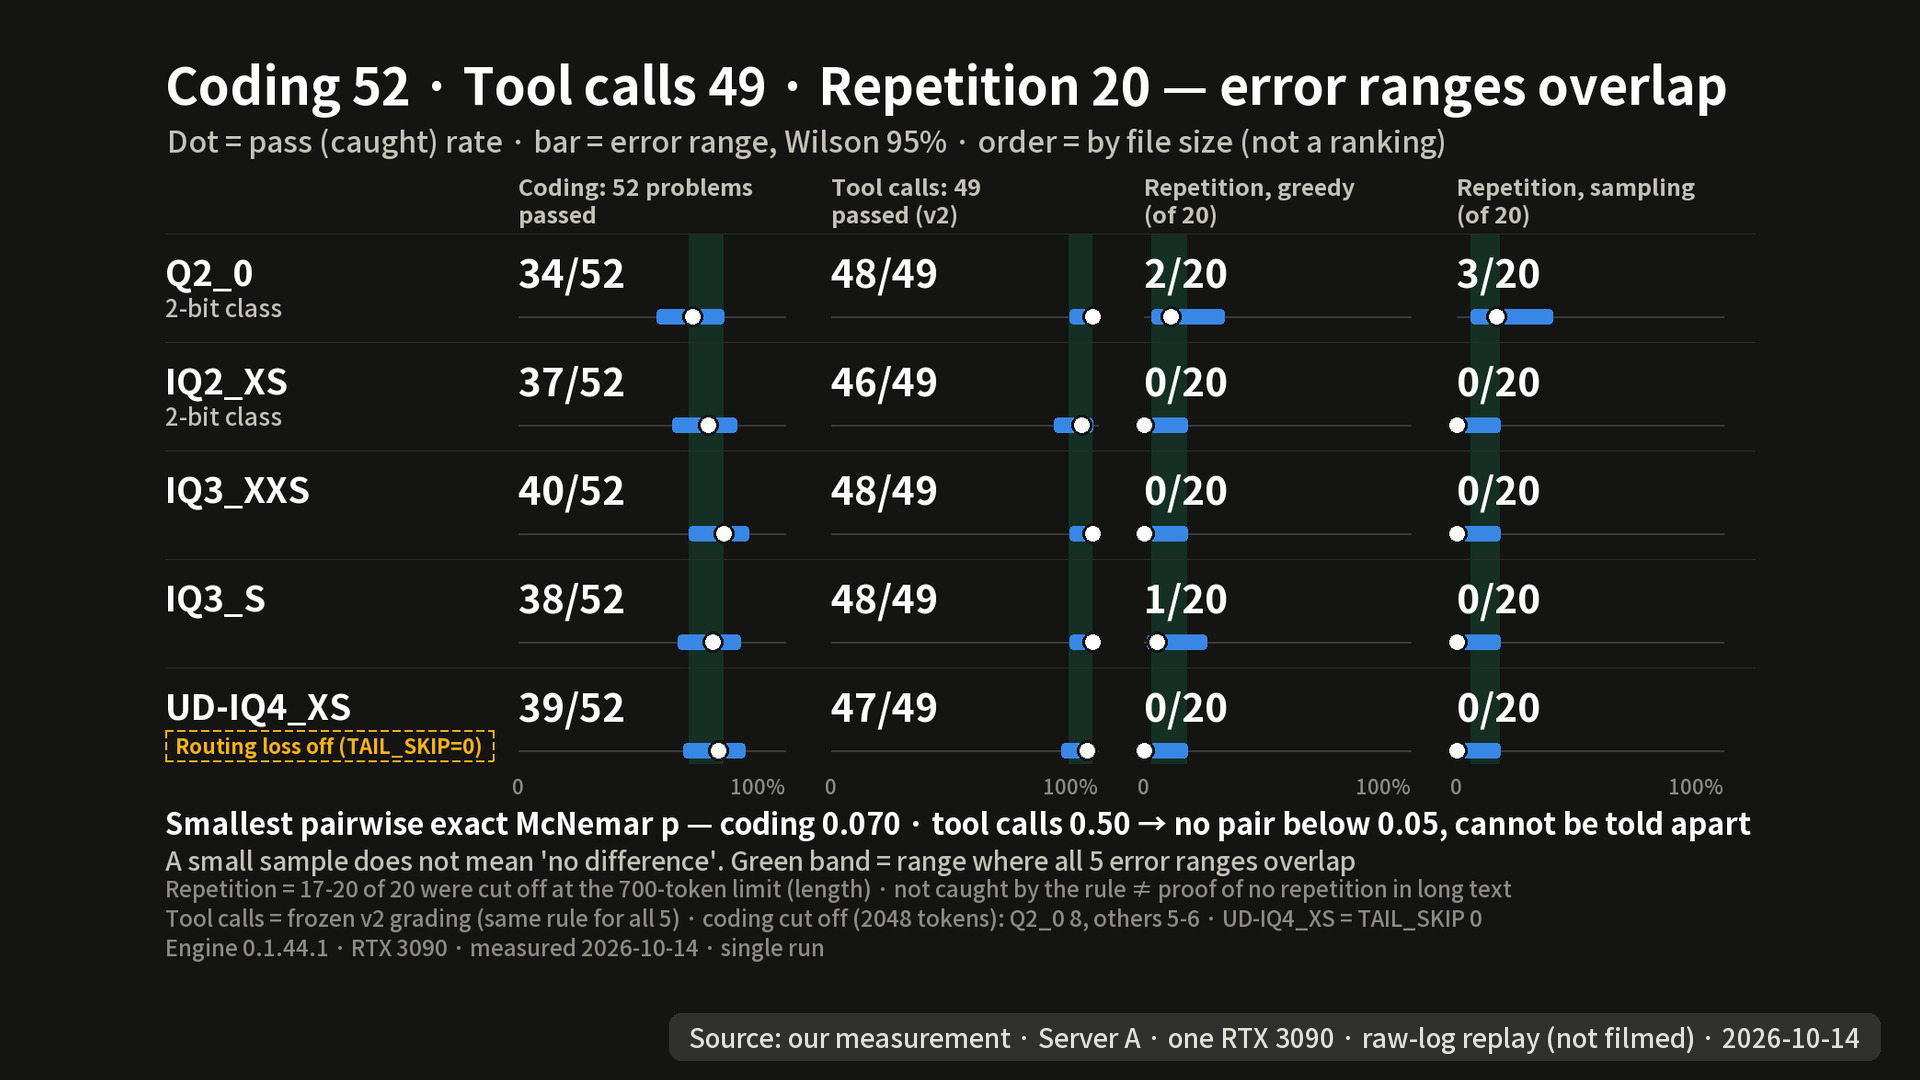
Coding, tool calls, Chinese characters, repetition
Coding passes on the 52 problems were 34 to 40, and even comparing the ten pairs as pairs, no difference exceeded the 5% threshold. Answers cut off at 2048 tokens were 8 for Q2_0, 5 for IQ2_XS, and 6 each for the rest, so a habit of ending short may be mixed into the pass rates. On the 49 tool-call tasks, 46 to 48 passed under the frozen grader v2, and one grading exception applied only to Q2_0, so we do not rank them. For Chinese-character contamination, Q2_0 had 5 answers with Chinese characters among 12 short Korean prompts and the others had 0; among 20 long 700-token prompts, it was 16 for Q2_0, 2 for IQ2_XS, and 0 for the rest. In the repetition check, 2 for Q2_0 and 1 for IQ3_S were caught under greedy and 3 for Q2_0 under sampling, but almost all answers were cut off at 700 tokens, so this must not be read as meaning no repetition occurs in long text.
When RAM runs short
On the same server A, we shrank usable RAM with an occupying process and reproduced only two quantizations, Q2_0 and IQ3_S. When RAM runs short, the engine drops from the normal mode, which keeps all experts in RAM, to a mode that reads experts from the file (mmap).
| Usable RAM | Q2_0 decode avg / 4K prefill | IQ3_S decode avg / 4K prefill |
|---|---|---|
| Natural (about 120GiB) | 124.7 / 2276.8 | 109.4 / 2045.1 |
| 96GiB | 128.4 / 2281.4 | 114.1 / 2054.2 |
| 64GiB | 127.6 / 2289 | 108.8 / 2066 |
| 48GiB | 129.3 / 2285.5 | File-read mode, number omitted (cause unconfirmed) |
| About 32GiB | 117.5 / 1664.4 (file-read mode) | 72.9 / 206.7 (file-read mode) |
Decode is the average of prose and Korean. Q2_0 stayed in normal mode down to 48GiB and dropped at about 32GiB; IQ3_S stayed normal down to 64GiB and dropped from 48GiB. We did not use the IQ3_S 48GiB tier because we could not confirm the cause of the available amount the engine reported.
One more card
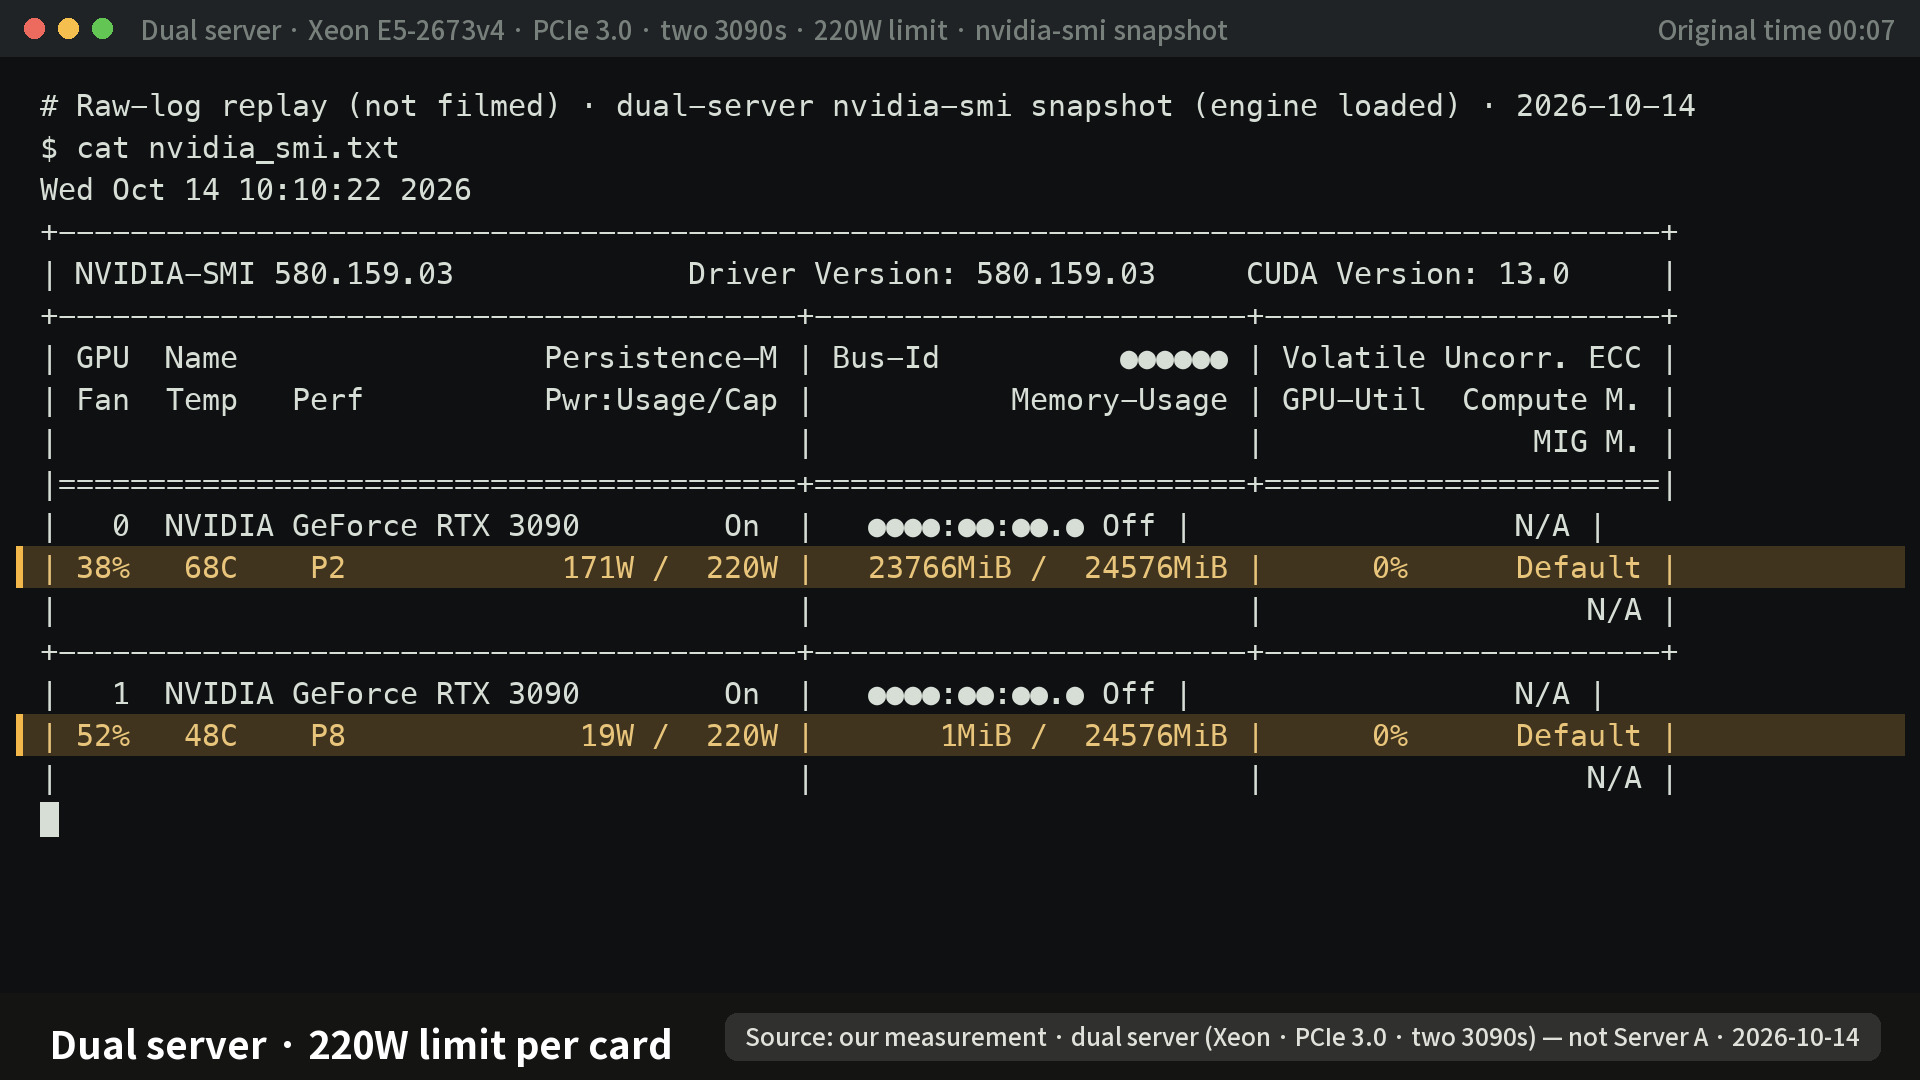
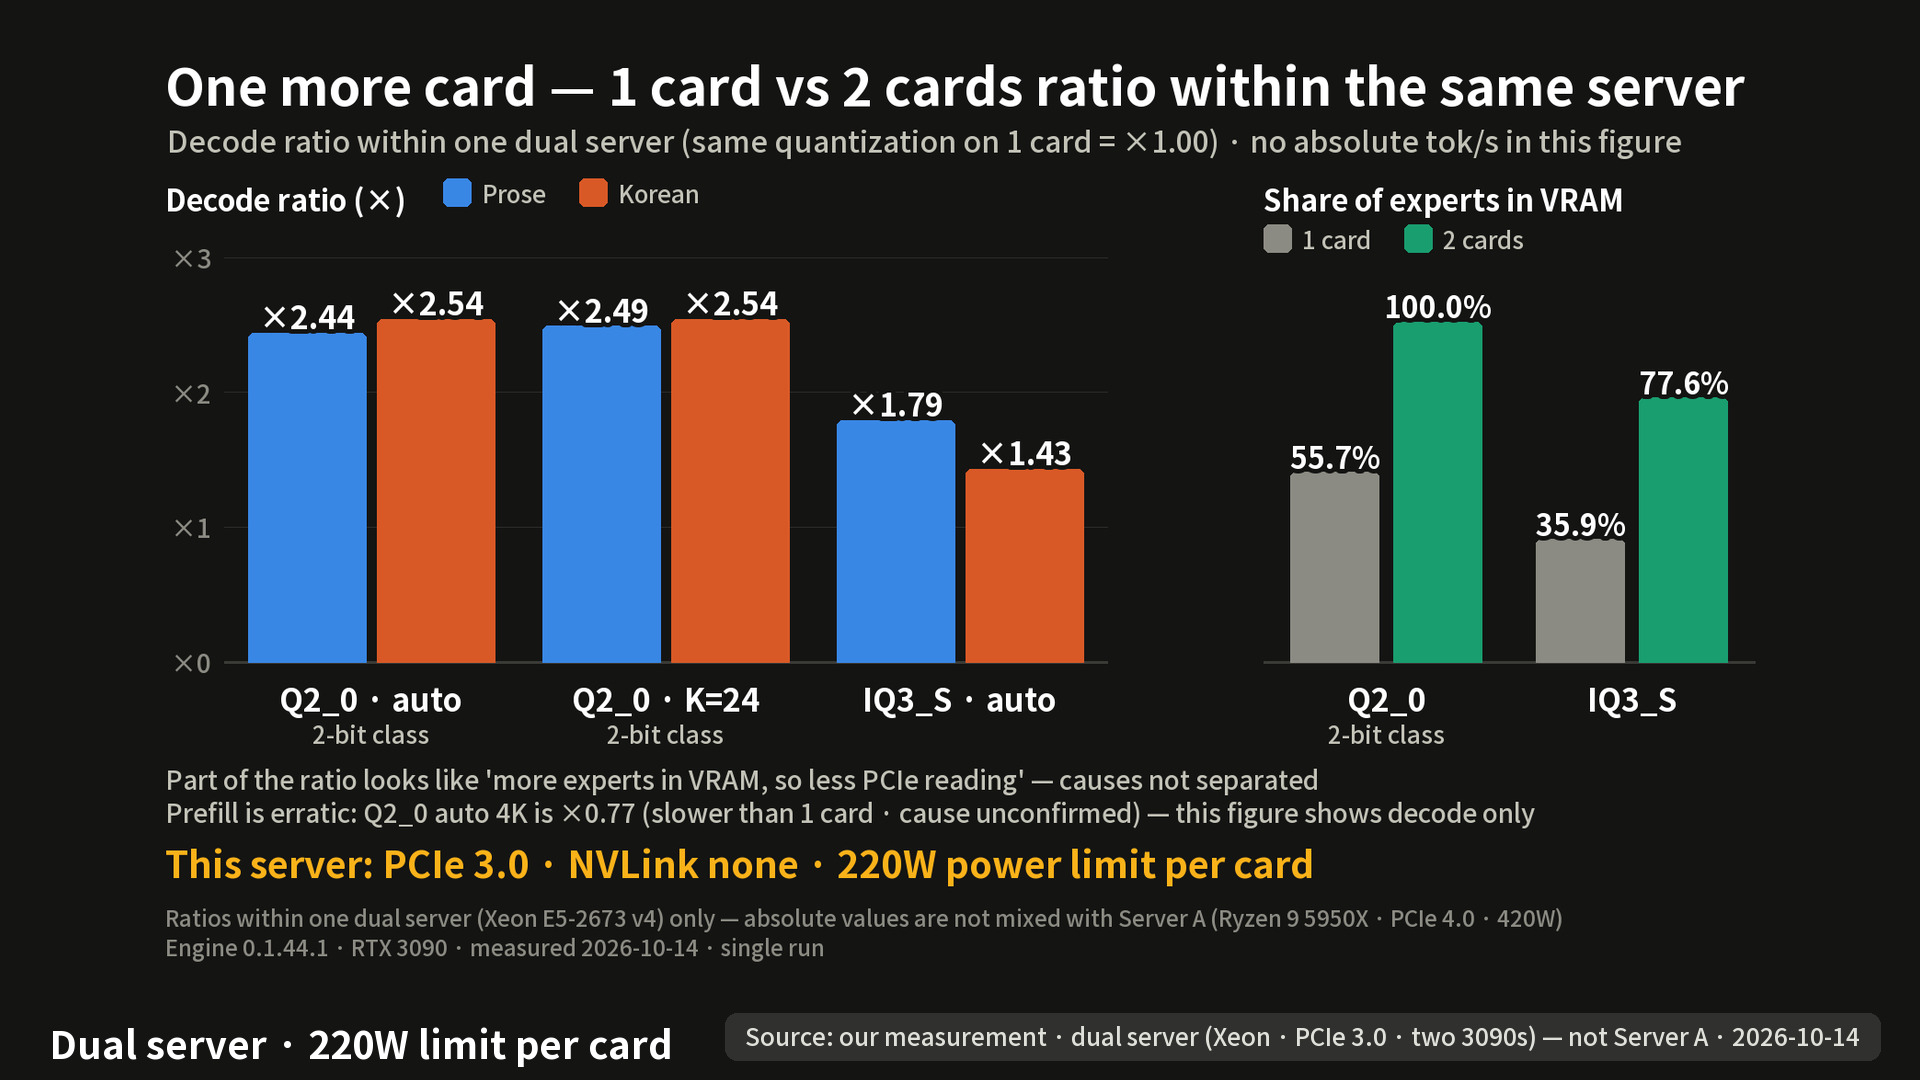
These are ratios comparing only 1 card against 2 cards on the same server, a different server with two 3090s. This server has PCIe 3.0, no NVLink, and a 220W power limit per card.
Prose decode was 2.44x for Q2_0 (2.49x when we set the split by hand) and 1.79x for IQ3_S. These ratios mix card compute with the effect of all experts fitting into graphics card memory, and we did not separate the causes. The share of experts placed in graphics card memory went from 55.7% to 100% for Q2_0 and from 35.9% to 77.6% for IQ3_S. The Q2_0 4K prefill was actually 0.77x with two cards, and we could not confirm why.
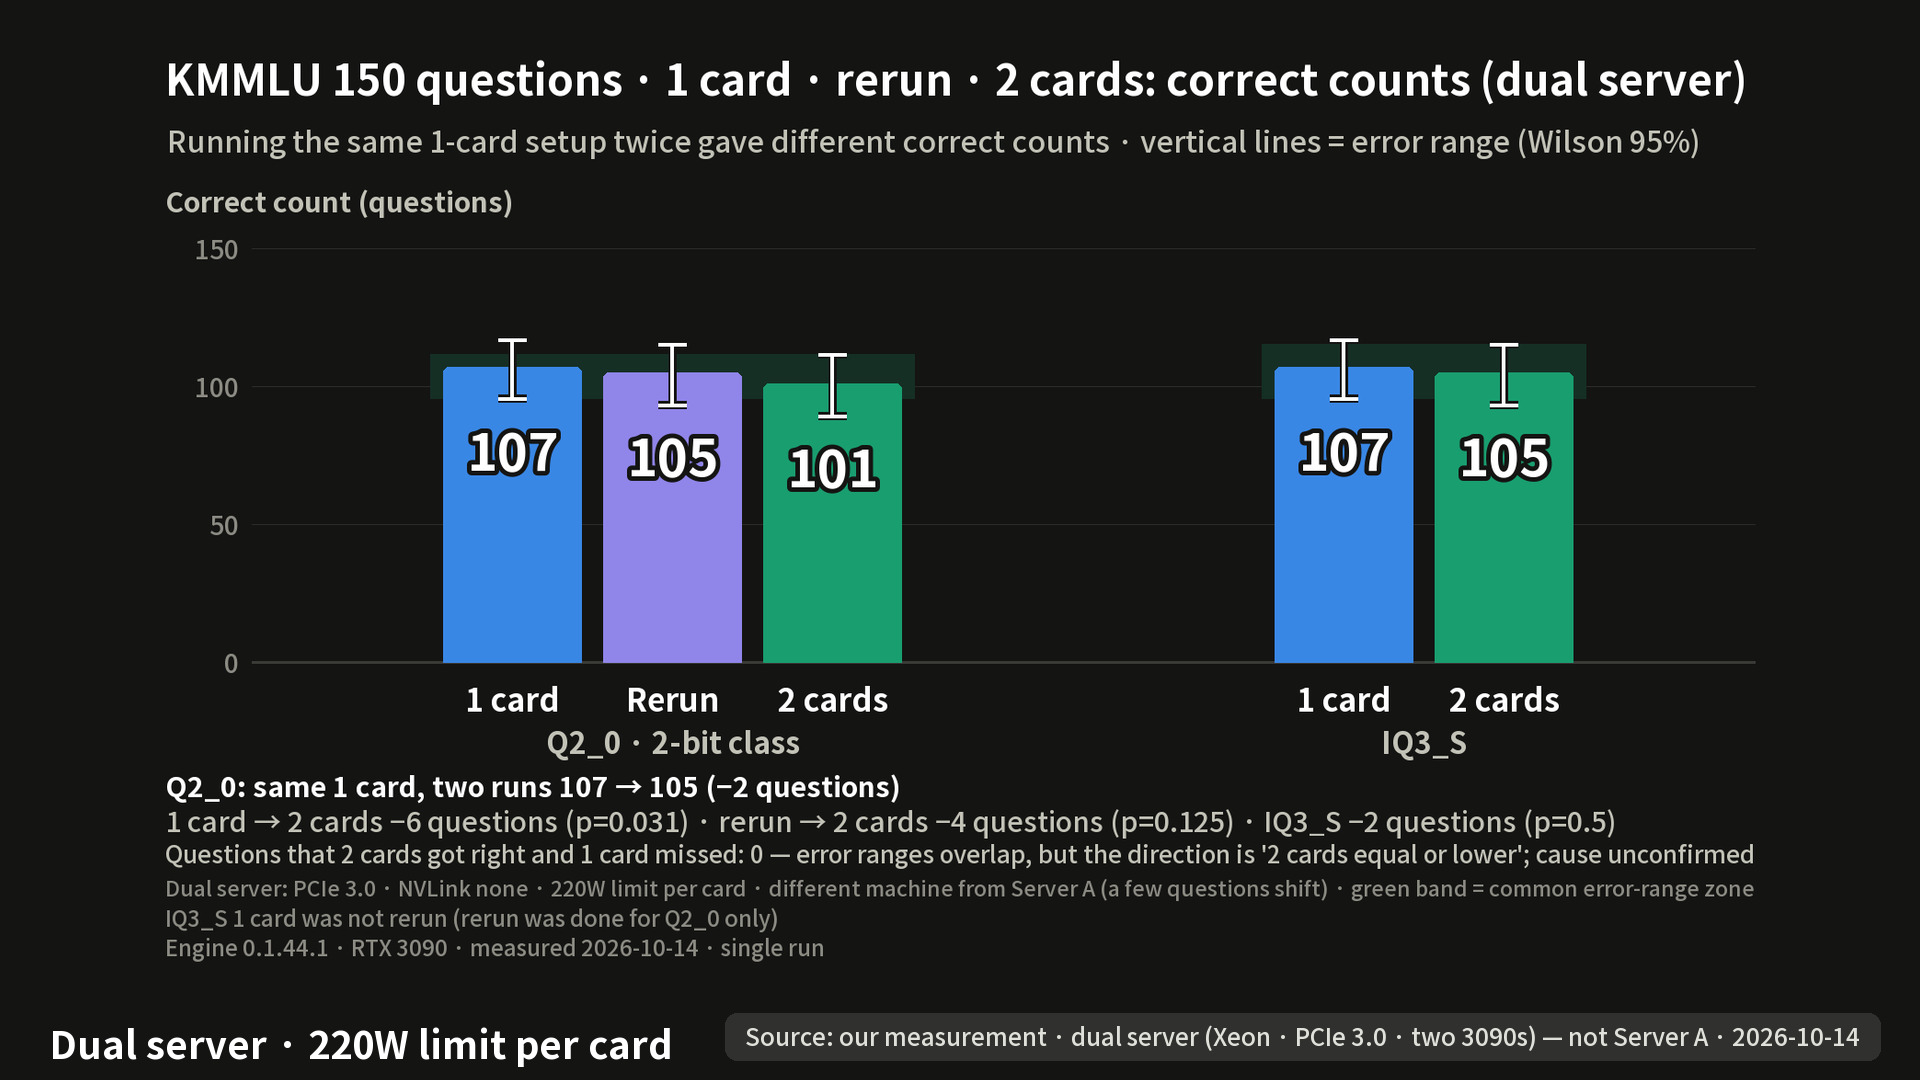
On the 150-question KMMLU subset, Q2_0 scored 107 with one card, 105 when the same one-card run was repeated, and 101 with two cards; IQ3_S scored 107 with one card and 105 with two. The two-card side came out 2 to 6 questions lower. The same one-card run also wobbled by 2 to 3 questions, so this may be within that spread, but the first Q2_0 comparison (107 vs 101) split 6 to 0 with p = 0.03. The cause may be how the model was split across cards, but we could not confirm it, so we do not claim that two cards leave accuracy unchanged. There were 0 questions that two cards got right and one card did not, for both quantizations.
Limits and reference date
- Every test is a single run, greedy, thinking-off format. The two 2-bit-class quantizations, 12 Chinese-character prompts, 20 repetition prompts, 52 coding problems, and 49 tool-call tasks are small samples and cannot be generalized.
- Server A values and dual-server values are not mixed, and the RAM-tier values are reproduced by occupation, so they can differ from a machine that really has that RAM (host CPU, memory channels, disk cache).
- UD-IQ4_XS ran under different conditions, so we cannot attribute its results to quantization.
- Reference date: measured and published 2026-10-14 to 15 (video published 2026-10-15). The engine was Strata 0.1.44.1.
Summary
- Accuracy overlapped within the error ranges; when RAM runs short, IQ3_S dropped sharply while Q2_0 dropped gently.
- Adding a second card gave 1.79x to 2.49x on this server, but memory effects are mixed in and it cannot be carried over to other setups as is.