Seedance 2.5 vs Wan 3.0: Is 3.7x the Price Worth It? A 4-Round Comparison
Posted Video released
Seedance 2.5 and Wan 3.0 compared over four rounds with the same prompts: 9 passes vs 8, 21,560 vs 6,240 credits (3.5x). Wan for Korean dialogue, Seedance for cel animation.
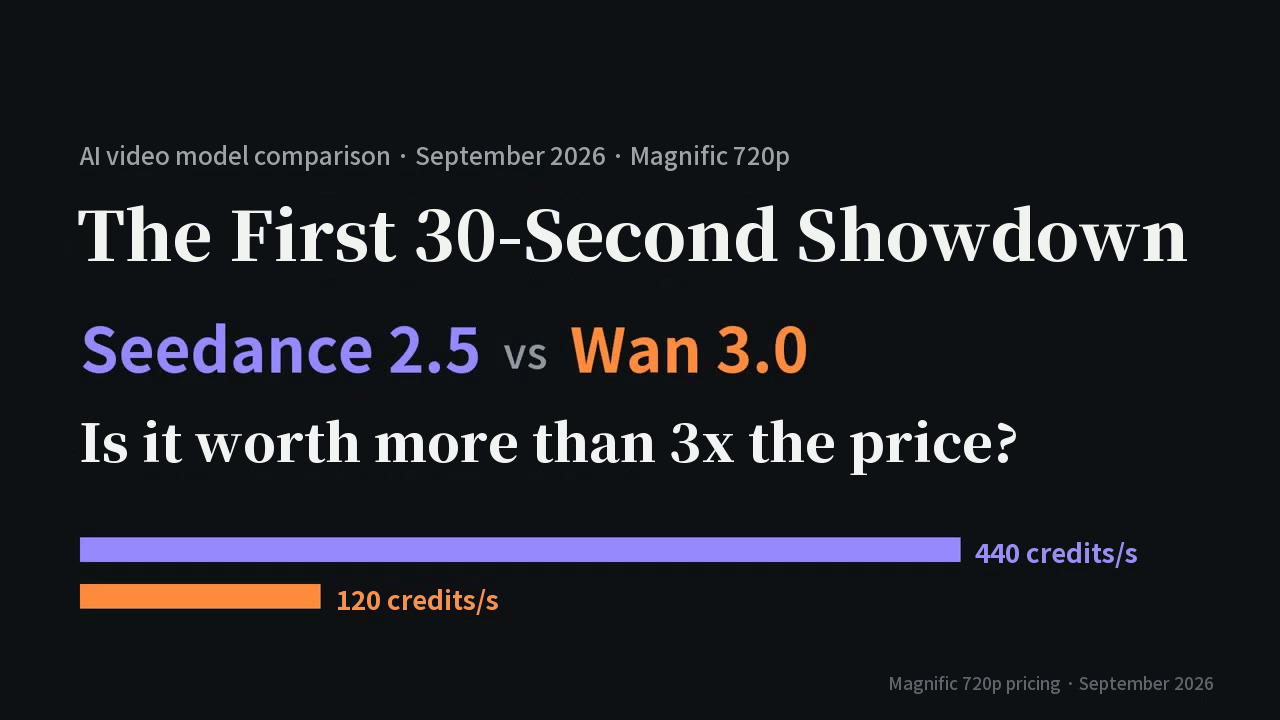
Seedance 2.5 and Wan 3.0 are both AI video models that can generate up to 30 seconds at a time, with sound. At the same Magnific 720p setting, Seedance costs 440 credits per second and Wan 120, a 3.7x difference. The video put the same prompts into both models, ran four rounds, and asked whether the price is worth it. This post rewrites those results together with the method and its limits. It is as of the video's publication date, 2026-09-15, and prices and rankings are September 2026 values.
The short answer
- Across 12 verdicts in four rounds, Seedance got 9 passes and 3 holds, and Wan got 8 passes and 4 holds, with no fails for either.
- Generating one take each cost Seedance 21,560 credits and Wan 6,240, about 3.5x. The video sums it up as more than triple the price for a one-pass lead, so Seedance's price was not always justified in these four rounds.
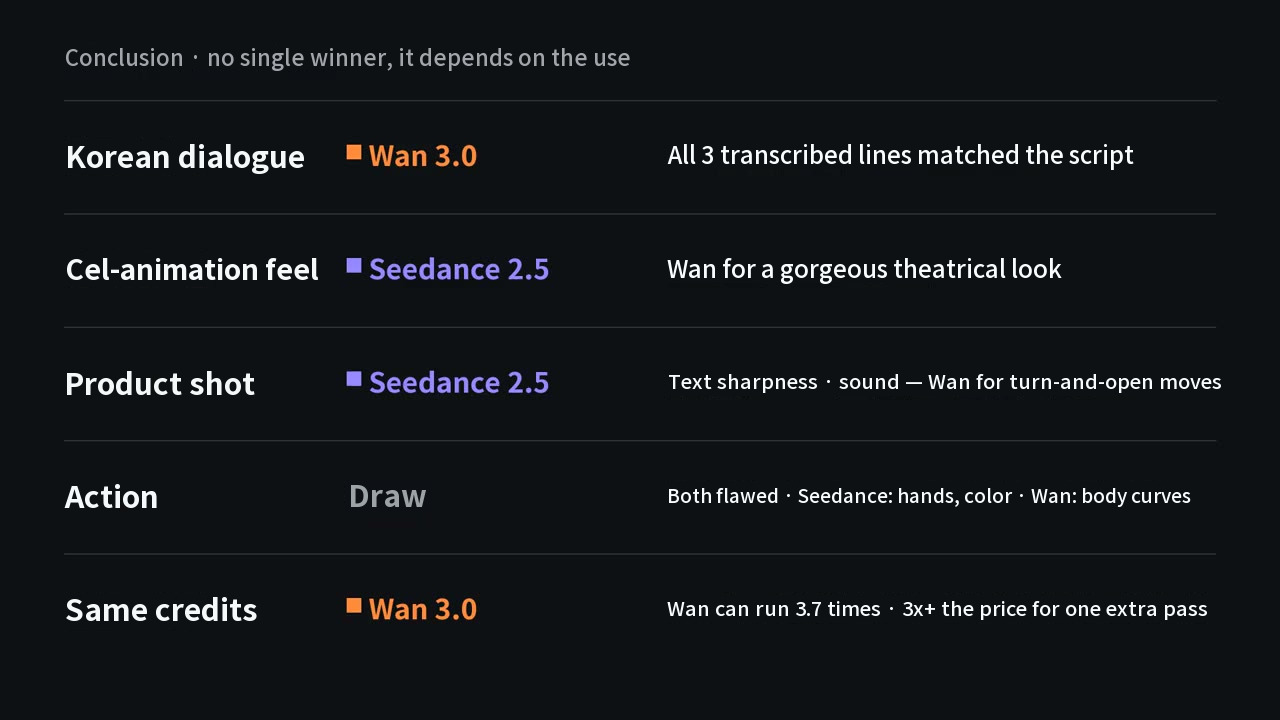
- There is no single winner; it depends on the use. Korean dialogue goes to Wan, the cel-animation feel and product-text sharpness go to Seedance, and action is a draw because both have flaws.
What kind of numbers these are
- Our measurement: credit consumption (from the Magnific screen), color richness, speech-to-text, text recognition (OCR), face recognition and sound analysis
- Review measurement (other people's tallies): blind-vote rankings from Artificial Analysis (checked 2026-09-14) and arena (updated 2026-09-04)
- Official: release dates and input limits (ByteDance Seed blog, Alibaba Cloud documentation, Atlas Cloud, September 2026) and the Magnific 720p pricing
- Calculation·estimate: 3.7x, 3.5x, credits for a 30-second piece, and ratios against the monthly credits
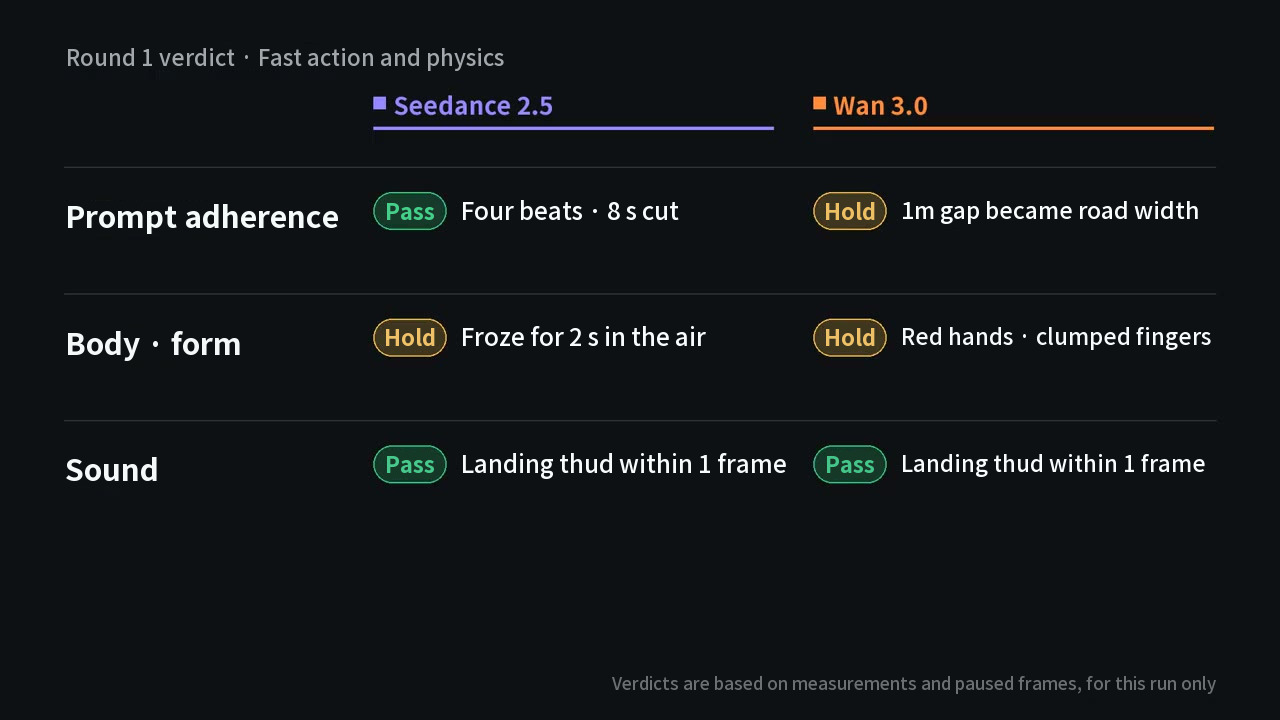
The clips were generated on Magnific at 16:9 720p, with the same prompt given to both models as text only, with no reference images. On screen, Seedance was always on the left and Wan on the right, and each round was judged as pass, hold or fail on three points: prompt adherence, body and form, and sound. The verdicts are "based on measurements and paused frames, for this run only."
The two models at a glance
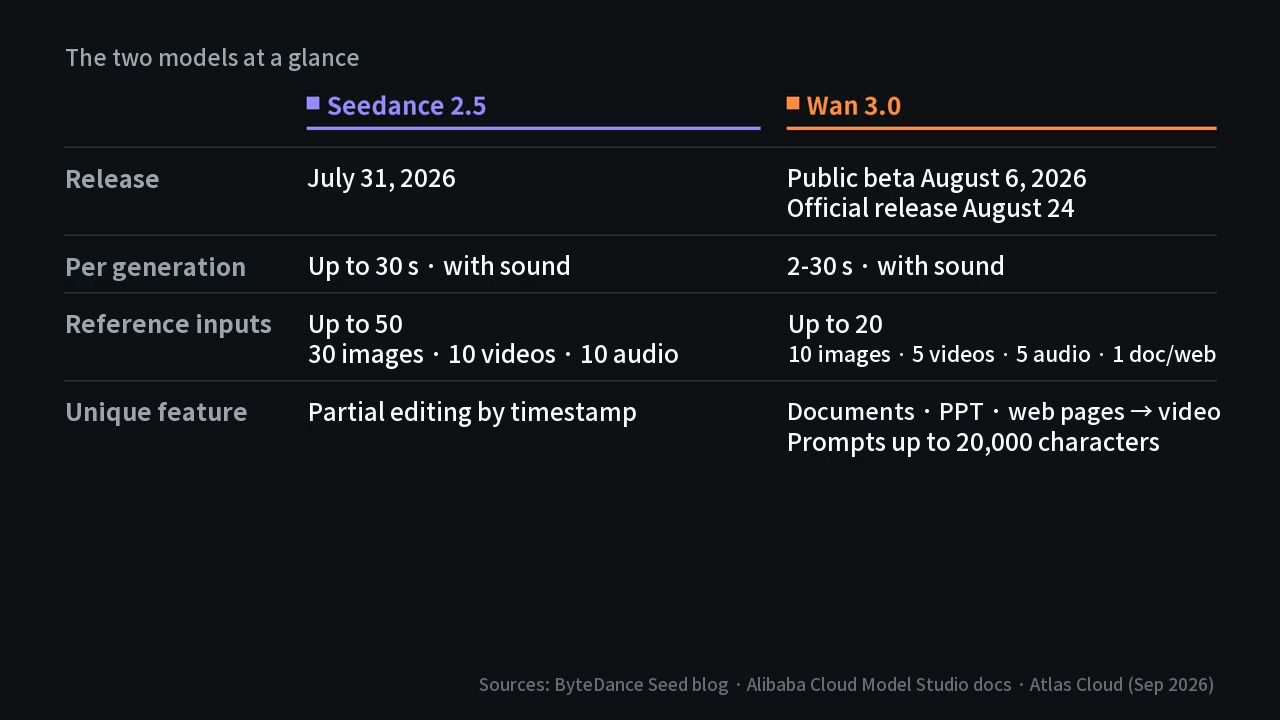
| Item | Seedance 2.5 | Wan 3.0 |
|---|---|---|
| Release | July 31, 2026 | Public beta August 6, 2026; official release August 24 |
| Per generation | Up to 30 seconds, with sound | 2-30 seconds, with sound |
| Reference inputs | Up to 50 (30 images, 10 videos, 10 audio) | Up to 20 (10 images, 5 videos, 5 audio, 1 document or web page) |
| Unique feature | Partial editing by timestamp | Turns documents, PPT and web pages into video; prompts up to 20,000 characters |
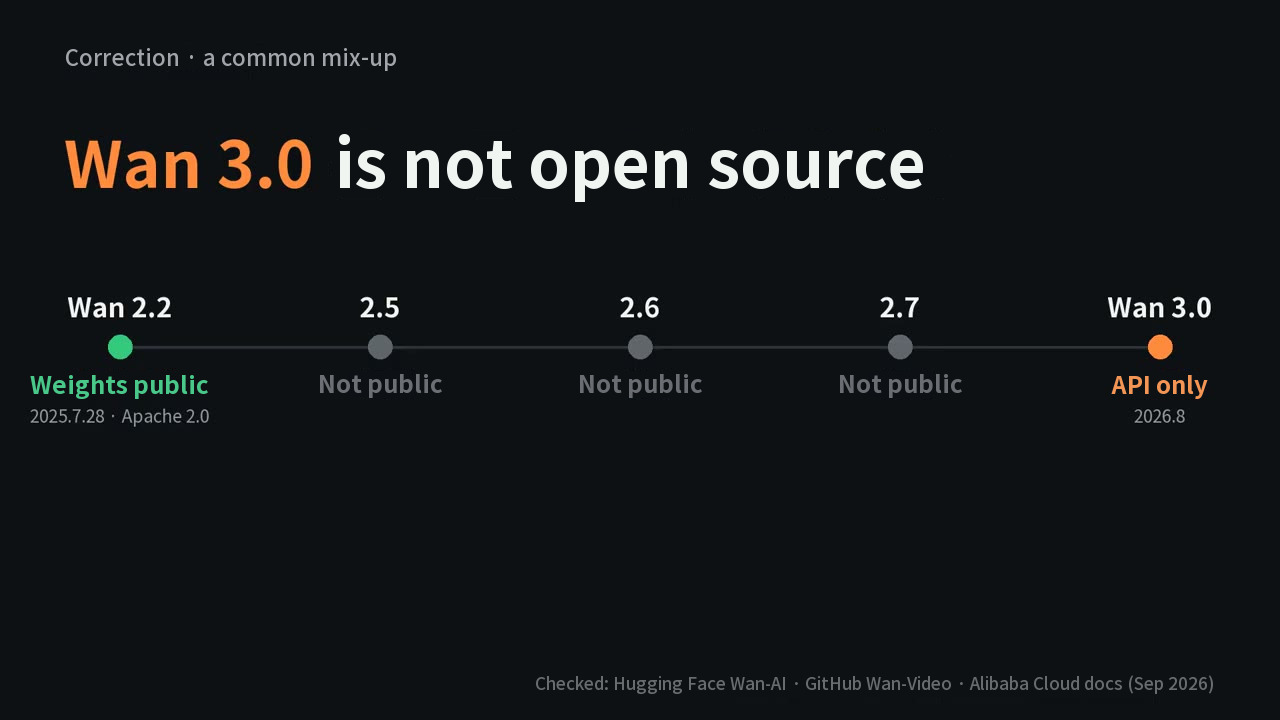
Neither model's weights are public. The video stresses one correction in particular: Wan 3.0 is not open source. The last major model with public weights was Wan 2.2 in July 2025 (Apache 2.0), and the four generations from 2.5 to 3.0 are available only through an API. You must not apply Wan 2.2's license to 3.0.
Blind-vote rankings need a date attached. In the Artificial Analysis text-to-video ranking as of 2026-09-14, Wan 3.0 was first and Seedance 2.5 was not yet on the list. In the arena ranking updated on September 4, Wan was third and Seedance 2.5 720p sixth, but the video explains that the margins of error overlap, so they are effectively in the same class.
Cost breakdown
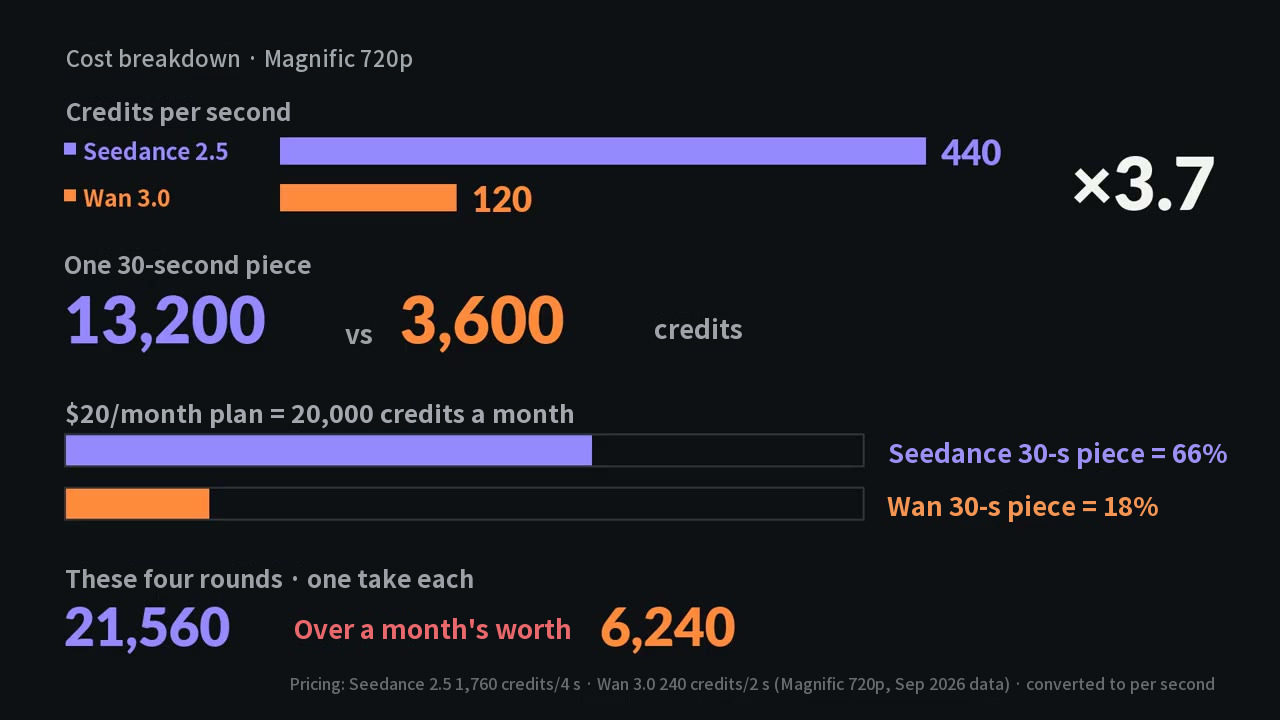
Pricing is 1,760 credits per 4 seconds for Seedance 2.5 and 240 credits per 2 seconds for Wan 3.0, which converts to 440 vs 120 per second (3.7x). A 30-second piece is 13,200 vs 3,600 credits. Magnific's 20-dollar monthly plan gives 20,000 credits a month, so one 30-second Seedance piece uses 66% of a month and Wan 18%. Generating the four rounds once each cost Seedance 21,560 credits, more than a month's worth, and Wan 6,240.
The video says what people really want to know is not the price of one take but the price of "a usable take" (credits per take x takes generated / takes that passed). But this episode generated only one take per round, so we could not work out the real unit price including re-rolls.
Round 1: Fast action and physics
A 15-second clip of running across a rainy Seoul rooftop, jumping a 1-meter gap, landing in a roll and catching breath at the railing (6,600 vs 1,800 credits).
- Impression: Wan is bright and vivid. Measured color richness was 1.6x higher on Wan, while Seedance had the muted look of an overcast Seoul day.
- Motion: In the jump's slow motion, Seedance froze for 2 seconds with the foot height and pose unchanged. Wan kept a living arc up and down and completed the forward roll after landing. In exchange, Wan stretched the 1-meter gap to the width of a road with cars on it.
- Hands: Seedance's two hands on the wet floor looked natural down to the finger joints. On Wan the hands turned red as if wearing red gloves, became a clump with indistinguishable fingers in the air at 8 seconds, and returned to skin color only after 10 seconds.
- Text and face: The Korean sign Wan drew read, when enlarged, as a nonsense word (걱식싱) that looks like Korean but means nothing. Comparing faces with a recognition model, Wan came out as the same person, while Seedance could not be measured because hair covered the face.
- Sound: Both landing thuds matched the frame where the foot touches within one frame. Seedance was nearly mono and Wan was stereo.
Round 2: A two-person dialogue and Korean lip-sync
A 12-second conversation between a 60-something owner and a customer just off work at a late-night gimbap shop (5,280 vs 1,800 credits; the Wan version came out at 15 seconds). The focus was pronunciation and intonation.
We transcribed the lines with a speech-to-text model (faster-whisper large-v3) and compared them with the script. Wan matched the script on all three lines, not one character off. For Seedance, the last line "I'll give you one more" was transcribed as a different word both times. The pronunciation blurred on a line said while laughing.
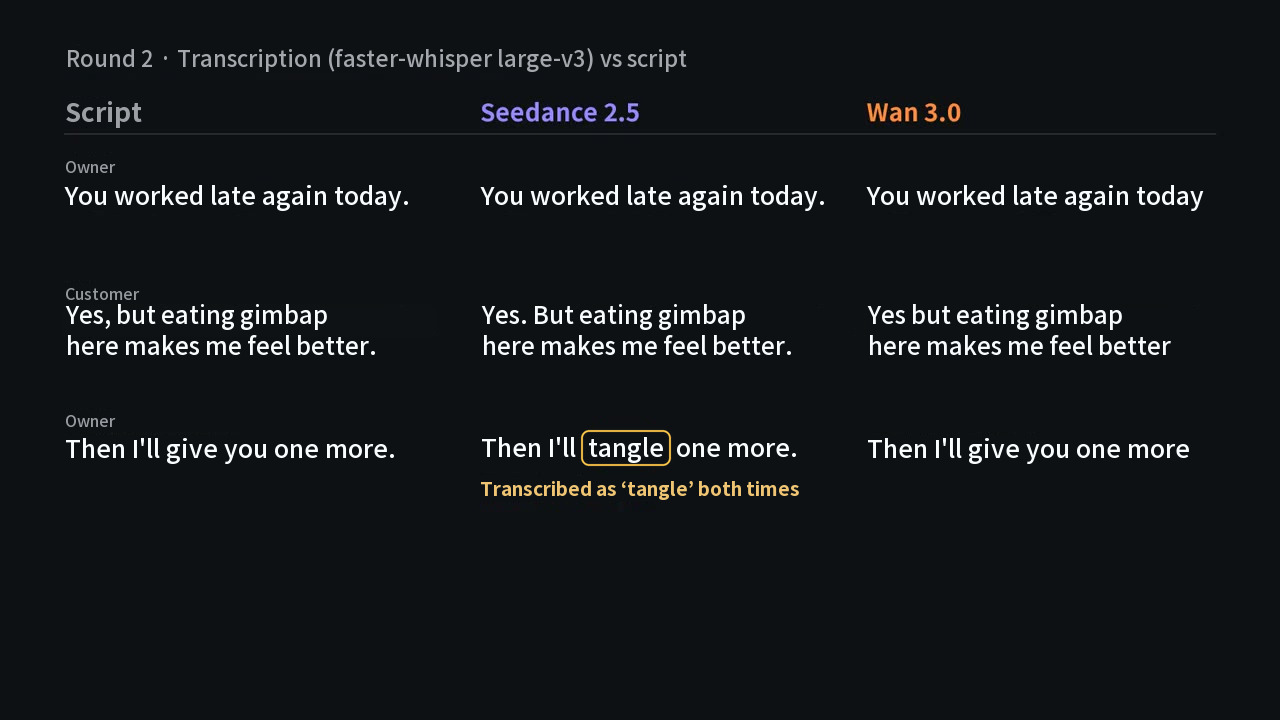
- Voice pitch was around 100Hz for the owner and around 180Hz for the customer in both, and there was no place where the speaker was swapped.
- Direction was closer to the script on Wan (an over-the-shoulder shot, a TV turned on in the back, a camera pulling back). Seedance drew a warm shop with gimbap stacked on shelves, but the camera pulling back was almost absent.
- Speech-to-text can get words with the same pronunciation wrong, and whether the intonation sounds Chinese cannot be measured by a machine, so the video urged listening for yourself.
The verdict: Seedance got prompt pass, form pass and sound hold; Wan passed all three.
Round 3: Korean text and a product
A 10-second clip with the white lettering "Doyoon Coffee" (in Korean) on a matte black tumbler, rotating half a turn on a turntable while the lid opens (4,400 vs 1,200 credits). We measured with EasyOCR whether the text was read every 3 frames, and counted it as correct when OCR read the syllable 윤 as the similar-looking 운.
Neither got the four characters wrong. Seedance was read in every frame (81/81) and Wan in 63 of 100 frames. On Wan the text turns sideways as the tumbler rotates, and from 7 seconds on it is a lid close-up, so the text is off screen.
But there is a catch in this number. The position of Seedance's text moved sideways by only 2 pixels over 10 seconds. The tumbler did not rotate, and the 100% was earned by skipping the instruction to turn half a turn.
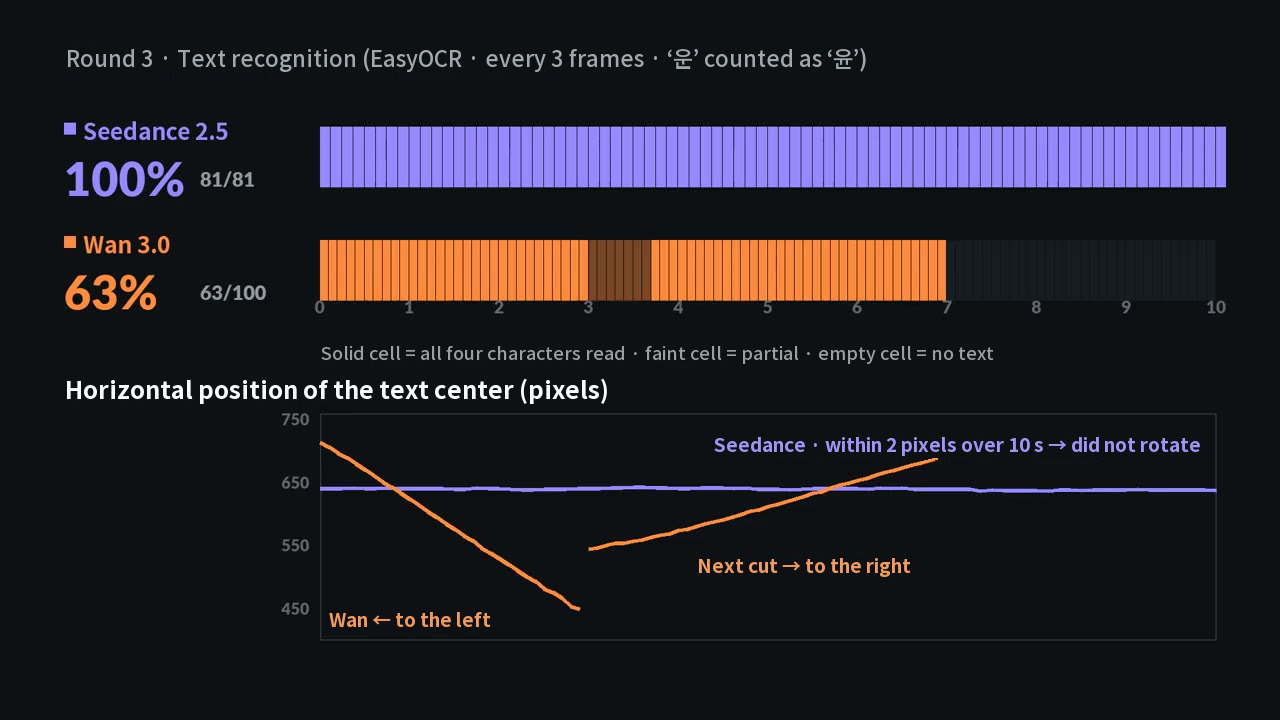
- The lid was interpreted differently. On Seedance the whole lid flew off. On Wan the drinking-opening cover opened but closed again within 0.2 seconds and turned translucent, and the tumbler that was turning left in the previous cut turned right in the next one. The opening sound matched the picture within two frames on both.
- Sound was richer on Seedance. Water drops, the lid and escaping steam were picked out separately, while Wan had only a short click over quiet reverb.
The verdict: Seedance got prompt hold (the tumbler did not turn), form pass and sound pass; Wan got prompt pass (rotation, cover, steam), form hold (the cover closed again) and sound pass.
Round 4: 2D animation
A 12-second clip of a schoolgirl in a red scarf at a bus stop with cherry blossoms in the air (5,280 vs 1,440 credits).
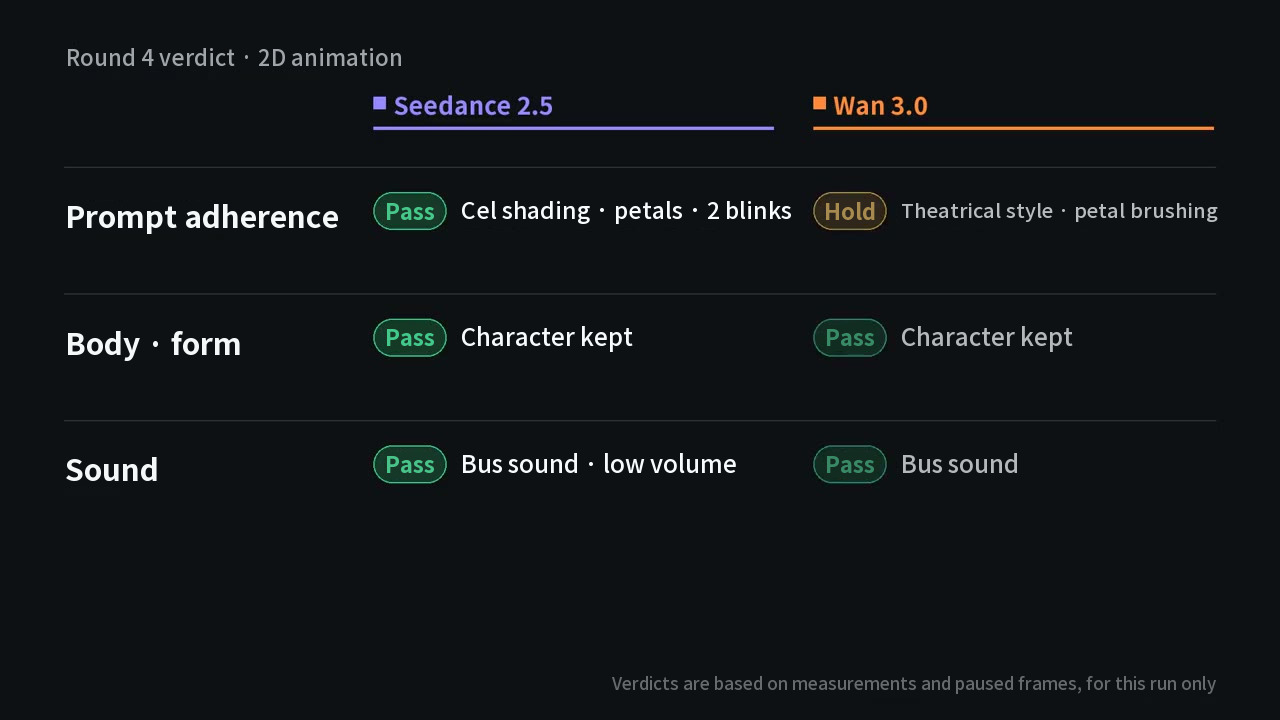
- Art style: Seedance used flat cel shading, close to the cel-animation feel the prompt asked for. Wan drew a theatrical-anime look with strong glow, smooth and gorgeous but not the feel requested.
- Numbers: The share of frames that keep the same drawing (higher means more limited animation) was Seedance 67% vs Wan 9% in the wide shot and 49% vs 0% in the mid shot. In the close-up it was 8% vs 10%. The screen notes this is measured from frame-to-frame differences, so it can come out low when many petals are flying.
- Detail: In the close-up, a petal landed on Seedance's nose and stayed to the end, while on Wan it brushed the nose and fell. When the bus arrives, told to lift her head and step forward, Wan turned her body and Seedance kept looking at her phone.
- Sound: Both rose as the bus arrived, and Seedance's overall volume was low.
Totals and the verdict by use
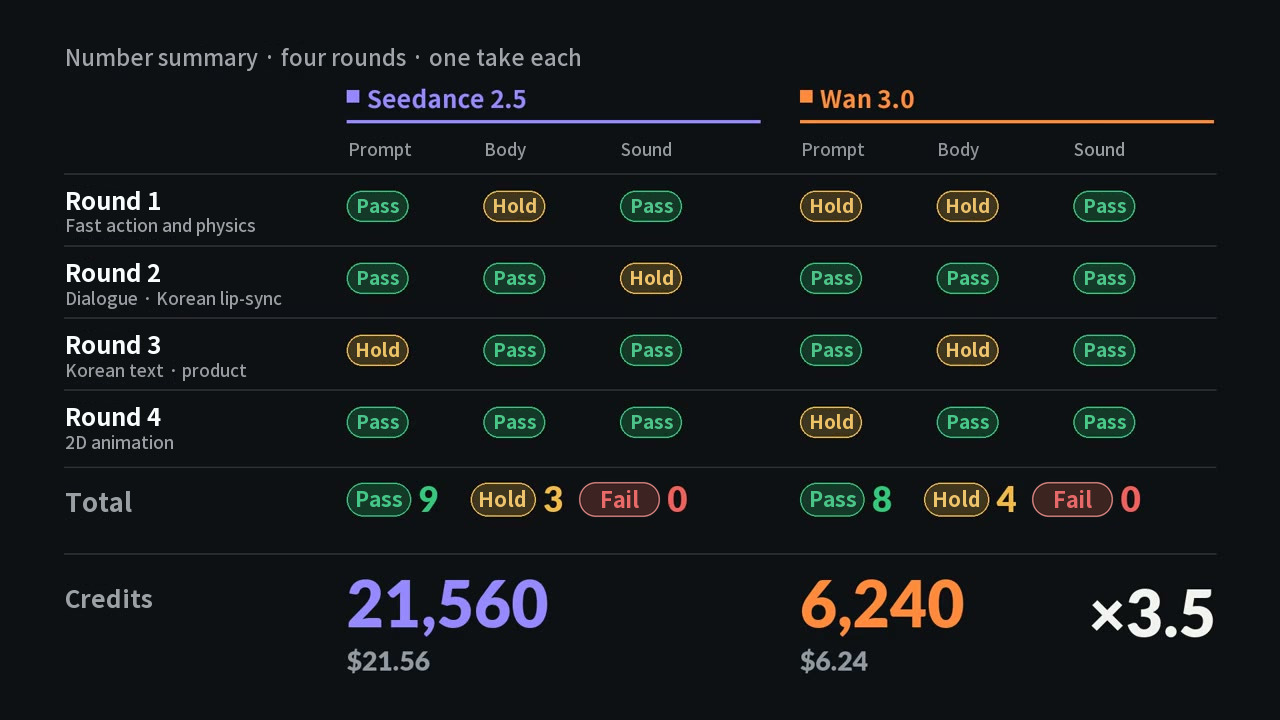
Converted at the 20-dollar plan's price, that is 21.56 dollars vs 6.24 dollars (as shown in the video).
| Use | The video's conclusion |
|---|---|
| Korean dialogue | Wan 3.0. All three lines matched the script in this run's transcription |
| Cel-animation feel | Seedance 2.5. Wan if you want a gorgeous theatrical look |
| Product shot | Seedance for text sharpness and sound; Wan for following turn-and-open instructions |
| Action | A draw. Both have flaws: Seedance in hands and color, Wan in body curves |
| Same credits | You can run Wan 3.7 times. More than triple the price for a one-pass difference |
Limits and what we could not check
- These are results from one take per round. Generating many times from the same prompt could differ, and the real unit price including re-rolls was not worked out in this video.
- A drift test, checking whether the picture melts from around 20 seconds in a 30-second one-take, was left out of this episode. The video announced a follow-up, but its description now says it was not made because the channel's direction changed.
- Speech-to-text can get same-sounding words wrong, and intonation cannot be measured by a machine, so the only way is to listen yourself.
- All clips used in the comparison were generated by generative AI (Seedance 2.5, Wan 3.0) on Magnific, and scenes showing a person's face are not used in this post.
- Prices, rankings and model specs are September 2026 values. Changes after the video are not reflected.