Qwen3.8 27B 4-bit on Mac mini M6 32GB: 49.7 Tokens/s JSON, 8.8 Korean
Posted Video released
Qwen3.8 27B 4-bit on a Mac mini M6 32GB: the fastest combo hits 49.7 tokens/s on JSON but only 8.8 on Korean, and the fastest file loses the most quality (vs UD-Q6_K).
On a Mac mini M6 32GB, the fastest Qwen3.8 27B 4-bit combination (the 13.1GB byteshape file plus a DFlash2 draft) reached 49.7 tokens/s on JSON conversion. The same combination wrote Korean at only 8.8 tokens/s. With nothing turned on, the default is 8.5 tokens/s, so Korean barely got faster. The figure near 50 tokens/s was a best case for output where the next words are obvious, like JSON or code, and the fastest file also had the largest quality loss.
Every value was measured on one Mac mini on 2026-10-11 with llama.cpp b11552 (Metal), and we did not rent a server. This article rewrites a 7 min 43 s video (published 2026-10-11), which is narrated in Korean.
What we measured
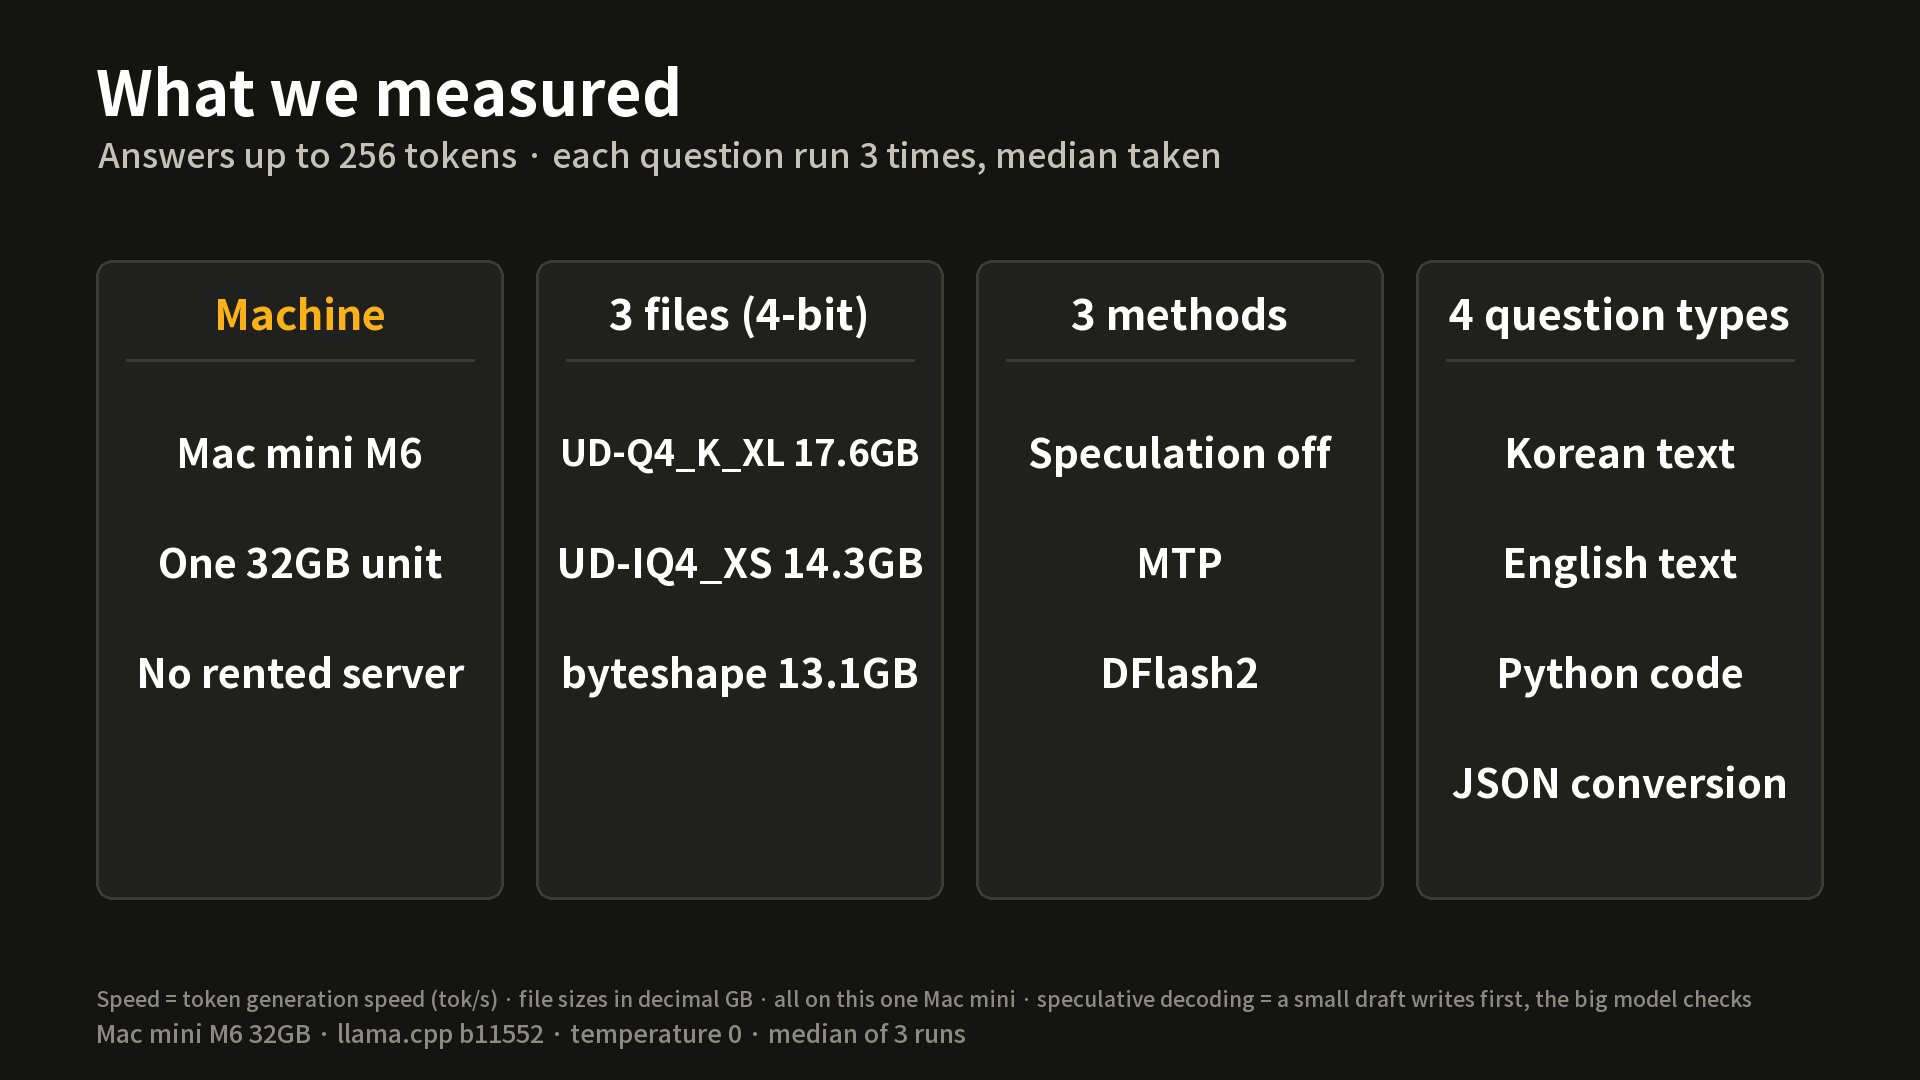
The 4-bit files are UD-Q4_K_XL at 17.6GB, UD-IQ4_XS at 14.3GB, and byteshape at 13.1GB. Speculative decoding means a small draft model writes several tokens ahead, and the big model checks them all at once and skips ahead by the number that were right. We compared MTP (a prediction part inside the model) and DFlash2 (a 1.1GB draft model, 7 tokens). The 4 question types are Korean · English · Python code · JSON, with answers up to 256 tokens, temperature 0, and the median of 3 runs. The speeds in the tables are rounded to one decimal place, while the multiples and ratios in the text are calculated from the unrounded measured values. So dividing the table values again can give a different last digit (for example, table values 10.8÷8.5=1.27, unrounded 10.834÷8.483=1.28).
The smaller the file, the faster
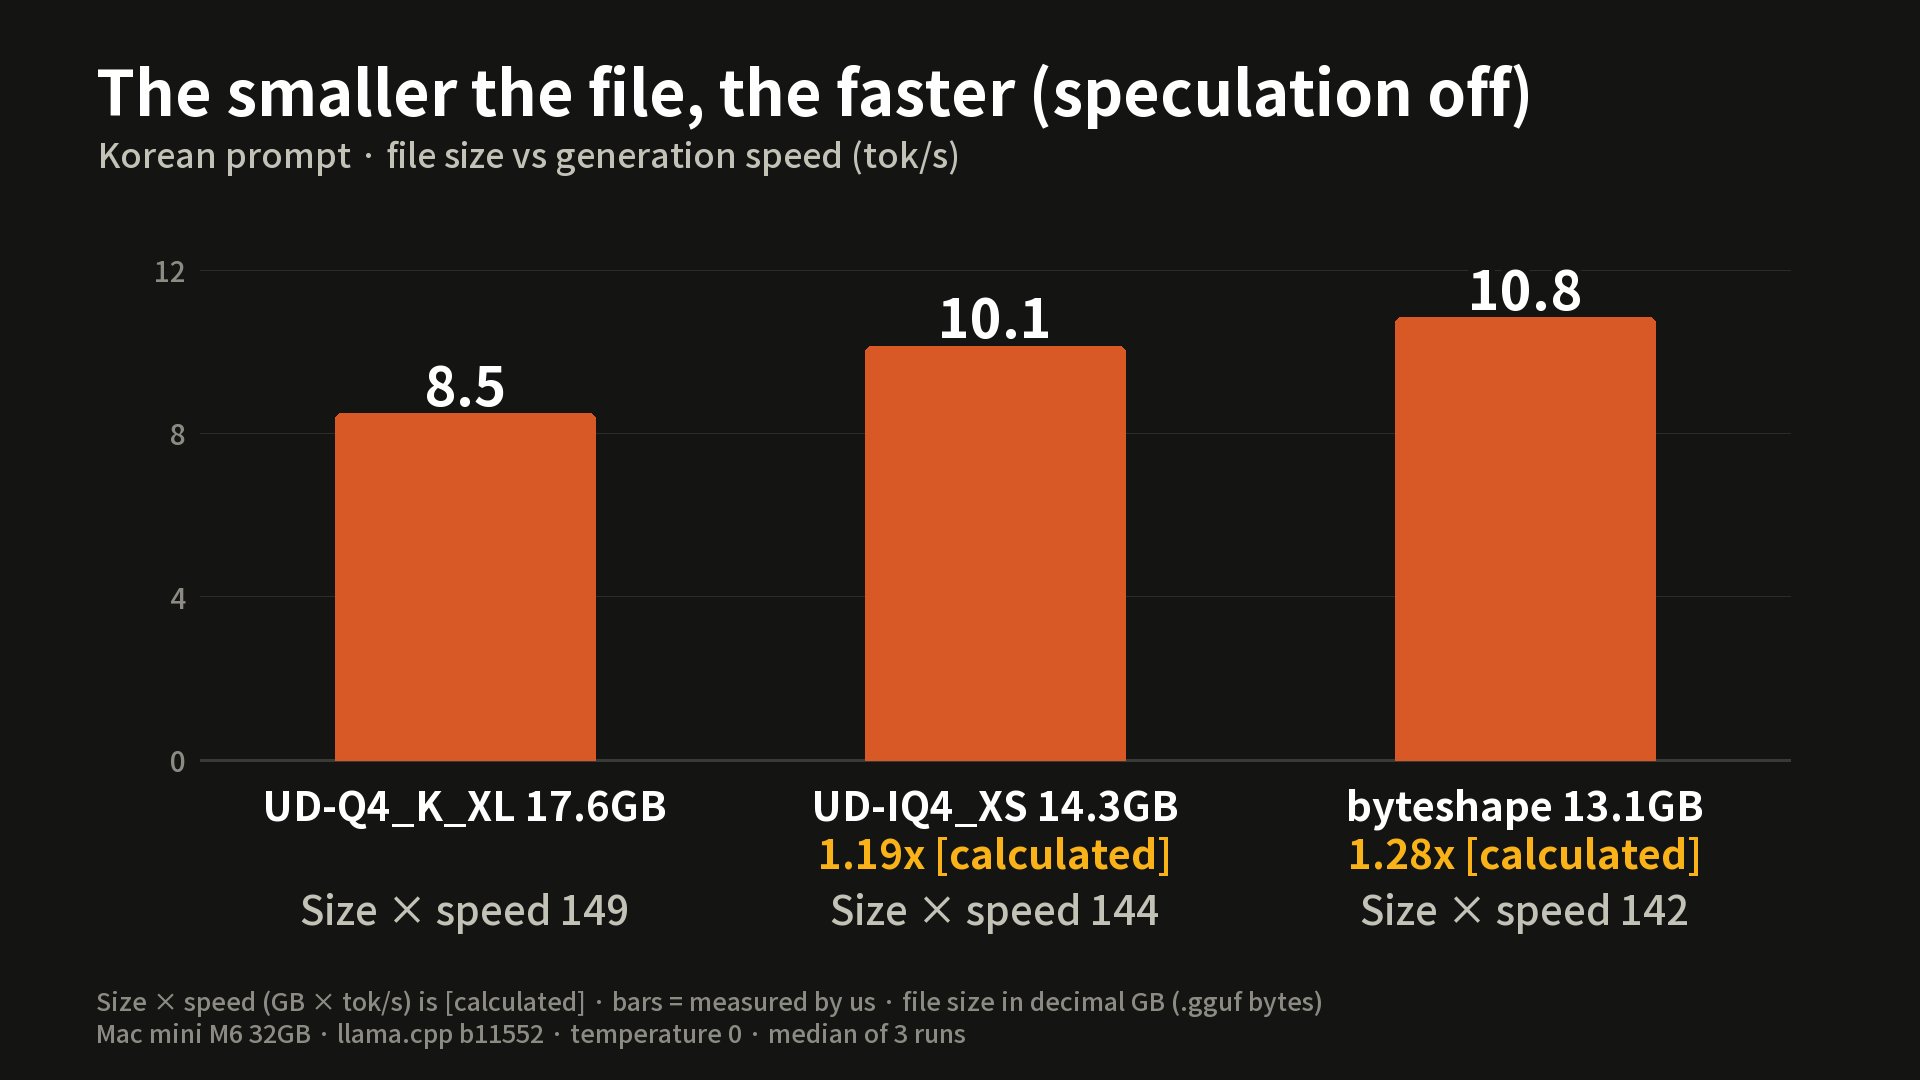
With speculation off and a Korean prompt, the 17.6GB file gets 8.5, the 14.3GB file 10.1, and the 13.1GB file 10.8 tokens/s. File size times speed is roughly constant (bandwidth is the limit), so shrinking the file alone gives 1.19x and 1.28x (calculated).
The draft has to be right to speed things up
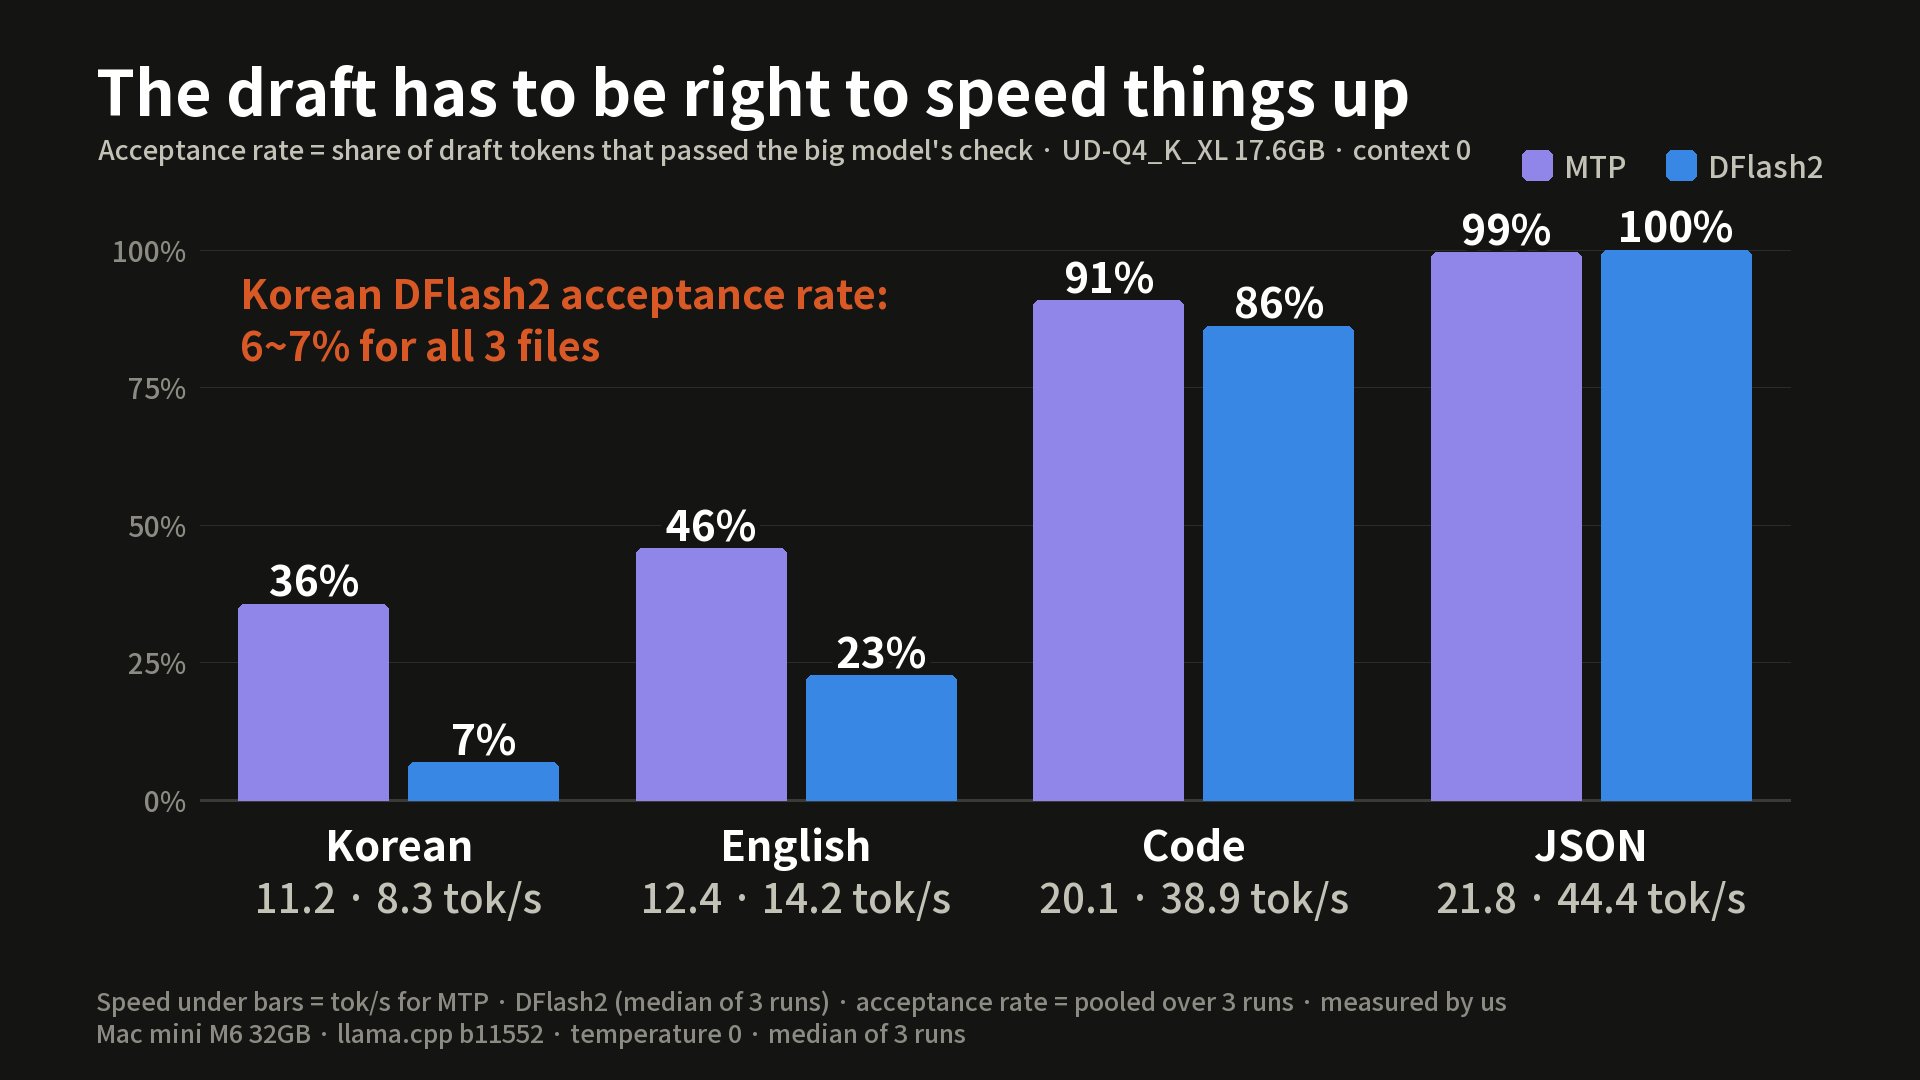
Turning on MTP for UD-Q4_K_XL gives Korean 11.2 · code 20.1 · JSON 21.8 tokens/s. Turning on DFlash2 gives Korean 8.3 · code 38.9 · JSON 44.4 tokens/s. The draft acceptance rate decides speed. For JSON it is 99% with MTP and 100% with DFlash2, but for Korean it was 36% with MTP and 7% with DFlash2.
The twist in the fastest combination
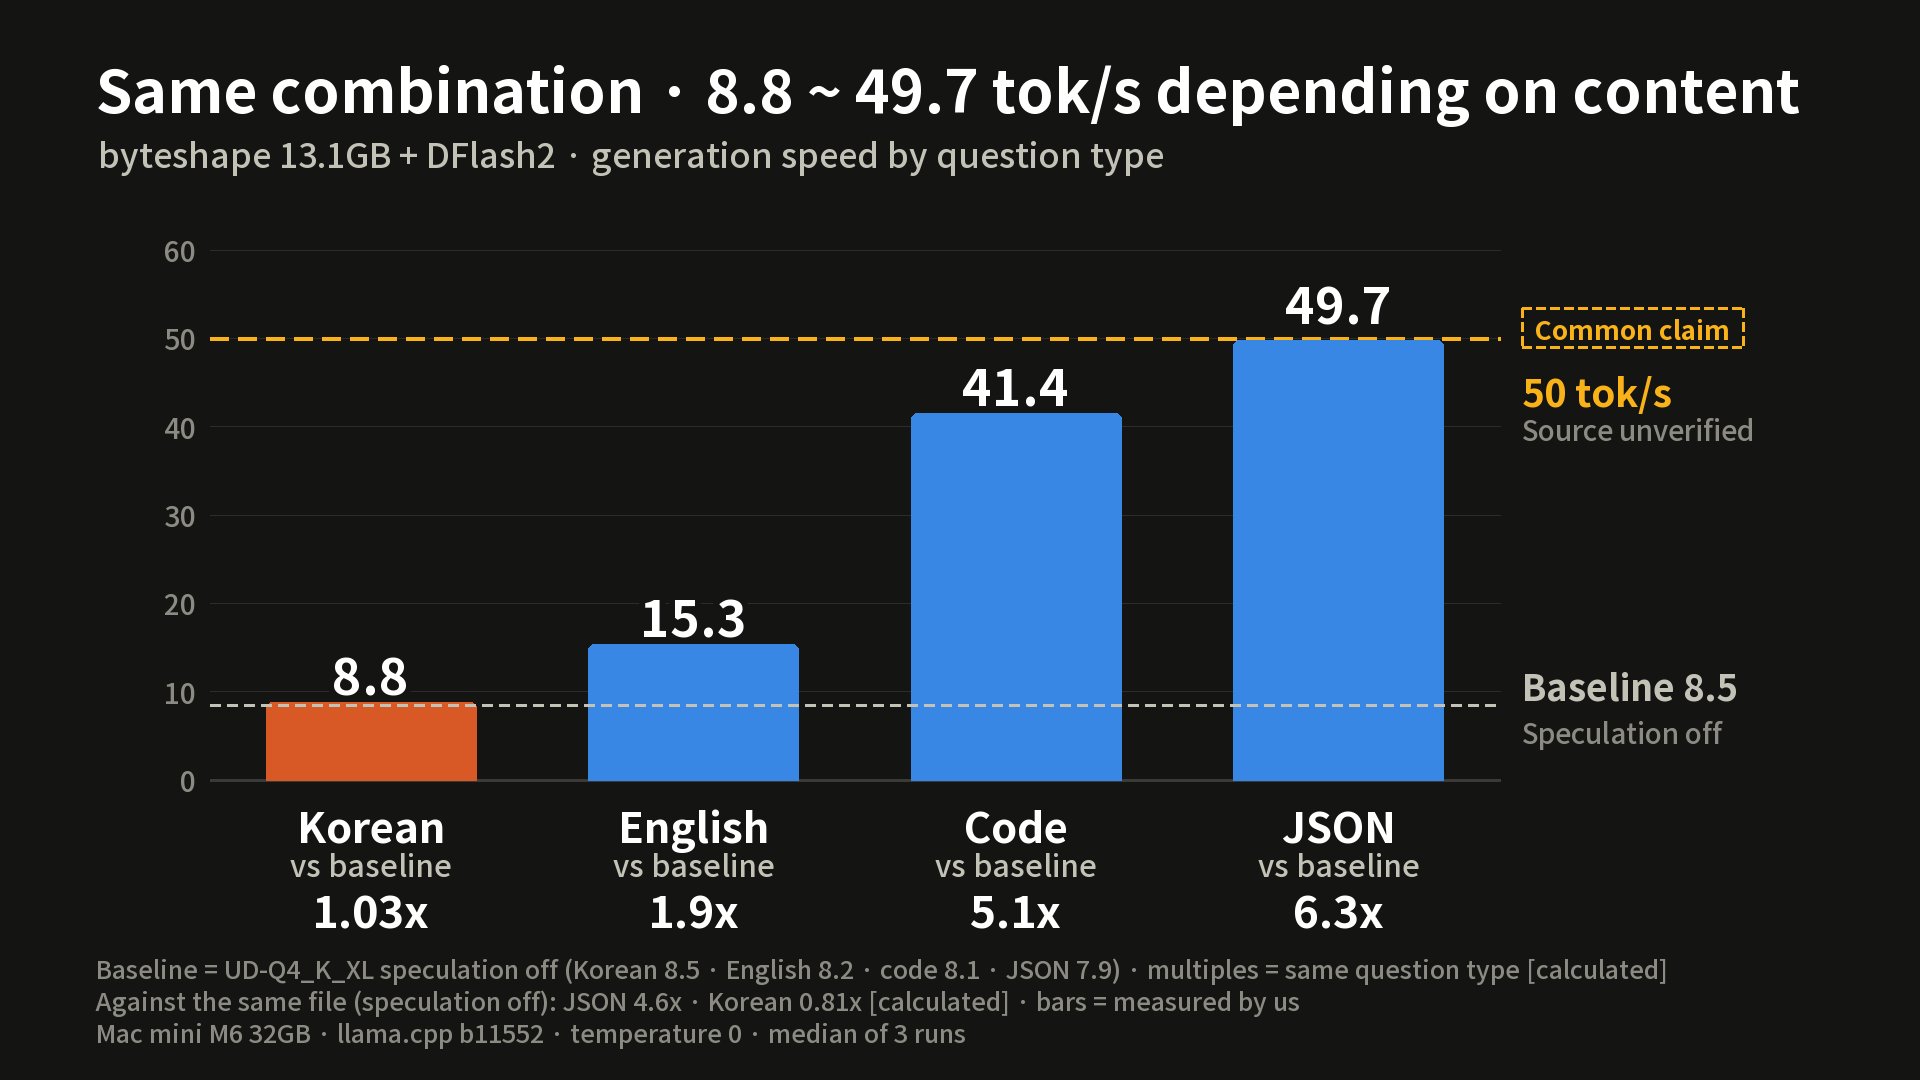
Combining byteshape with DFlash2 gives JSON 49.7 · code 41.4 · English 15.3 · Korean 8.8 tokens/s. Against the baseline (UD-Q4_K_XL, speculation off), that is JSON 6.3x · code 5.1x · Korean 1.03x (calculated). The smaller file's effect is mixed in, so on the same file the JSON gain is 4.6x (byteshape with speculation off gets 10.9 tokens/s on JSON, 49.7÷10.9; calculated). On the same file with speculation off, Korean was 10.8, so turning it on actually made it slower.
Speed by question type (tokens/s, measured by us)
| Configuration | Korean | English | Code | JSON |
|---|---|---|---|---|
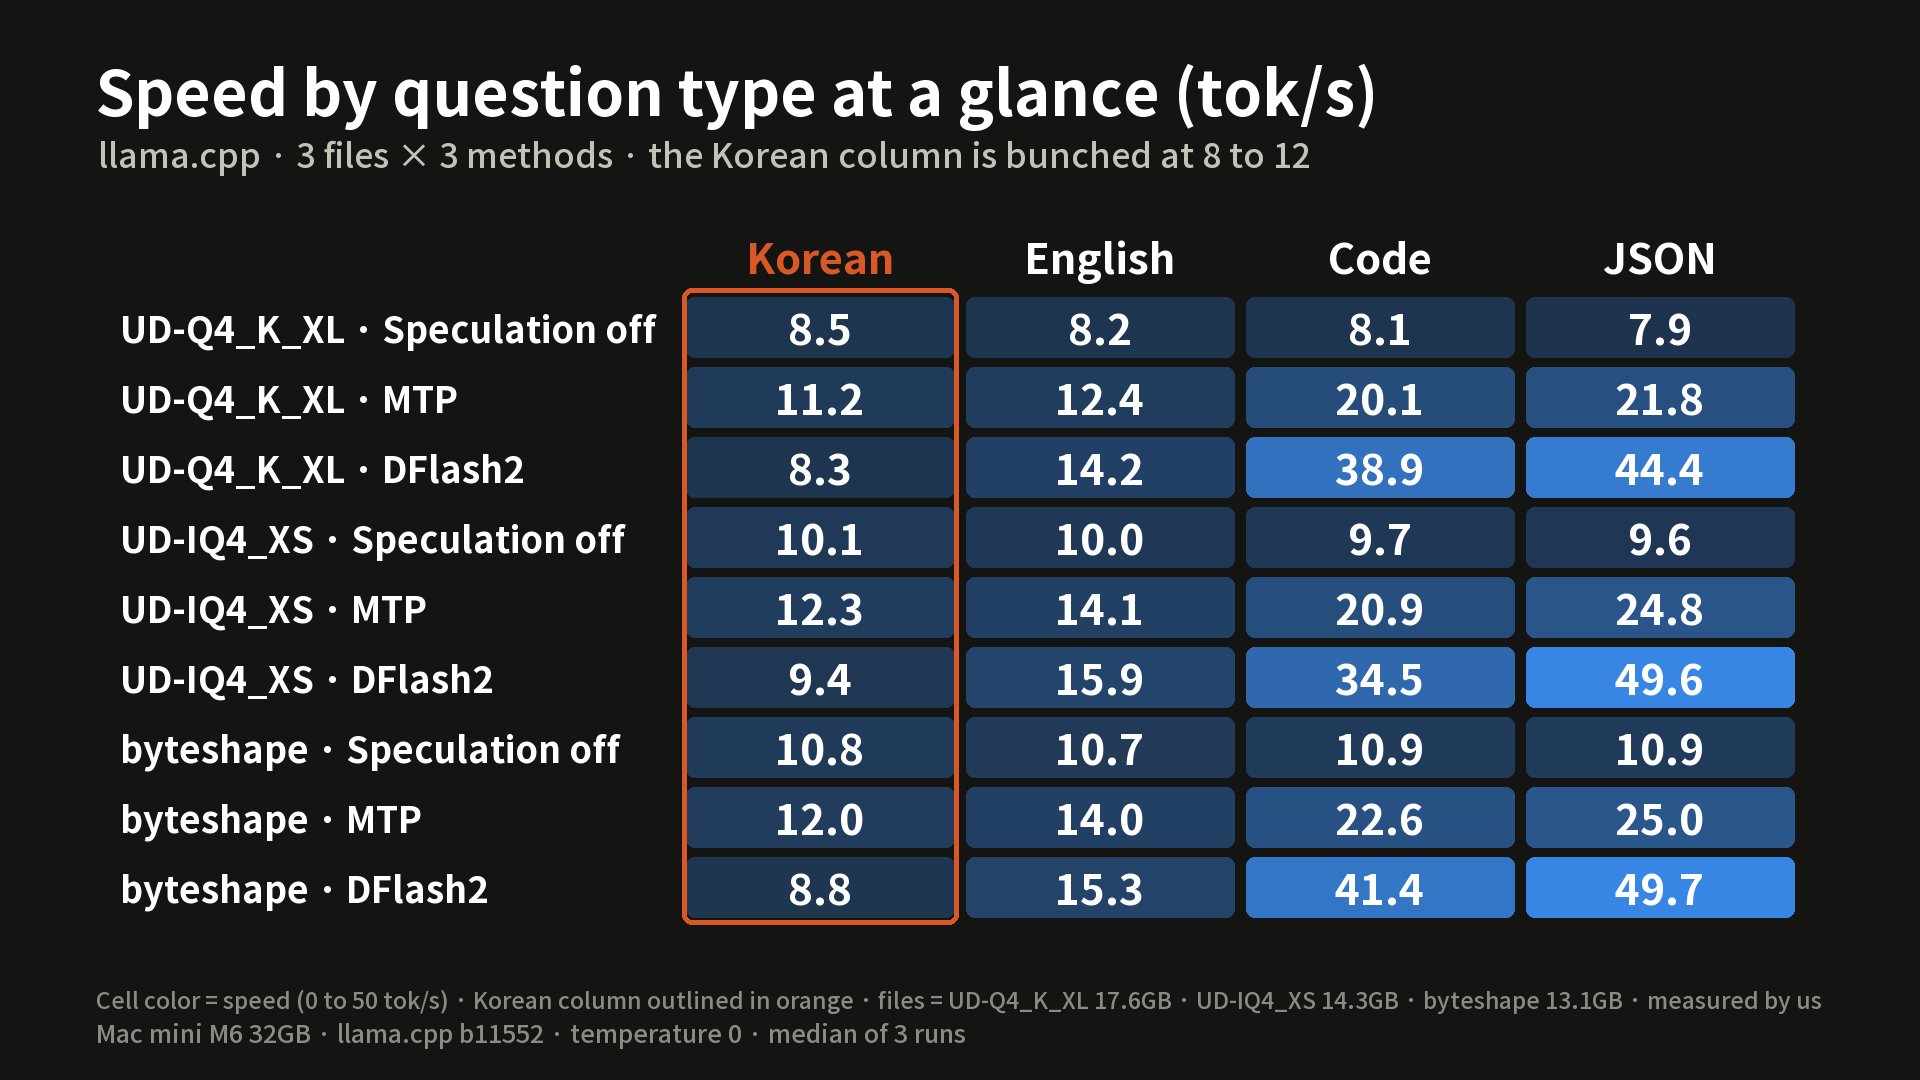
| UD-Q4_K_XL speculation off (baseline) | 8.5 | 8.2 | 8.1 | 7.9 |
| UD-Q4_K_XL + MTP | 11.2 | 12.4 | 20.1 | 21.8 |
| UD-Q4_K_XL + DFlash2 | 8.3 | 14.2 | 38.9 | 44.4 |
| UD-IQ4_XS + MTP | 12.3 | 14.1 | 20.9 | 24.8 |
| byteshape + DFlash2 | 8.8 | 15.3 | 41.4 | 49.7 |
The JSON and code columns spread from 8 to 50, while the Korean column is bunched at 8 to 12. The fastest llama.cpp configuration for Korean is UD-IQ4_XS + MTP at 12.3 tokens/s. JSON is an easy conversion, so the average in real use is lower.
Other runtimes and long context
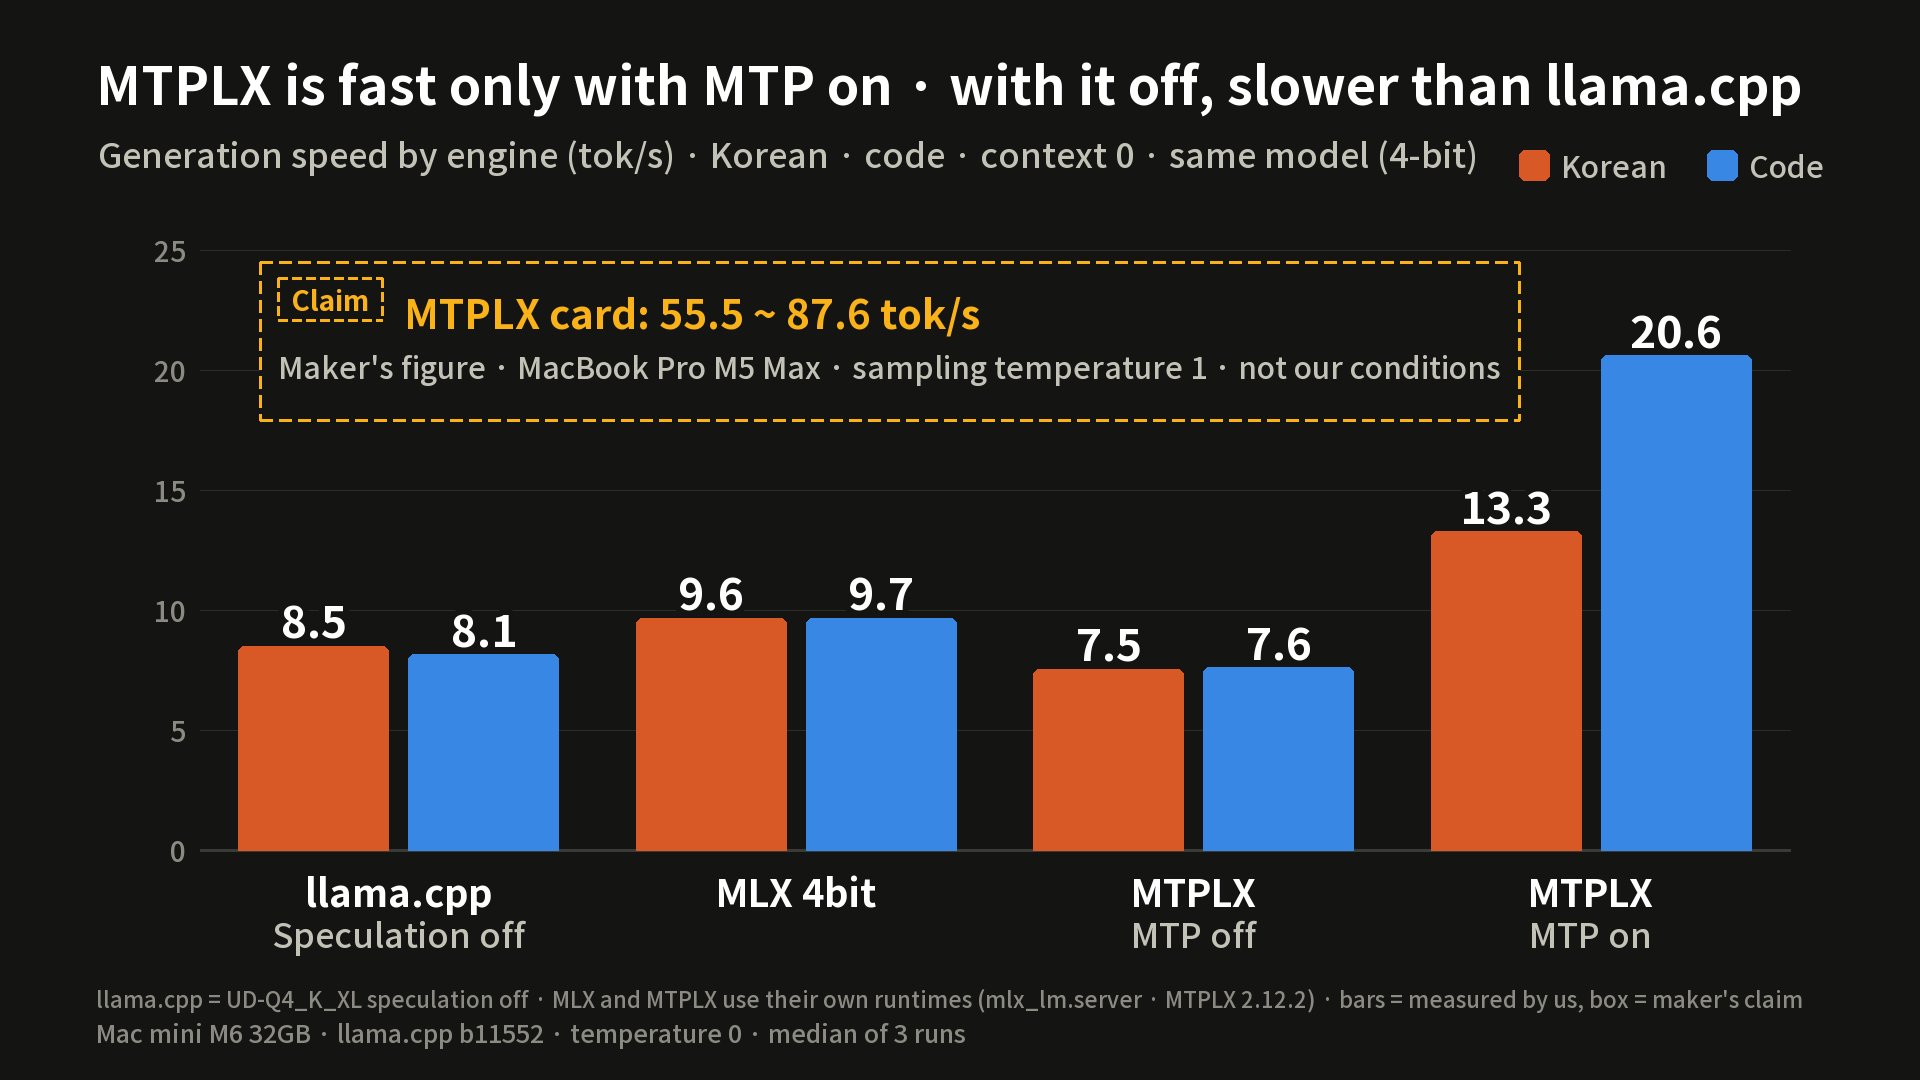
MLX 4-bit gets 9.6 tokens/s in Korean. The MTPLX pack is 7.5 with MTP off, slower than llama.cpp, and 13.3 for Korean and 20.6 for code with it on. At a 4K-token context, the default settings blocked the request for lack of memory. The 55.5 to 87.6 tokens/s on the MTPLX card is the maker's figure on an M5 Max, so it is not the same conditions.
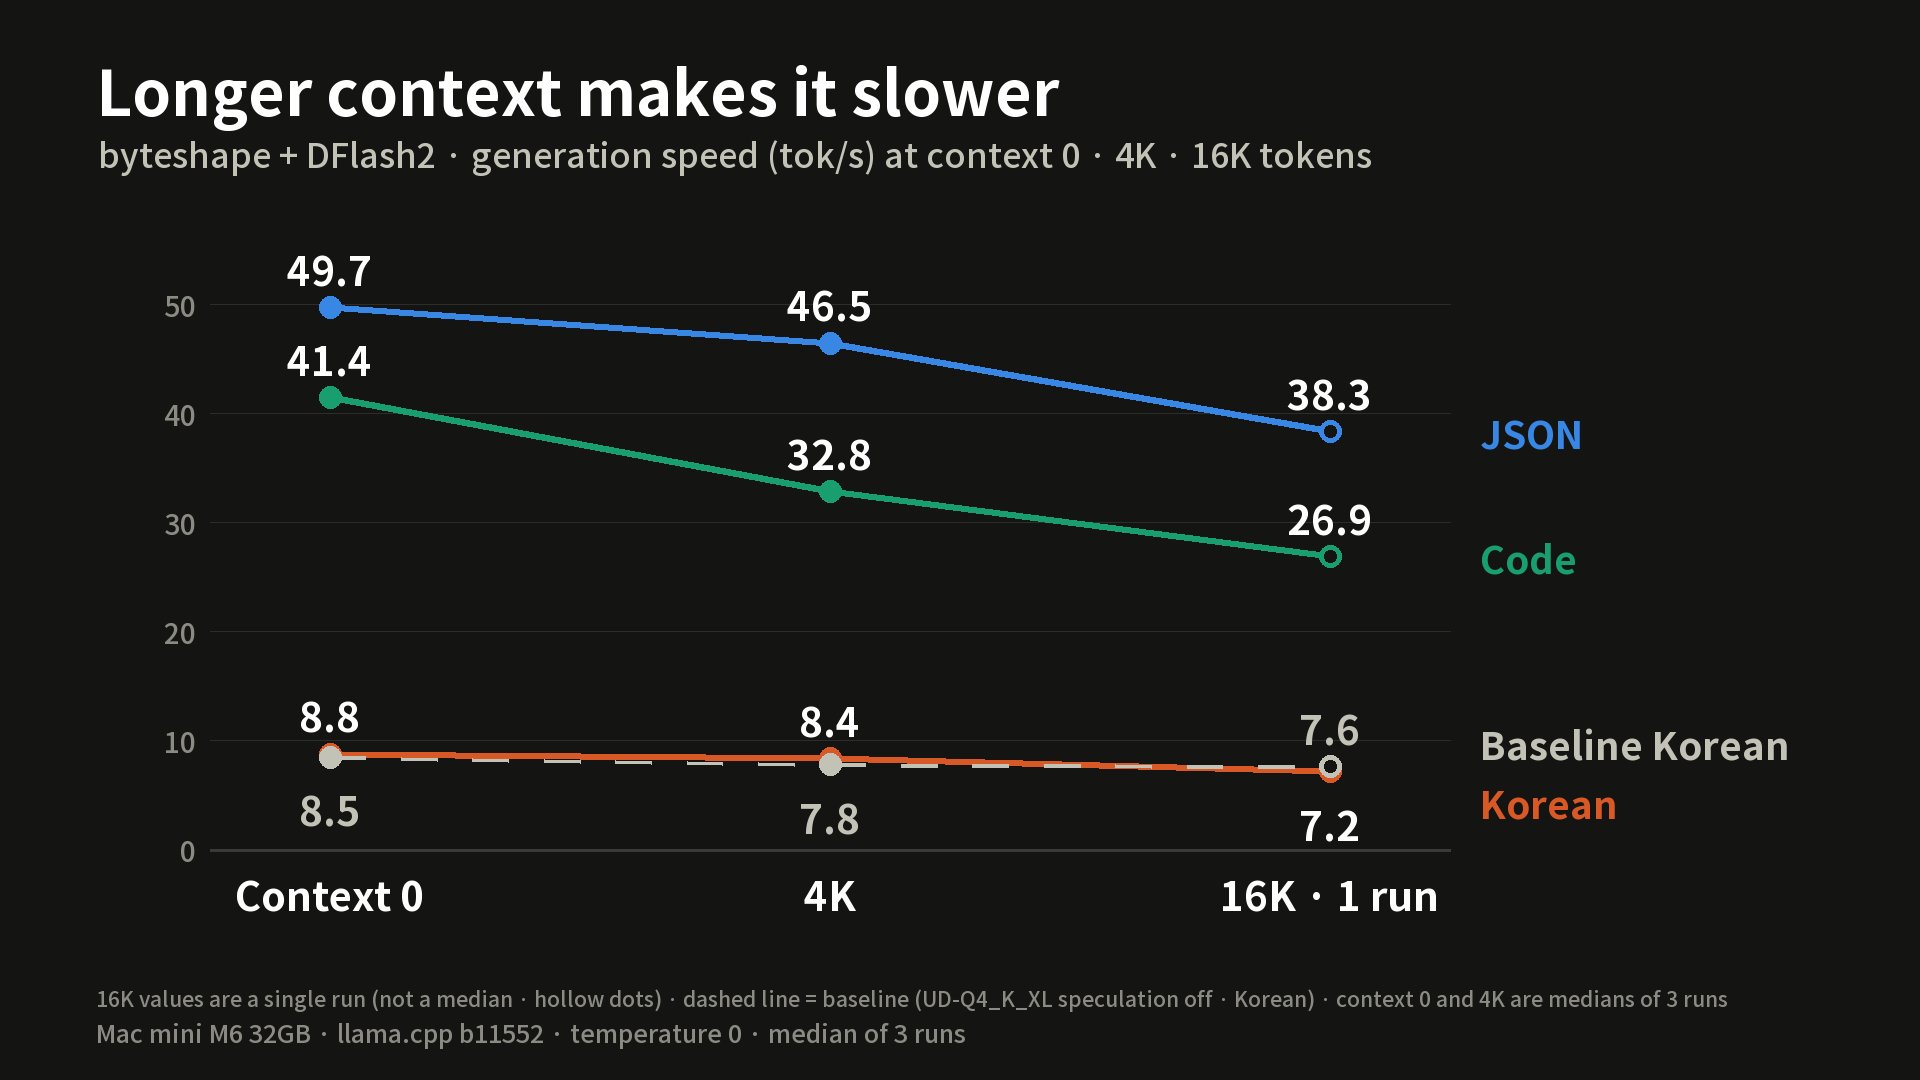
As context grows, byteshape + DFlash2 JSON goes 49.7 at context 0, 46.5 at 4K, and 38.3 tokens/s at 16K (the 16K figure is a single run). Korean goes 8.8, 8.4 and 7.2, which at 16K is lower than the baseline of 7.6.
Quality: the fastest file also has the biggest loss
We measured how differently each file predicts the next word compared with the 22GB 6-bit file (UD-Q6_K), using KL (lower means closer to the reference). The reference is not the original BF16, and we neither downloaded nor ran BF16.
| File | Korean KL | Korean match rate | English KL | English match rate |
|---|---|---|---|---|
| UD-Q4_K_XL 17.6GB | 0.0068 | 96.4% | 0.0236 | 95.0% |
| UD-IQ4_XS 14.3GB | 0.0226 | 92.9% | 0.0621 | 91.6% |
| byteshape 13.1GB | 0.0507 | 89.3% | 0.1146 | 88.4% |
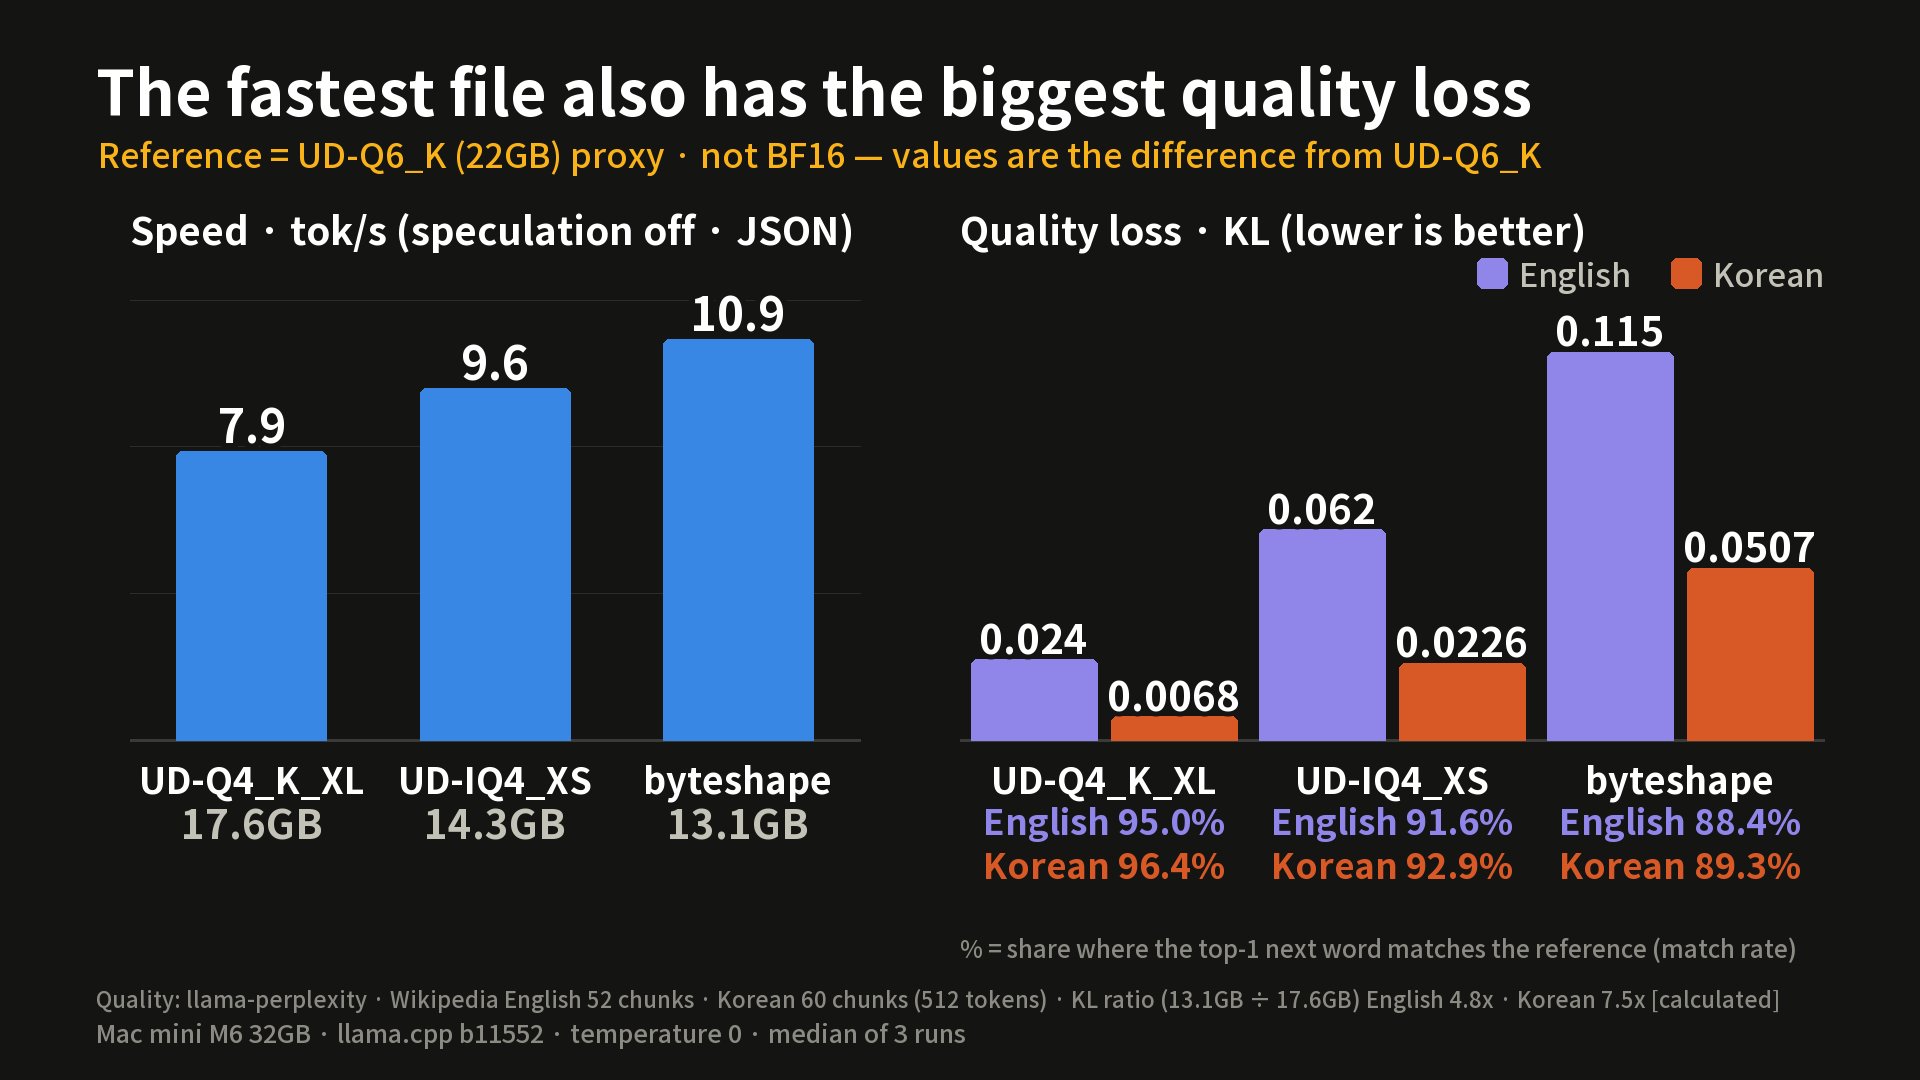
Compared with UD-Q4_K_XL, byteshape's KL is about 7.5x for Korean and about 4.8x for English (calculated; unrounded, 0.114565÷0.023645=4.845). The speed gain, between files both using DFlash2, was 12% for JSON and 6.6% for code (calculated; unrounded, 41.45÷38.88. With the table values 41.4÷38.9 it is 6.4%). The maker says byteshape scores highest on its own task scores (measured on an RTX PRO 6000), but what was measured differs, so they cannot be compared directly, and this test cannot say that a smaller file is also better in quality. The sample is 120,000 characters of English and 70,000 characters of Korean from Wikipedia.
Numbers left out of the speed table, and how to choose
With the ngram method, repeating the same Korean question shows 108 to 111 tokens/s, but it looks like a replay of the earlier answer. The first request ran at 8.4 tokens/s, and a freshly restarted server ran at 8.1 to 8.6 tokens/s, so we did not use it as performance.
- Korean writing and conversation: UD-Q4_K_XL + MTP (11.2 tokens/s, smallest quality loss).
- Korean, faster: UD-IQ4_XS + MTP (12.3 tokens/s, Korean KL up more than 3x).
- Code and JSON as the main use: UD-Q4_K_XL + DFlash2 (38.9 to 44.4 tokens/s). We did not measure code and JSON quality separately.
What we did not measure, and a follow-up note
We did not measure quality against BF16, a 40-question accuracy test, acceptance rates with sampling other than temperature 0, fan and temperature, or Splash (official minimum memory 36GB). All values come from this one Mac in one session, and a difference of a few percent may be error.
Follow-up note: in the channel's Strata video of 2026-10-13, we remeasured Korean on the same UD-IQ4_XS MTP file and got 14.1 tokens/s (acceptance rate 45.3%), which differs from this article's 12.3 (acceptance rate 33%). Apart from different question text and calling method, we could not identify a cause, and we do not mix the two values in one table.
Sources and reference date. Measured 2026-10-11. ByteShape blog (viewed 2026-10-11, cited only), MTPLX model card.
This article is based on a video narrated with an AI voice, and AI assisted the writing. It is for information only and is not a purchase recommendation.