DGX Spark Tested: 128GB Boxes vs Mac mini M6 (as of Sept 2026)
Posted Video released
We rented a DGX Spark and ran the same models as a Mac mini M6 32GB. One user: Mac mini (64 vs 40 tokens/s). 16 users: DGX Spark (319 vs 166). As of 2026-09.
We rented a DGX Spark in the cloud and measured it ourselves. For a single user, the Mac mini M6 32GB was faster (the same 35B-A3B 4-bit model, 64 vs 40 tokens/s). For several simultaneous users, the DGX Spark had the higher total (319 vs 166 tokens/s at 16 concurrent users). The four 128GB boxes, where the CPU and GPU share the memory, split by "one user or many, whether you need CUDA, and whether price comes first."
Reference date notice. Prices and product information in this article are as of the video's publication date (2026-09-28), with prices viewed on 2026-09-27. Prices and product configurations may have changed since. The RTX Spark, which was unreleased at the time of the video, has since had launch news (see the channel's 2026-10-20 video), but this article does not reflect it. Check the latest prices separately before you buy. This article rewrites the content of a 5 min 30 s video, which is narrated in Korean.
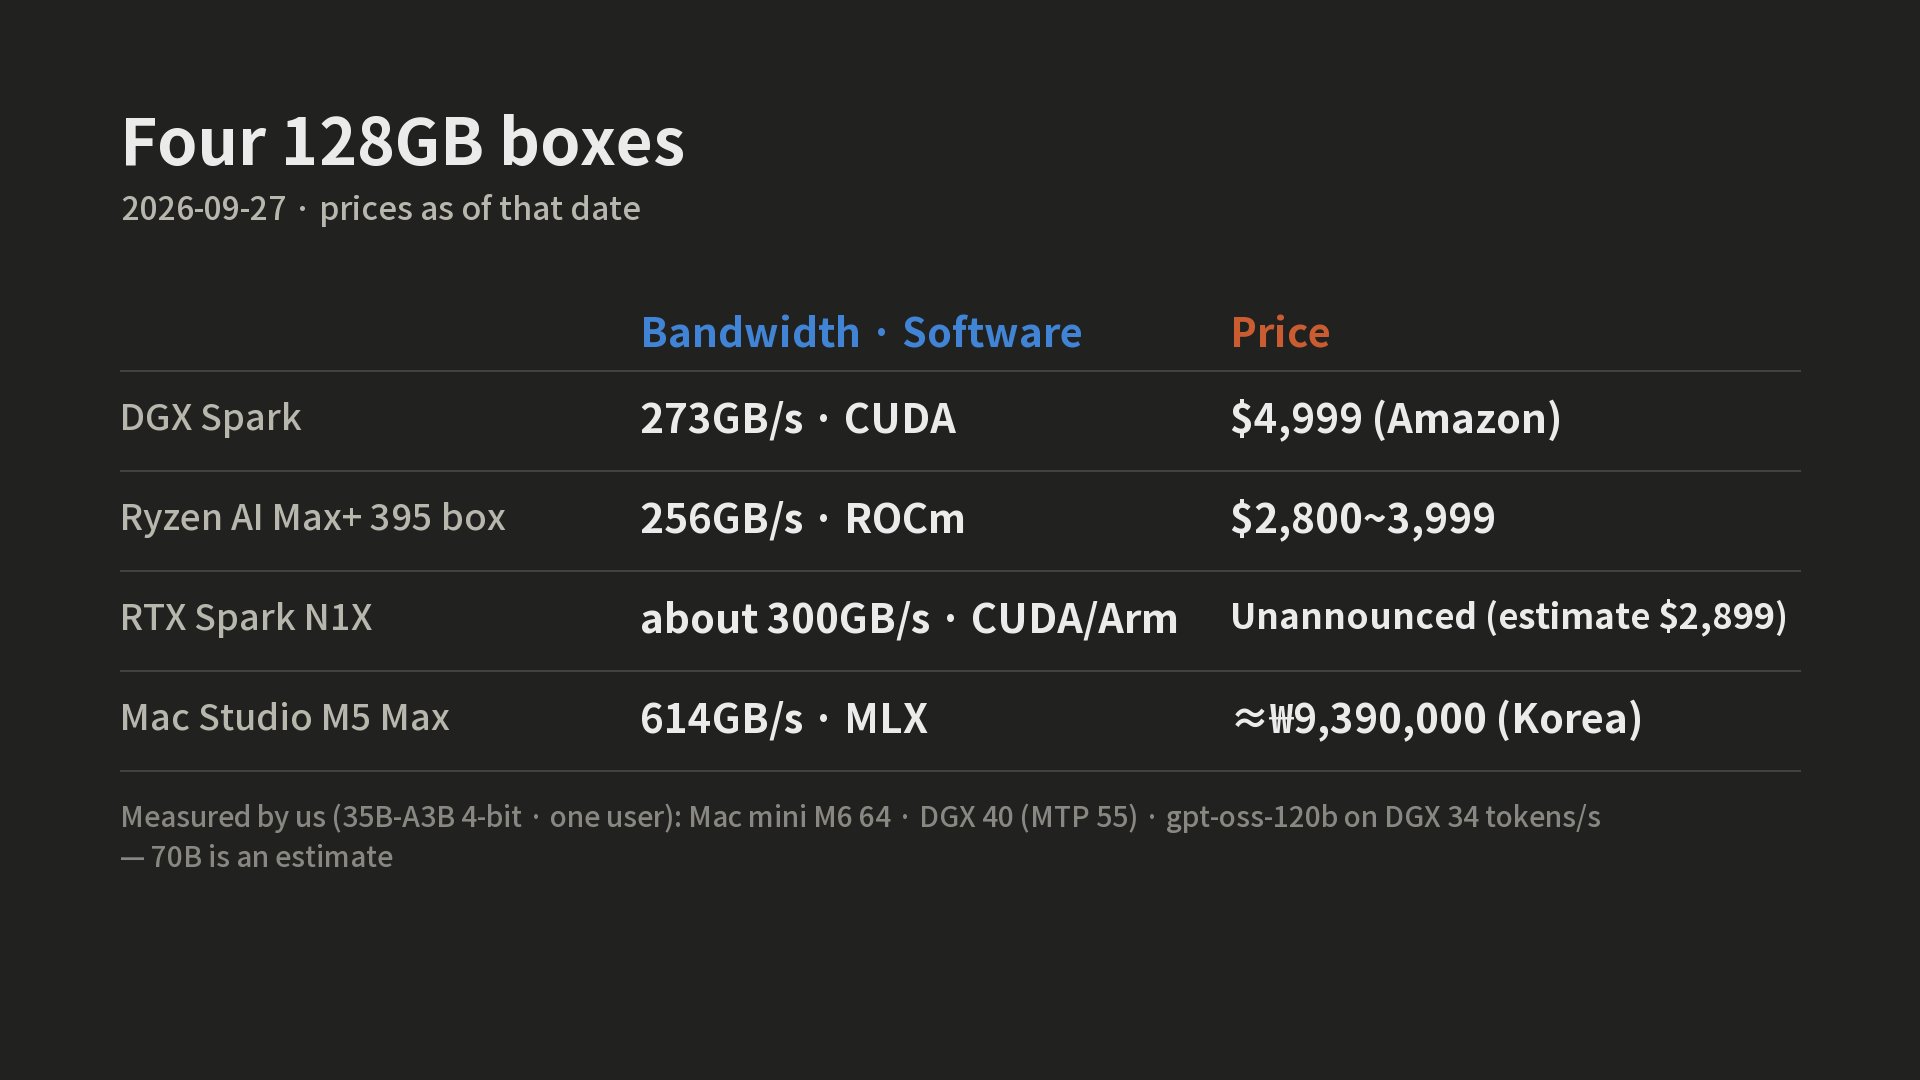
The four 128GB boxes in one table (as of 2026-09-27)
| Box | Memory bandwidth | Software | Price (as of the video's publication date) |
|---|---|---|---|
| NVIDIA DGX Spark | 273GB/s | CUDA | $4,999 (Amazon) |
| Ryzen AI Max+ 395 box | 256GB/s | ROCm | $2,800 to 3,999 |
| RTX Spark N1X | About 300GB/s | CUDA · Arm | Unannounced (Morgan Stanley estimate $2,899) |
| Mac Studio M5 Max 128GB | 614GB/s | MLX | About KRW 9,390,000 in Korea (as listed in the video) |
Bandwidth is the manufacturer's official figure (the announced spec for the RTX Spark), and prices are the values written in the video. Of these, the only one we measured ourselves is the DGX Spark. The other three are specs, estimates and citations.
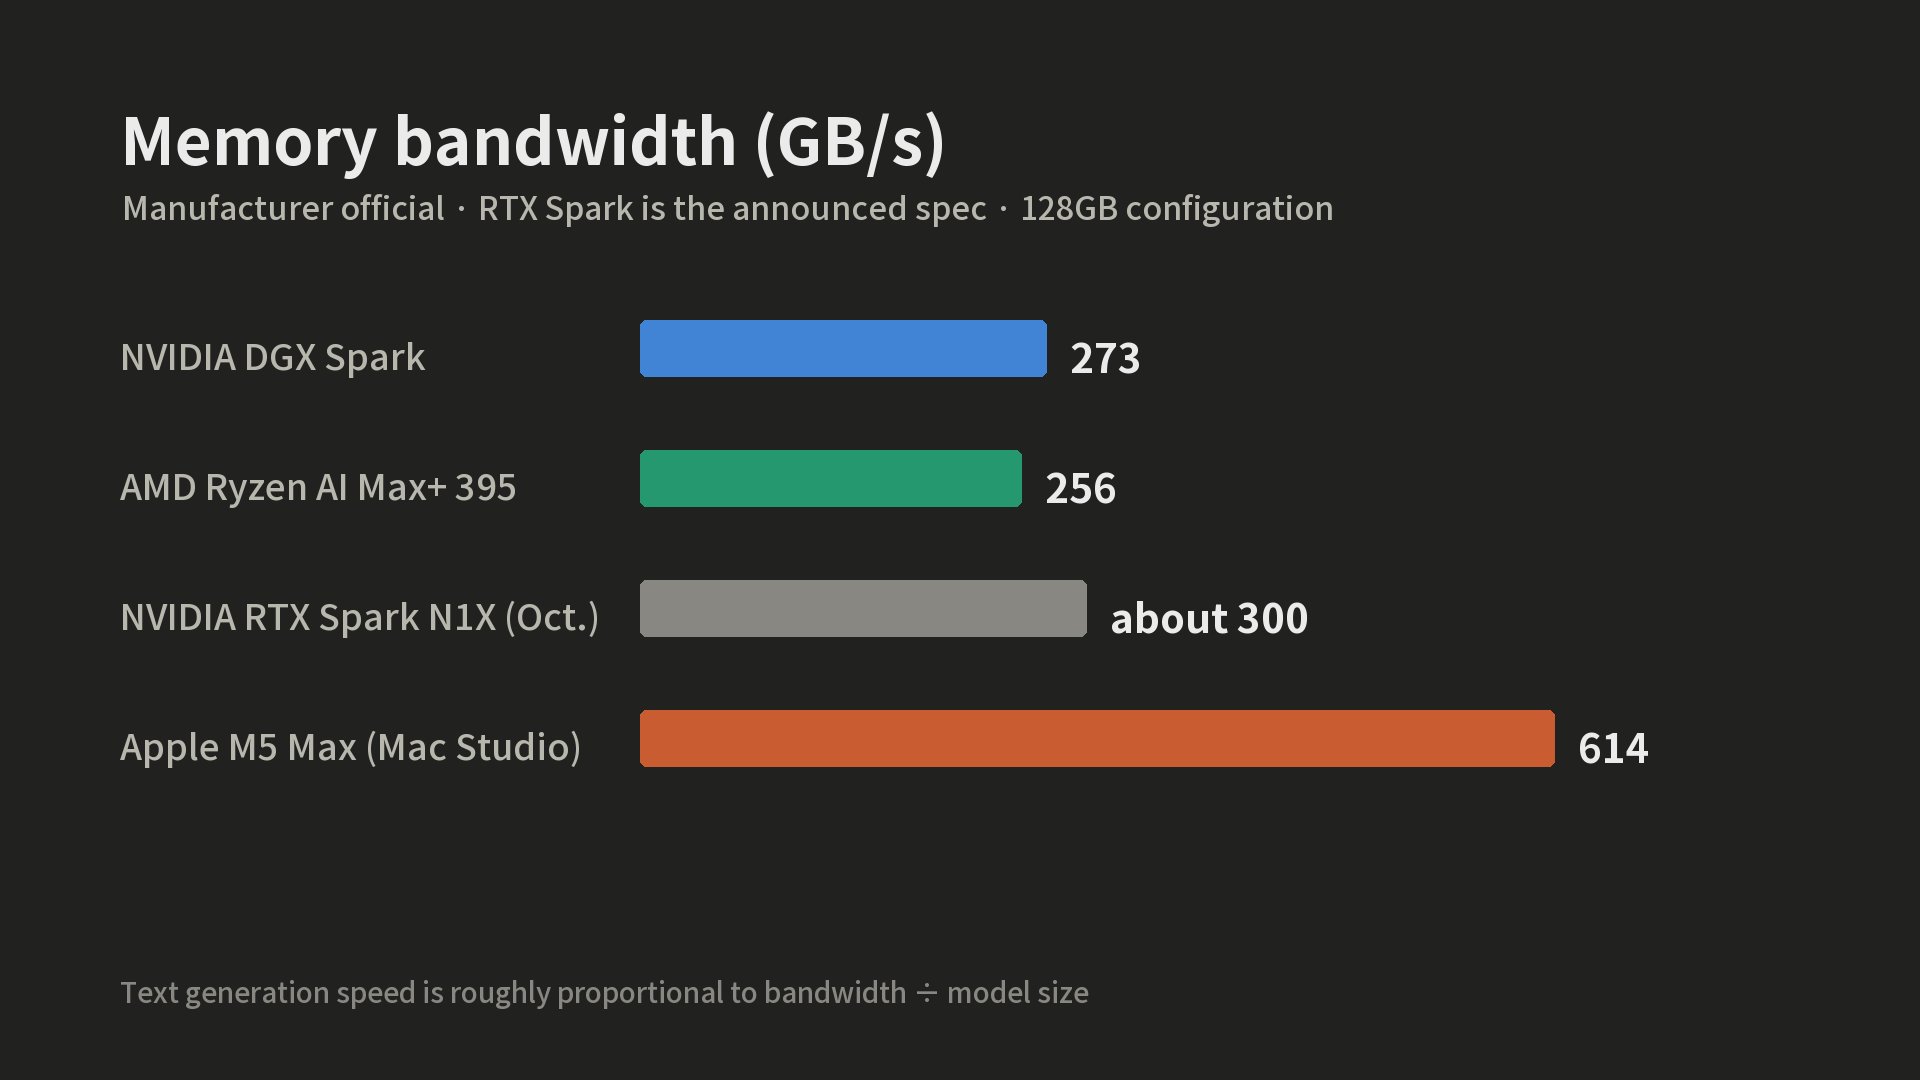
Estimate text generation speed from bandwidth first
Every time a token is generated, the whole model is read from memory, so speed is roughly proportional to "bandwidth ÷ model size." The Mac Studio M5 Max, at 614, is about 2.2x the DGX Spark's 273 (calculated).
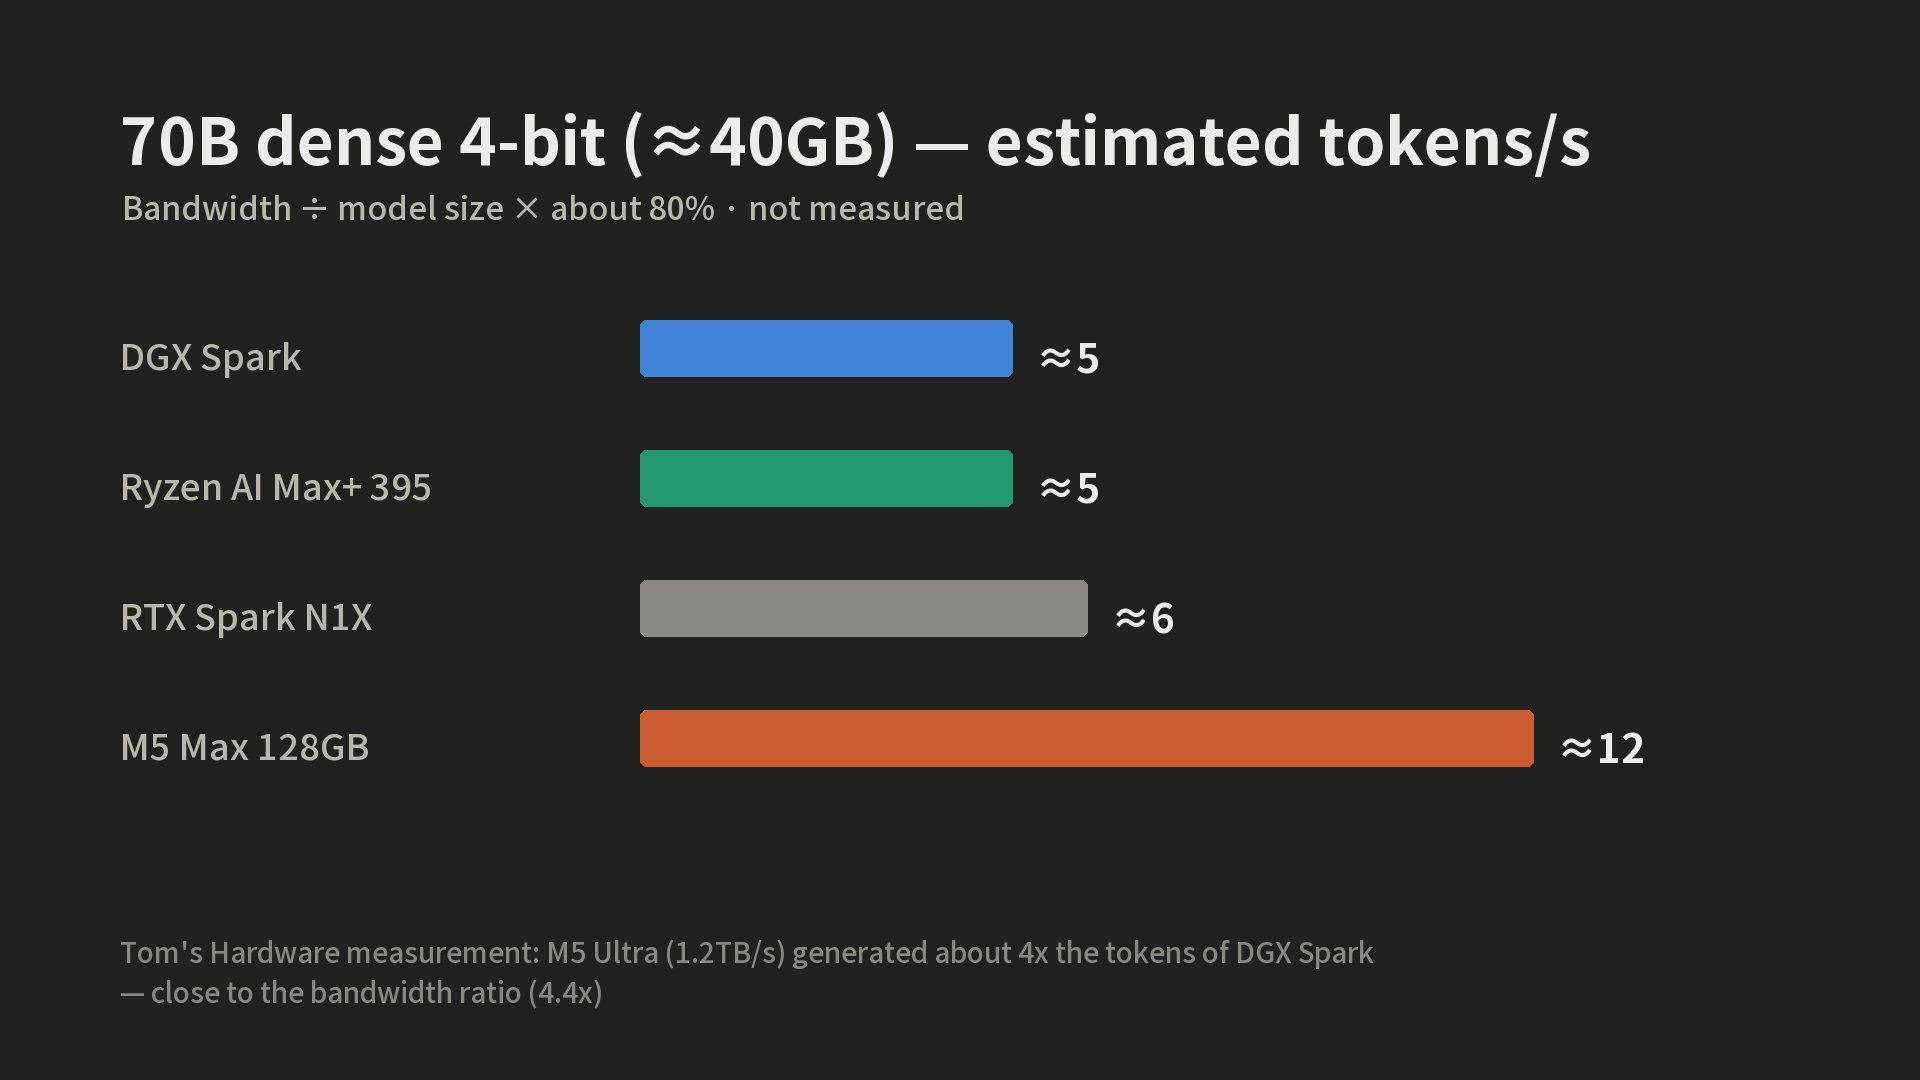
Applying "bandwidth ÷ size × about 80%" to a 40GB, 70B dense 4-bit model gives about 5 tokens/s on the DGX Spark and AMD, about 6 on the RTX Spark, and about 12 on the M5 Max (estimate). We could not measure the 70B ourselves because it failed twice on the rented DGX Spark (a host reboot, and the server exiting without a log). In Tom's Hardware's measurements, the M5 Ultra (1.2TB/s) generated about 4x the tokens of the DGX Spark, close to the bandwidth ratio of 4.4x (cited, secondary).
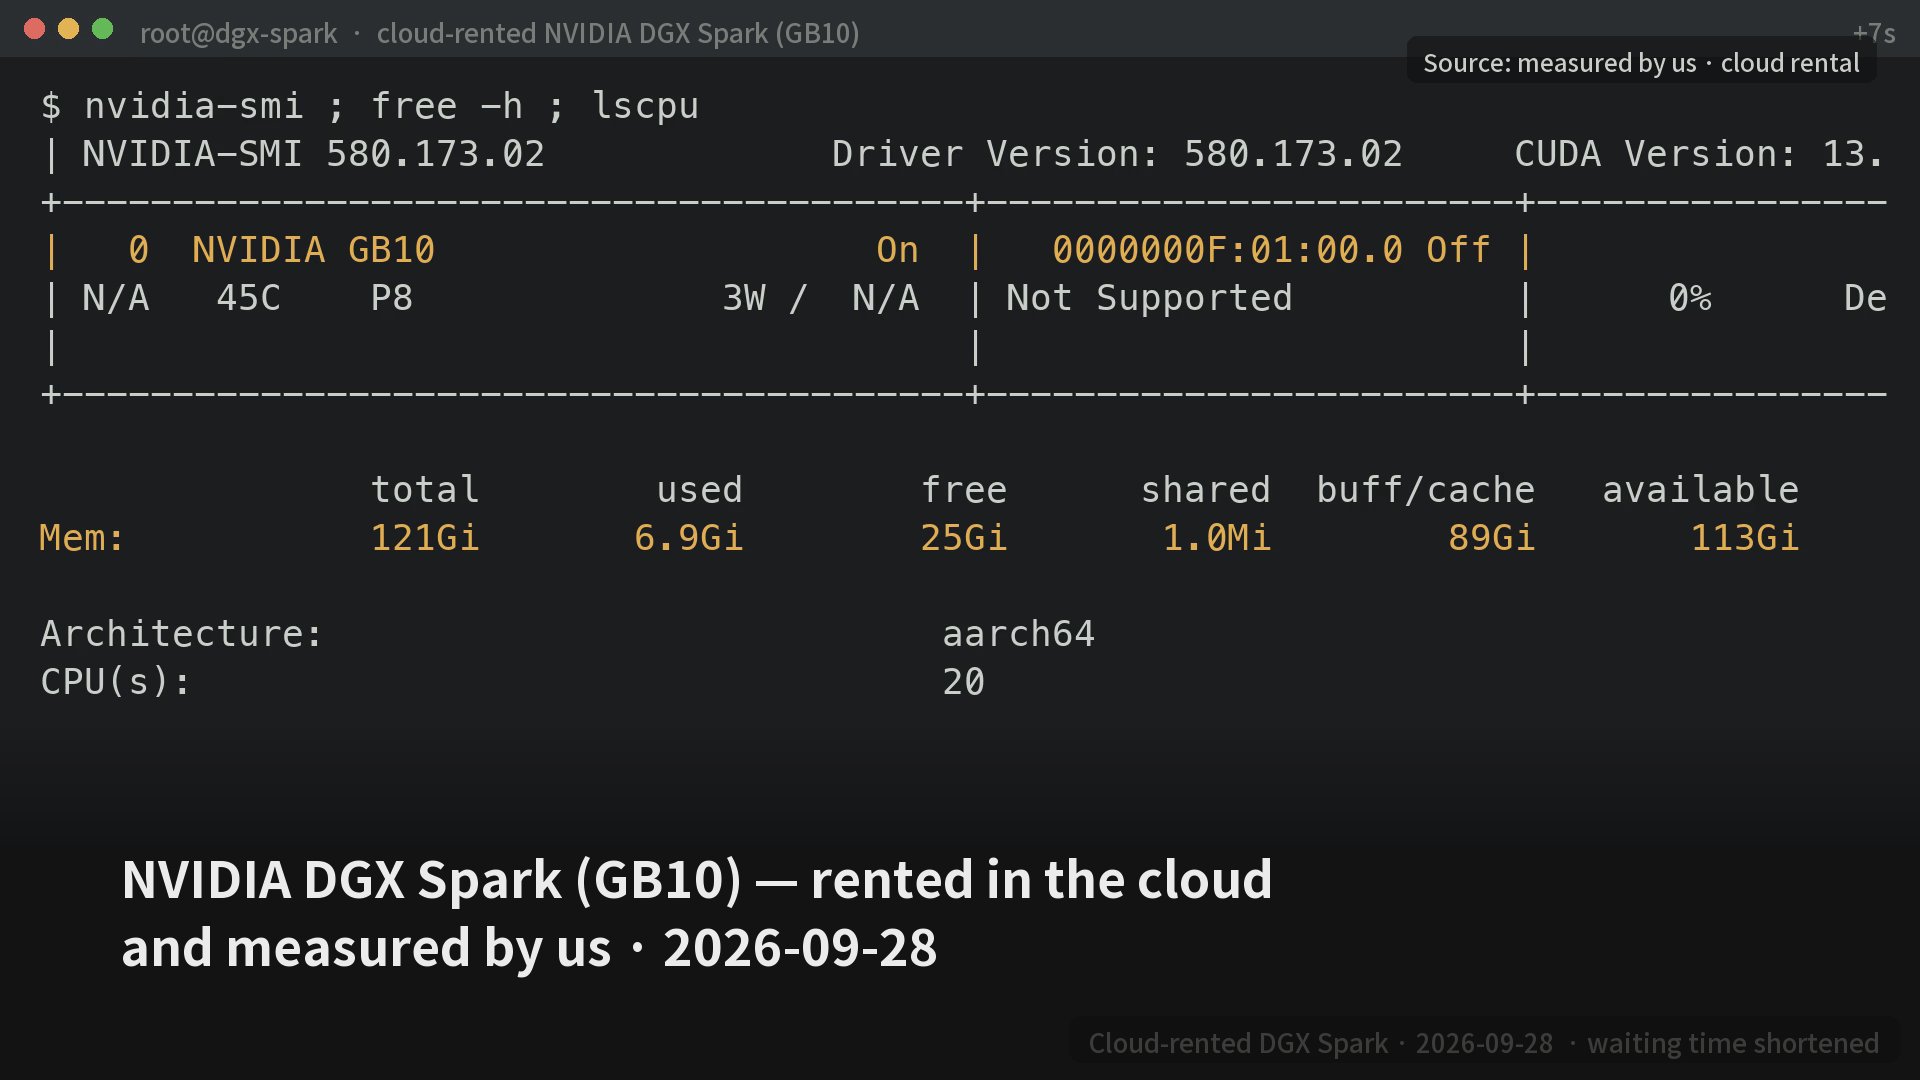
The DGX Spark we rented and measured: used by one person
On 2026-09-28 we rented a DGX Spark in the cloud (vast.ai) at $0.387 per hour. It shows 121GiB of memory and a 20-core ARM CPU.
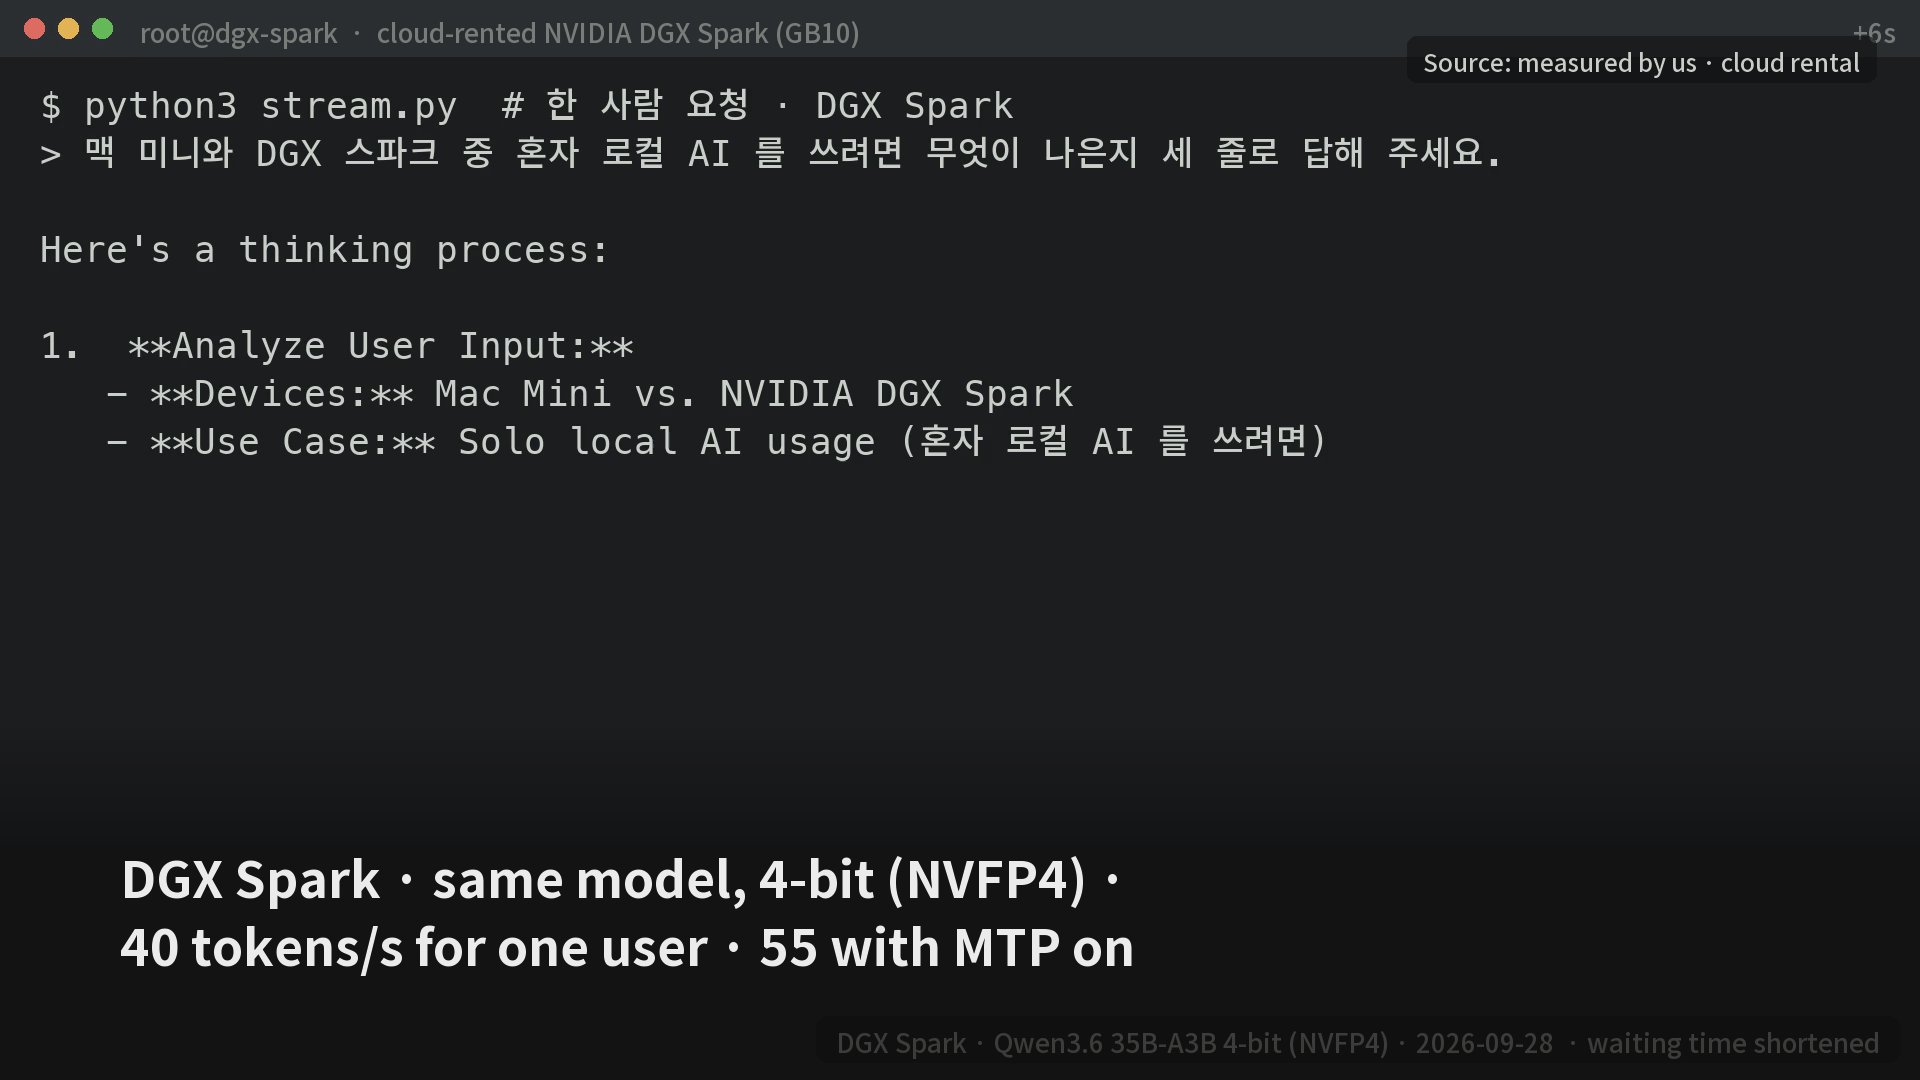
Today's popular models are MoE models: large overall, but computing only a part for each token. We measured the speed at which one user receives 300 tokens from Qwen3.6 35B-A3B 4-bit, cycling through the same 8 questions (measured by us).
| Configuration | Tokens/s for one user |
|---|---|
| Mac mini M6 32GB (MLX 4-bit) | 63.9 |
| DGX Spark (NVFP4) | 39.9 · 40.8 |
| DGX Spark + speculative decoding MTP | 54.1 · 55.3 |
On single-user speed alone, the DGX Spark did not beat the Mac mini. However, the 4-bit formats on the two sides differ (NVFP4 on the DGX, MLX 4-bit on the Mac). NVIDIA's official NVFP4 file threw a loading error in the vLLM version we used, so we used the RedHatAI version. A rented server may differ from a retail unit in power and settings.
The real use of 128GB: a big model, whole
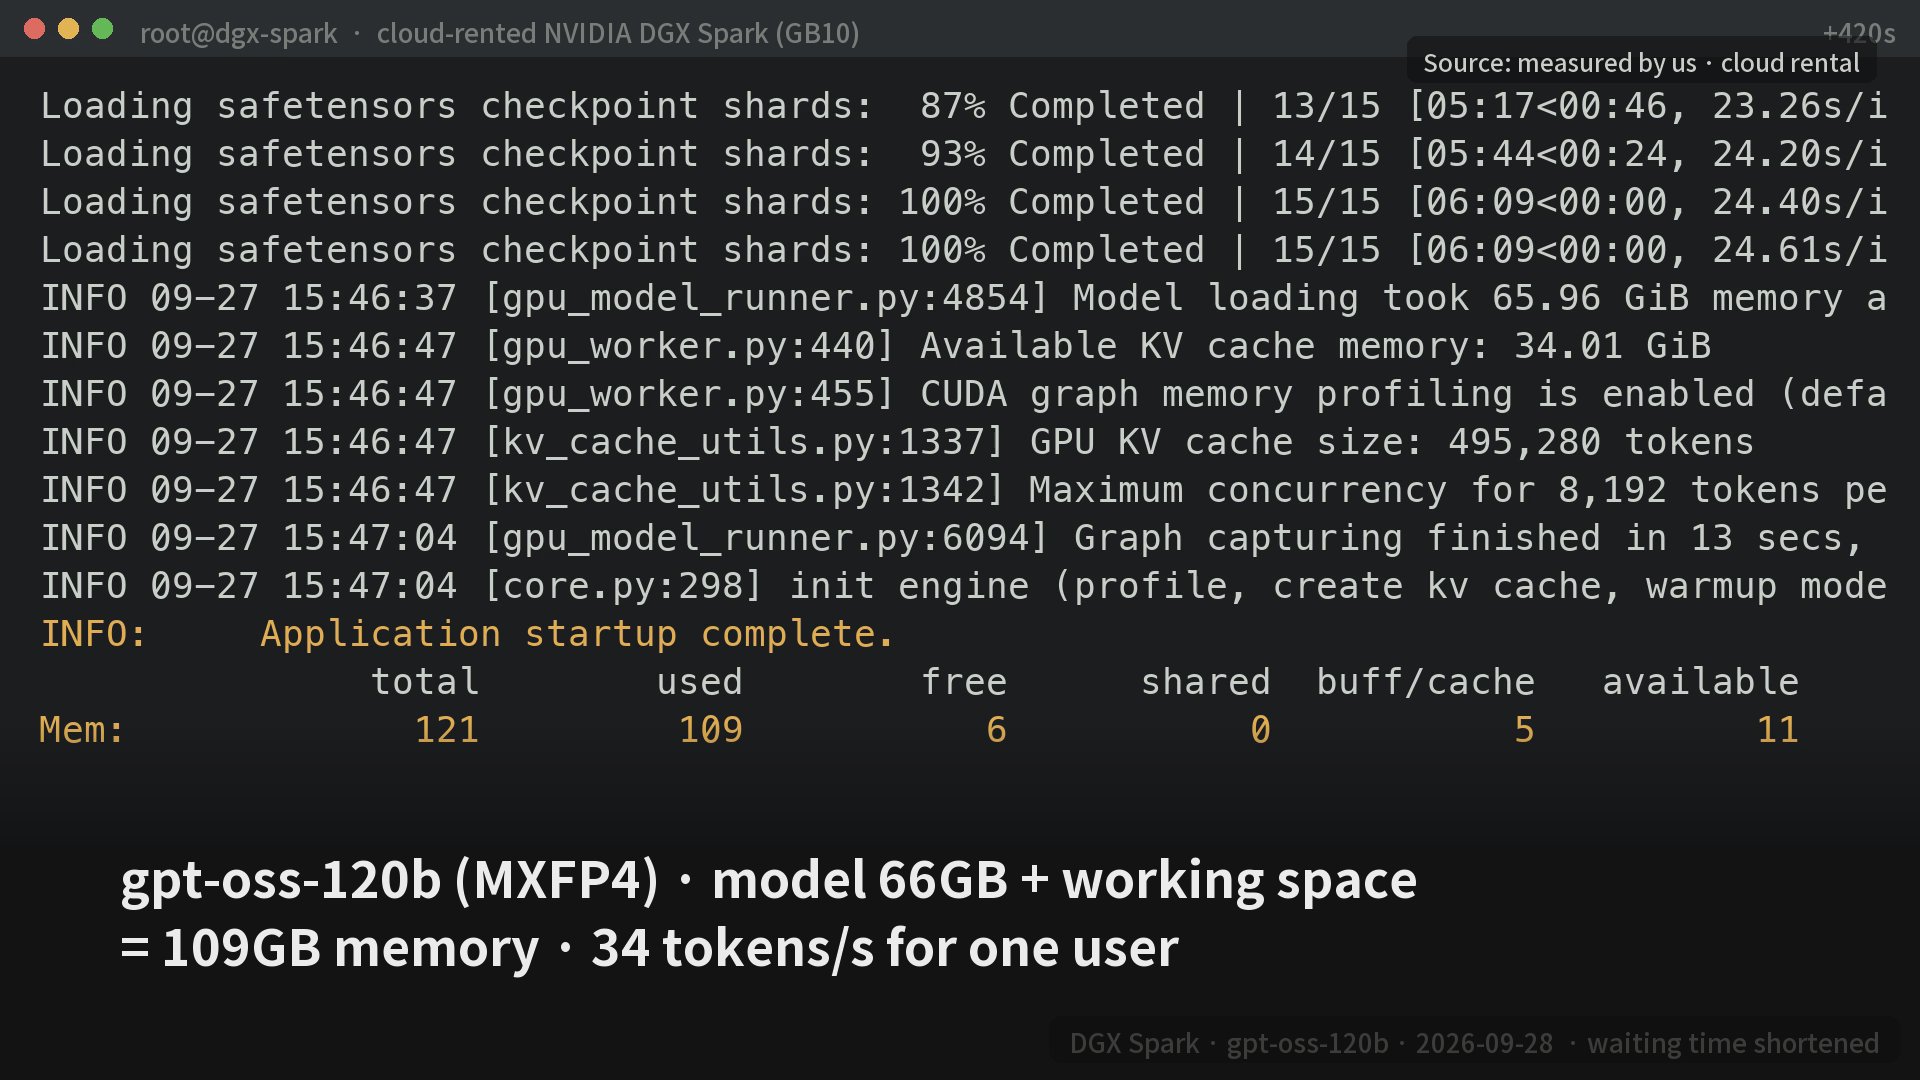
The 120-billion-parameter gpt-oss-120b (MXFP4) took 109GiB of memory (out of 121GiB in total), about 66GiB for the model plus working space, and produced 34.3 tokens/s for one user (measured by us, close to Dendro Logic's published 33.5). It is a model that does not fit on a 32GB Mac mini.
With simultaneous users, the result flips
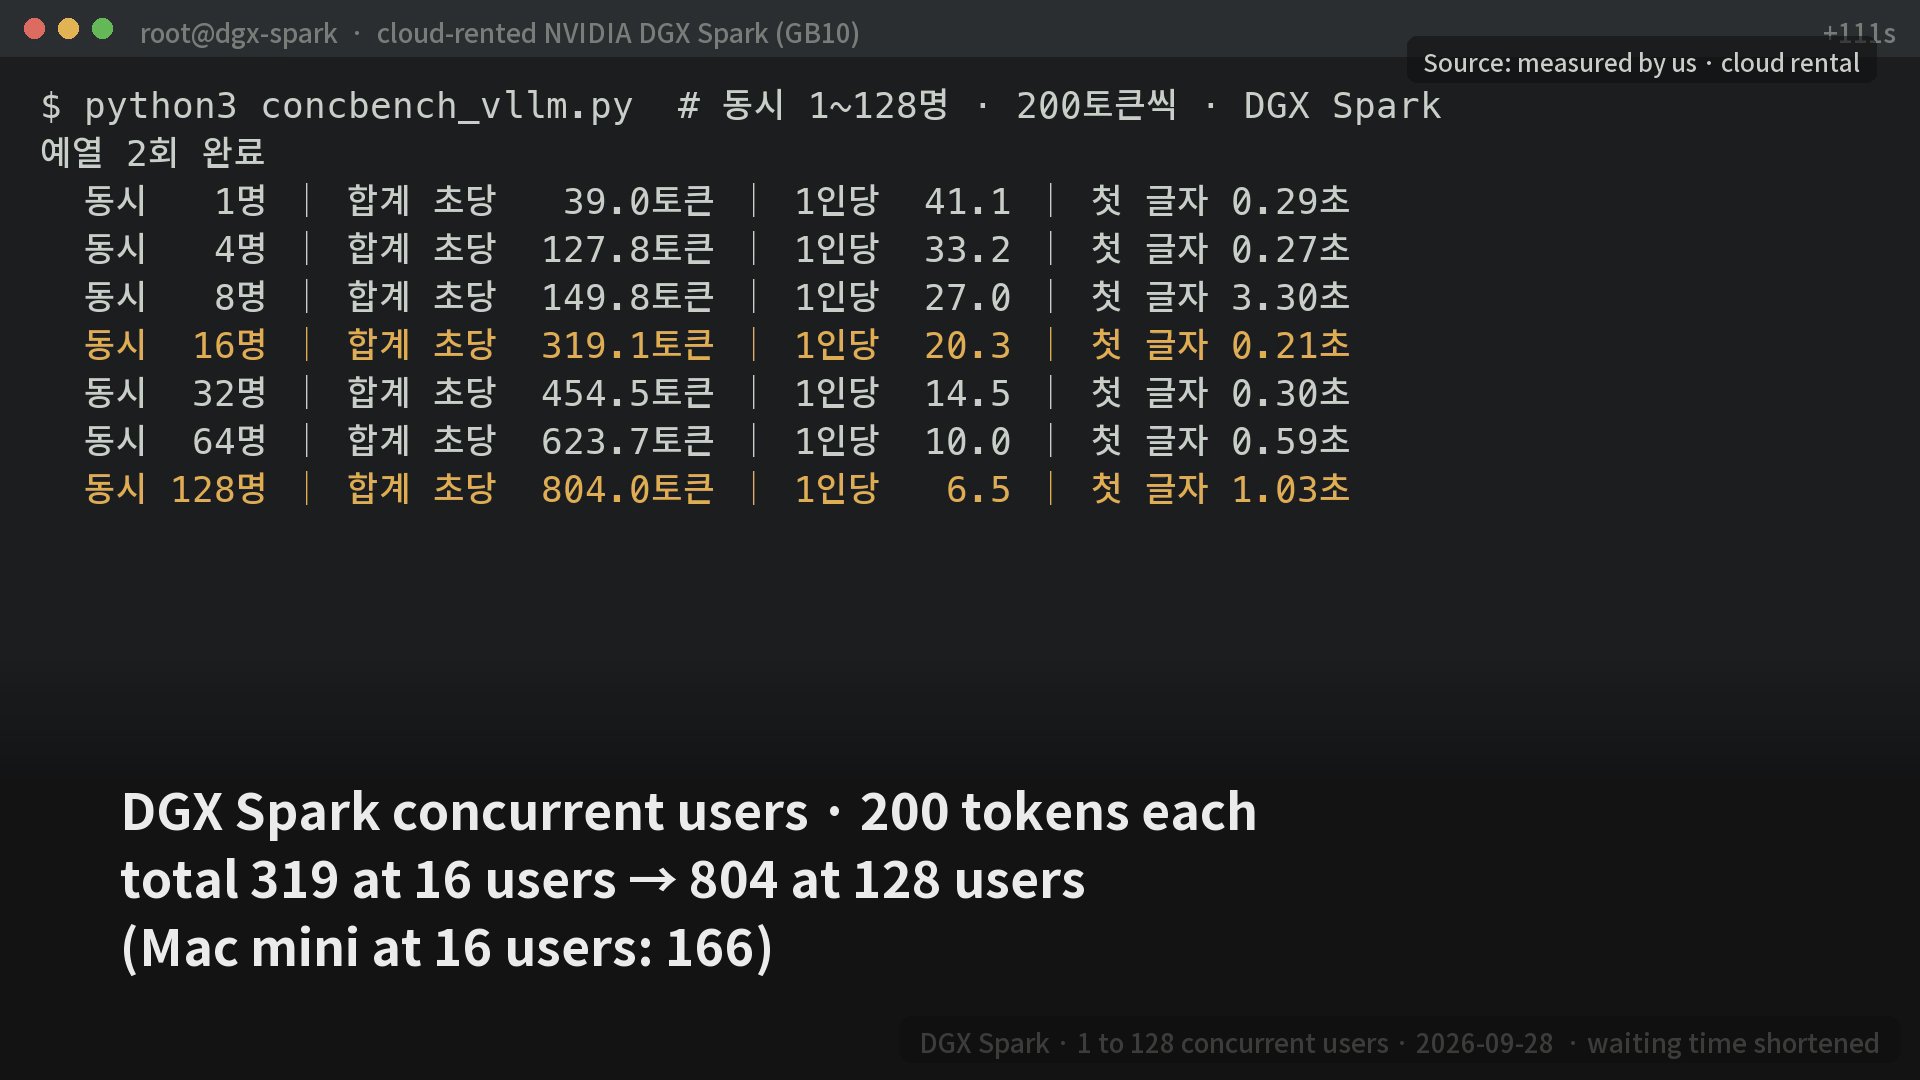
We sent requests from 1 to 128 users at the same time, 200 tokens per request, to the same model. Each cell shows "total · per-user median" (tokens/s, measured by us), and the DGX values are with MTP off.
| Concurrent users | DGX Spark | Mac mini M6 32GB |
|---|---|---|
| 1 user | 39.0 · 41.1 | 62.4 · 64.6 |
| 4 users | 127.8 · 33.2 | 123.2 · 34.0 |
| 8 users | 149.8 · 27.0 | 150.0 · 20.7 |
| 16 users | 319.1 · 20.3 | 165.7 · 11.8 |
| 32 users | 454.5 · 14.5 | Not measured |
| 64 users | 623.7 · 10.0 | Not measured |
| 128 users | 804.0 · 6.5 | Not measured |
At 1 user the Mac mini is about 1.6x ahead (62.4÷39.0; calculated), at 4 and 8 users the totals are nearly the same, and at 16 users the DGX Spark is about 1.9x ahead (319.1÷165.7; calculated). The DGX value in the 1-user row (39.0 · 41.1) differs from the 39.9 · 40.8 in the table above because the tool and the length differ. The table above is from a 300-token demo request measured twice in a row. This table gives the total for 200-token requests (divided over the time including the wait for the first character) and the per-user median (speed after characters start appearing). We measured the Mac mini only up to 16 users, so we do not know beyond that.
How to choose, in order
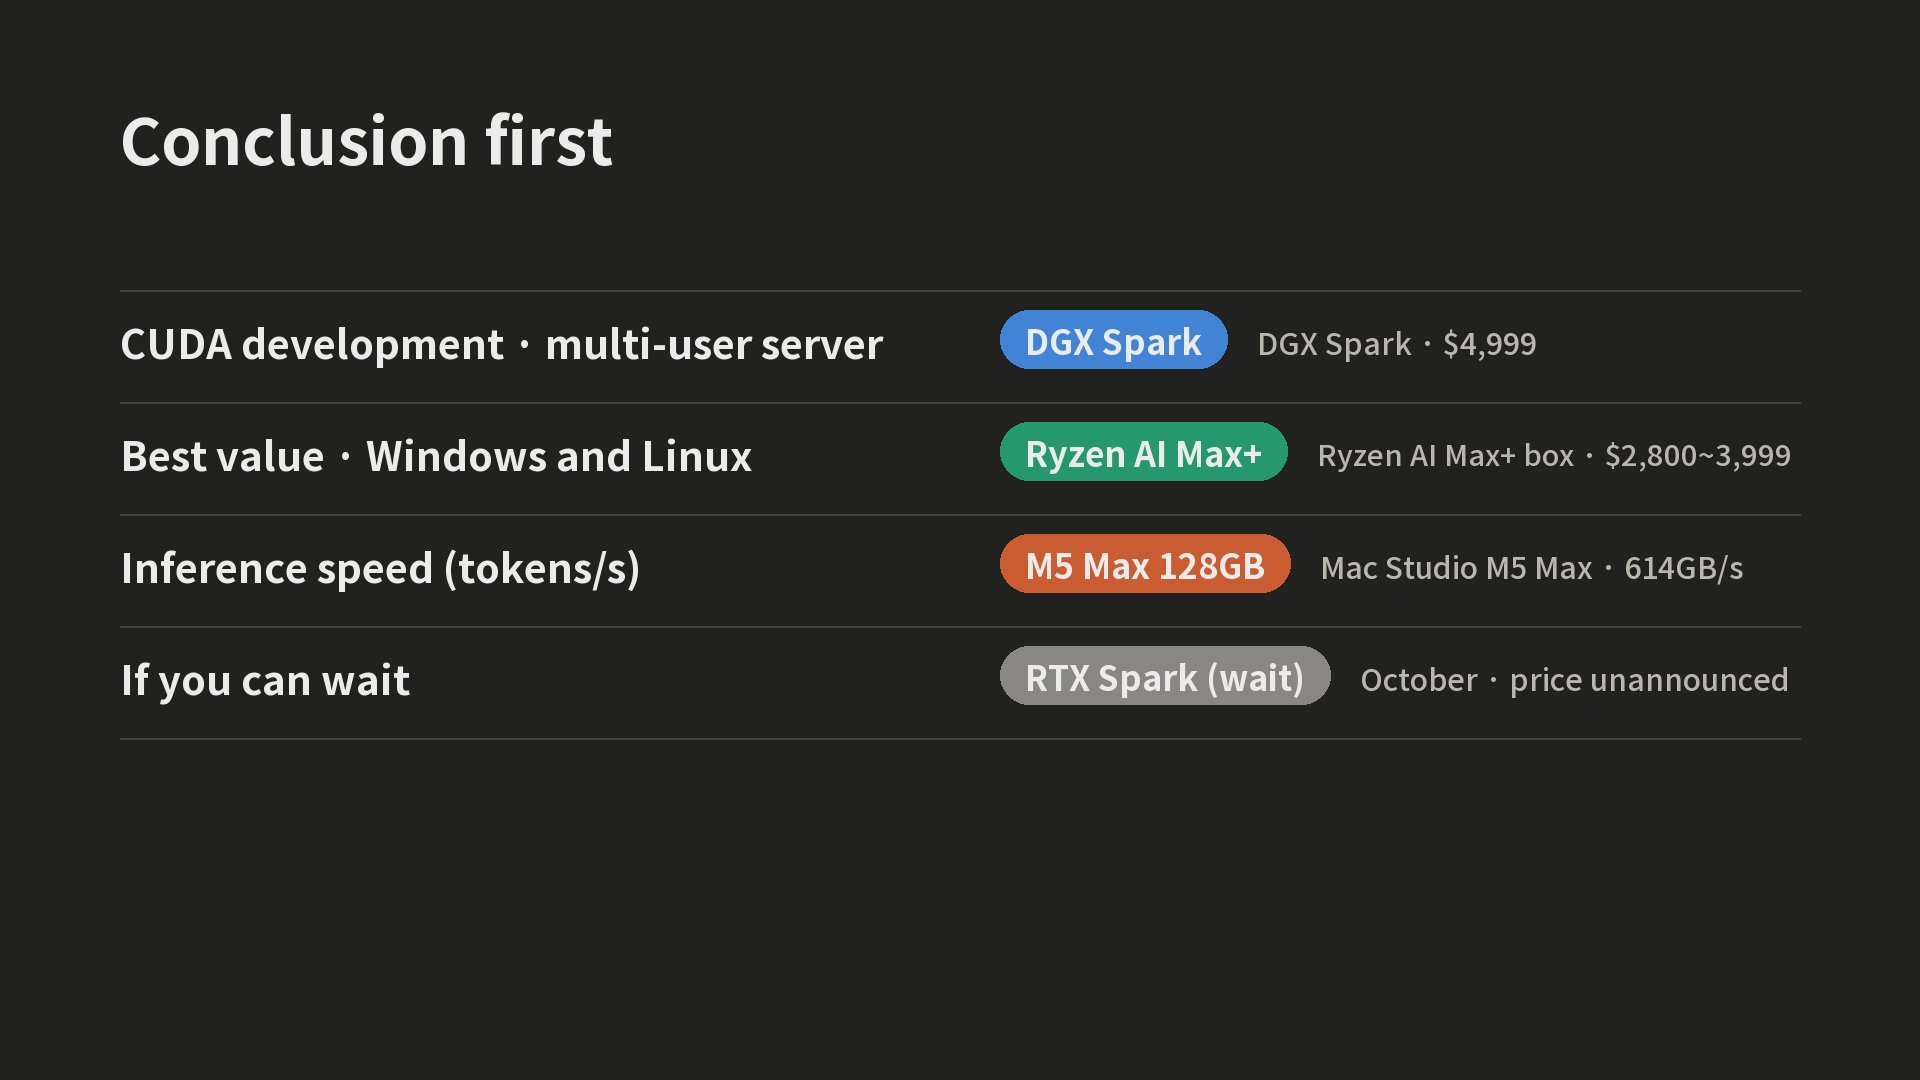
- CUDA development or a server several people use: the DGX Spark.
- Price, and both Windows and Linux: the cheapest Ryzen AI Max+ box. It is the same chip, so speed is the same, and the differences are cooling, ports and warranty.
- Single-user inference speed as the goal: the Mac Studio M5 Max, which has high bandwidth. But this is a judgment based on specs we did not measure.
- If you can wait: check the price and compatibility of the RTX Spark, which was unannounced at the time of the video (it is Windows on Arm, so check compatibility after launch).
The video also raised three points before buying. The GPU cannot use all 128GB (about 75% on a Mac, and a configured limit on the other boxes). Rising RAM prices were said to have pushed prices of these boxes up 40 to 65% in a year (cited from the video). If solo chat is the goal, a subscription is still cheaper.
Test conditions and what we did not measure
Conditions (2026-09-28). DGX Spark: vast.ai rental · vLLM 0.19.2rc1 · max length 8192 · KV fp8. Mac mini: mlx_lm 0.31.3 · mlx-community 4-bit. 8 questions in rotation, 200 tokens per request, and 300 for the single user.
What we did not measure. 70B dense models, the Ryzen AI Max+ box, the RTX Spark, and the Mac Studio M5 Max (all specs, estimates and citations), Mac mini at 17 or more users, power and noise, and answer quality.
Sources and reference date. Measured 2026-09-28. Prices 2026-09-27: pi3g DGX Spark price list, TweakTown (2026-06-14), TerminalBytes (2026-05), Morgan Stanley estimate (from the channel's RTX Spark roundup), Apple Newsroom 2026-08-25, Tom's Hardware M5 Ultra review.
This article is based on a video narrated with an AI voice, and AI assisted the writing. It is for information only and is not a purchase recommendation.